Natural Language UnderstandingTransformer
Natural Language
Understanding
Transformer
Understanding
Transformer
Mingming Sun
BIMSA
Outline
Outline
Background
Transformer Overview
Transformer Block
Transformer Architecture
Challenges and Solutions
2.2 Transformer 2.2.1 Background: Neural Machine Translation and RNNs
2.2 Transformer 2.2.1 Background: Neural Machine Translation and RNNs
Machine Translation
Machine Translation
Machine Translation (MT) is the task of translating a sentence from one language (the source language) to a sentence in another language (the target language).
x: L'homme est né libre, et partout il est dans les fers
y: Man is born free, but everywhere he is in chains
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
History
History
Early Stage (1950s): Basically just simple rule-based systems doing word substitution. Problem soon appeared intractable.
Statistical Machine Translation (1990s-2010s):
Learn a probabilistic model from data:
The best systems were extremely complex, with many separately-designed subcomponents, which requires lots of feature engineering and lots of human effort to maintain
Neural Machine Translation (2010s-)
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
Neural Machine Translation
Neural Machine Translation
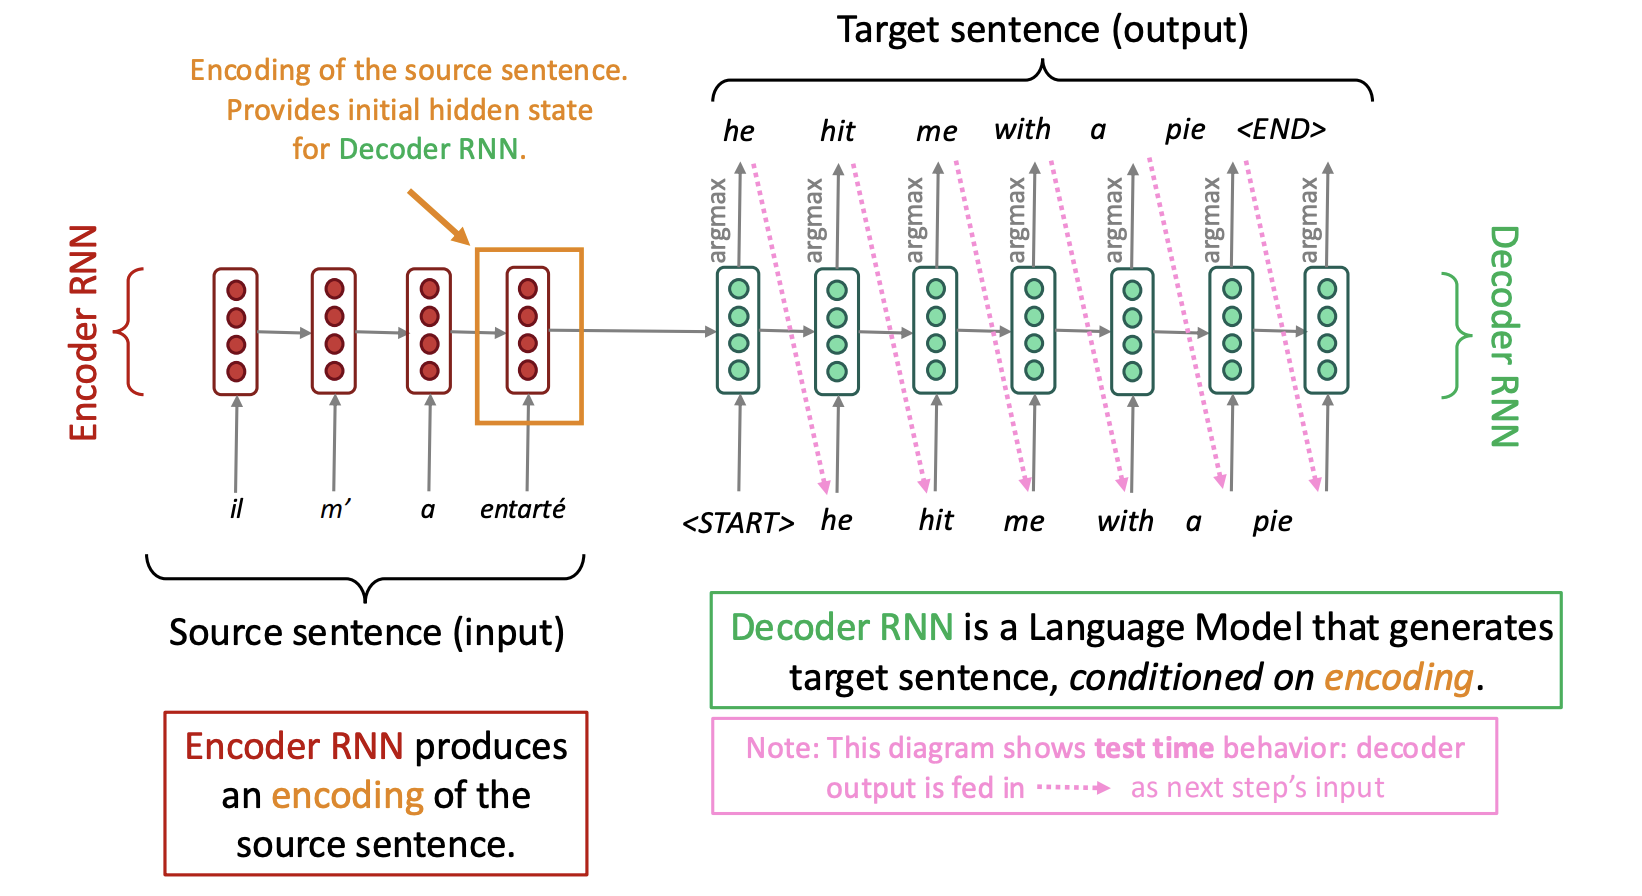
In 2014, Ilya Sutskever applied Sequence to Sequence RNN model to MT, starting the NMT.
NMT learns a Conditional Language Model :
Language Model: the decoder is predicting the next word of the target sentence
Conditional: its predictions are also conditioned on the source sentence
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
Sequence to Sequence RNN
Sequence to Sequence RNN
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
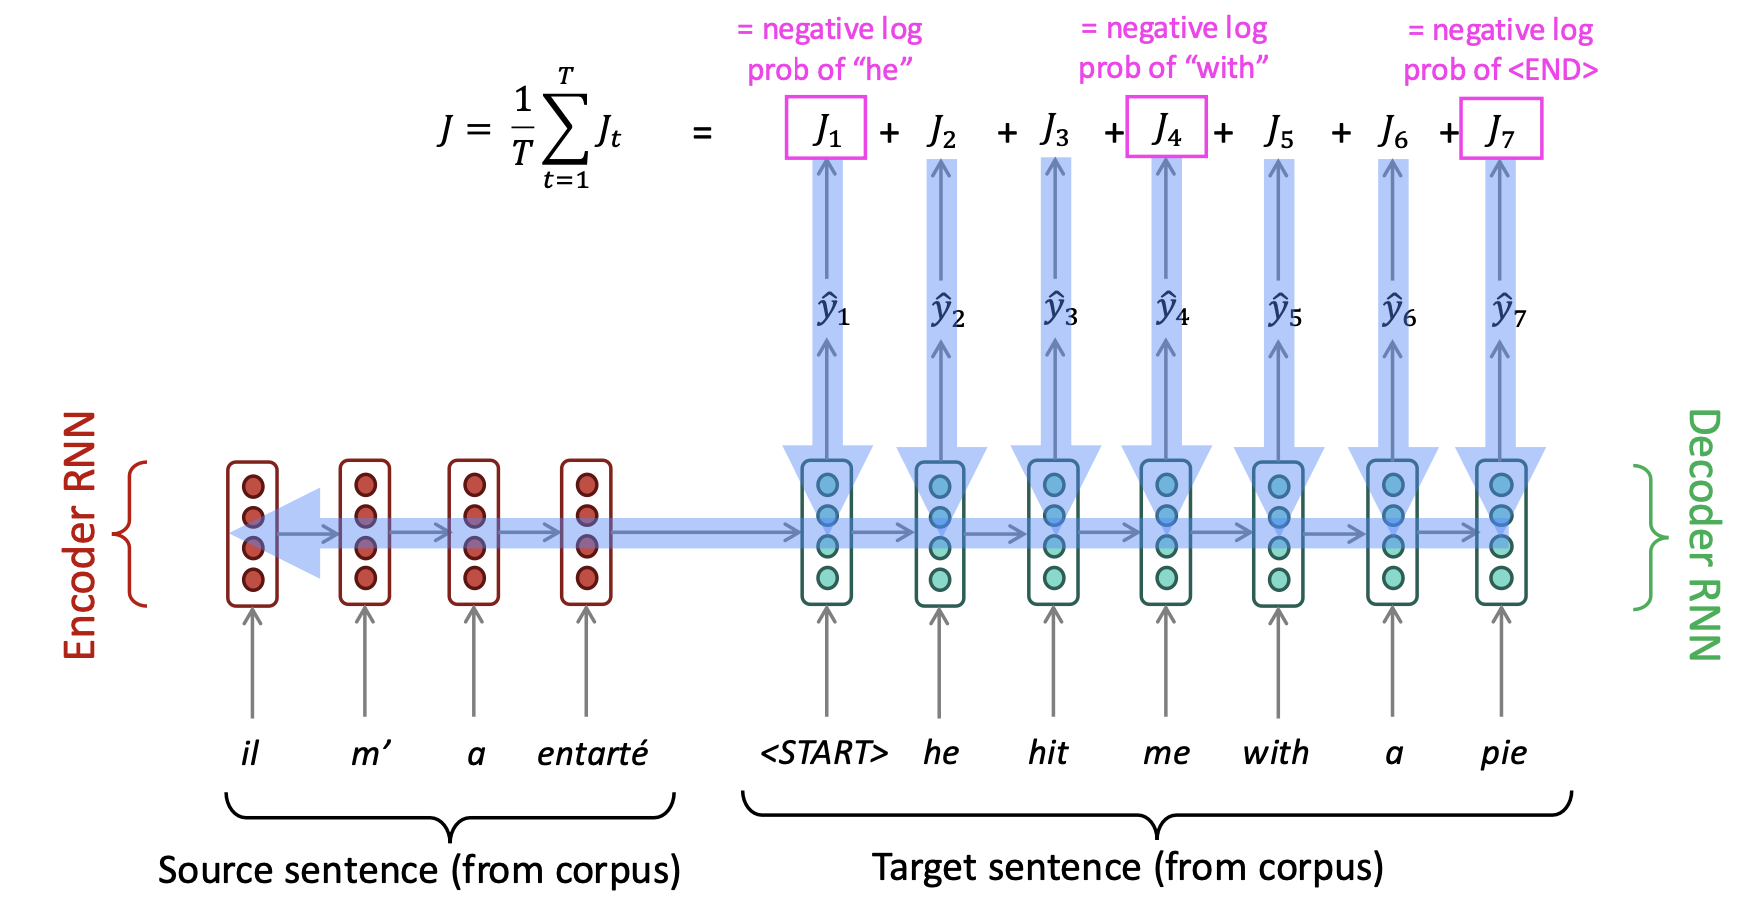
Training the System
Training the System
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
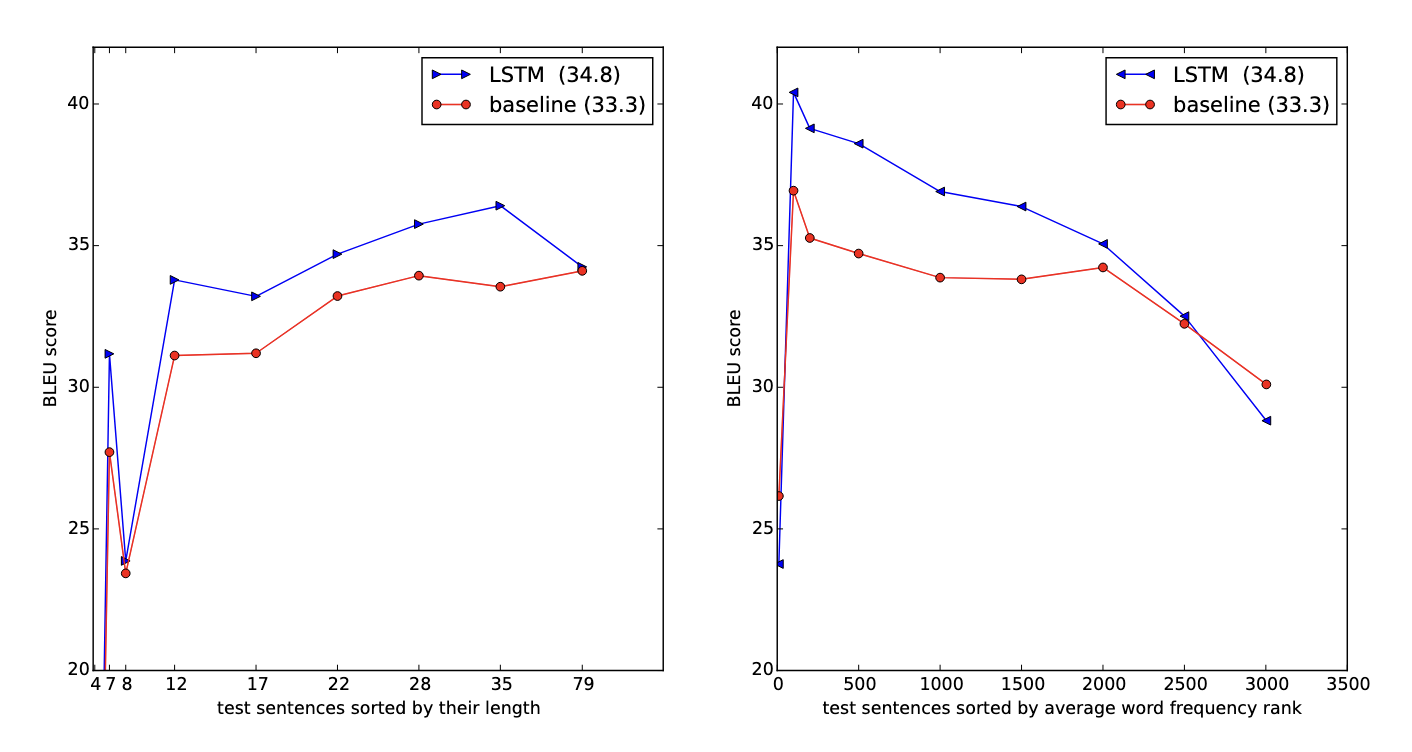
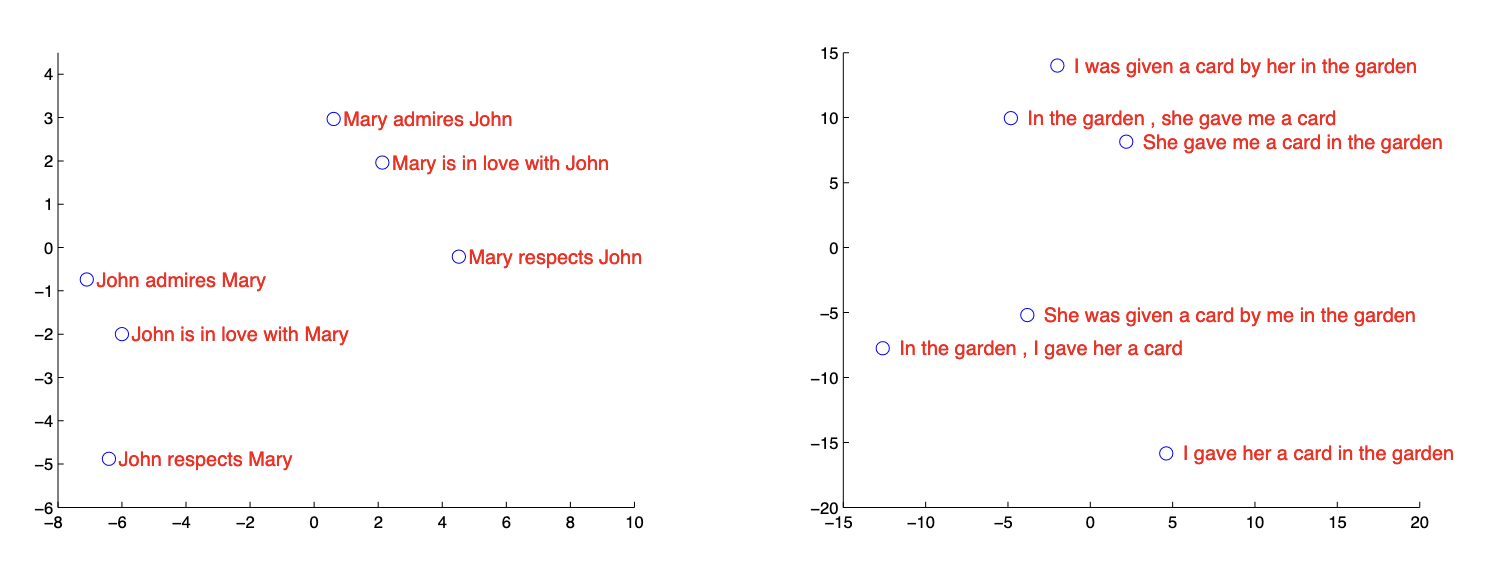
Sequence to Sequence Learning in NMT
Sequence to Sequence Learning in NMT
Sutskever, I., Vinyals, O. & Le, Q. V. Sequence to Sequence Learning with Neural Networks.
Bottlenecks
Bottlenecks
Does the architecture limit the learning ability?
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
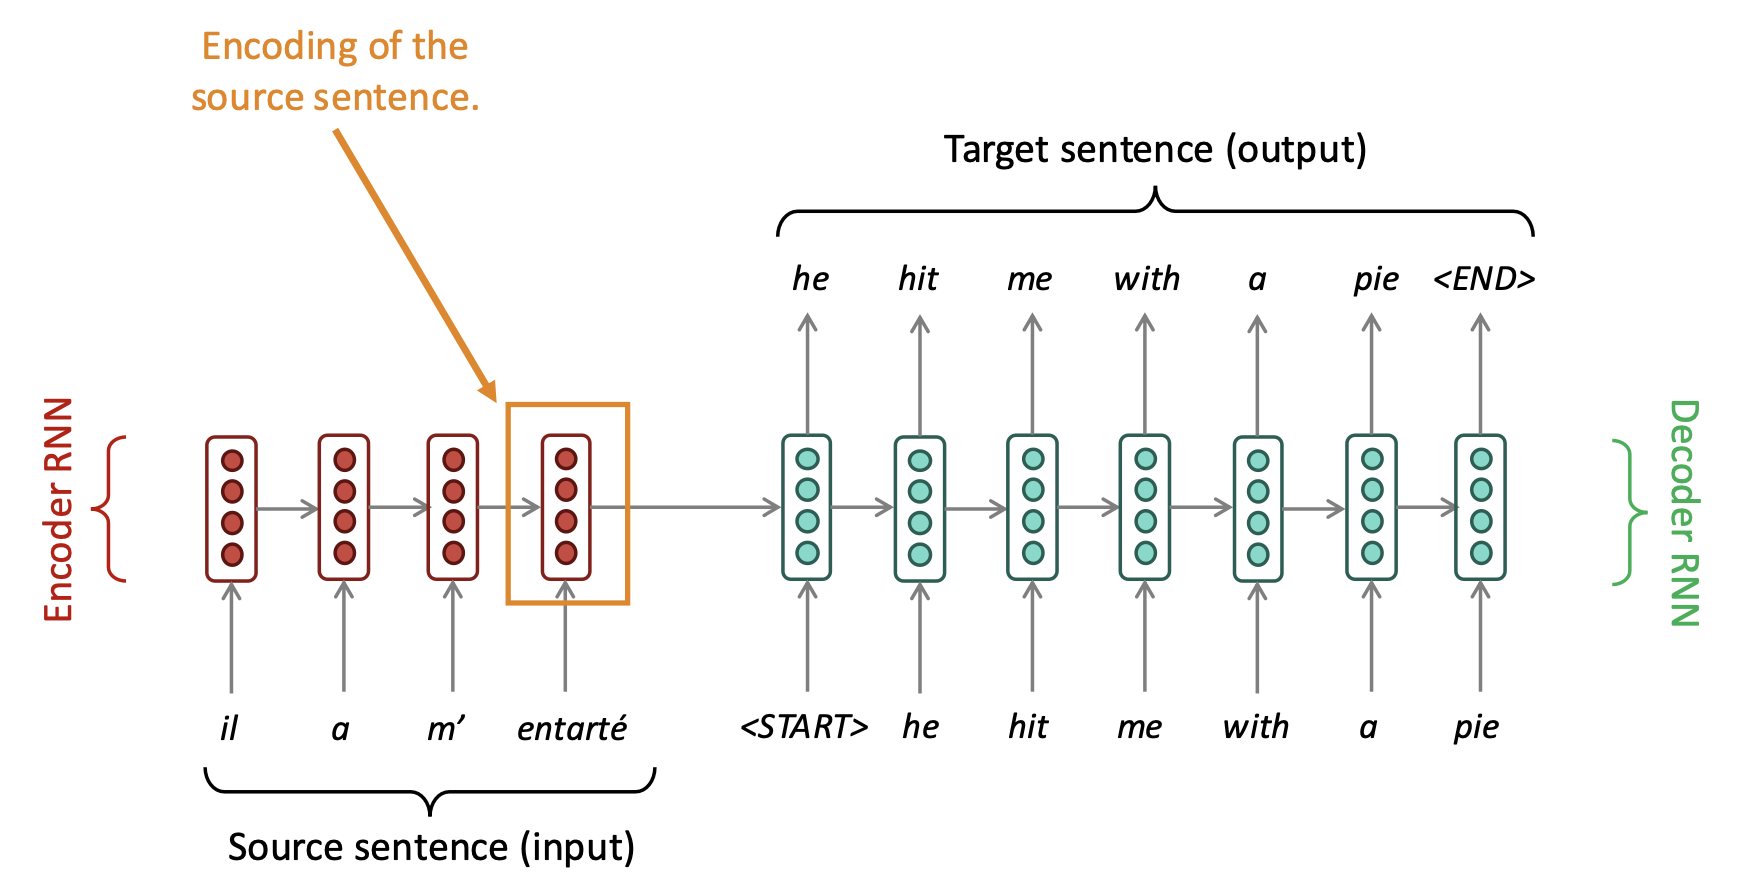
Limitations: Linear Interaction Distance
Limitations: Linear Interaction Distance
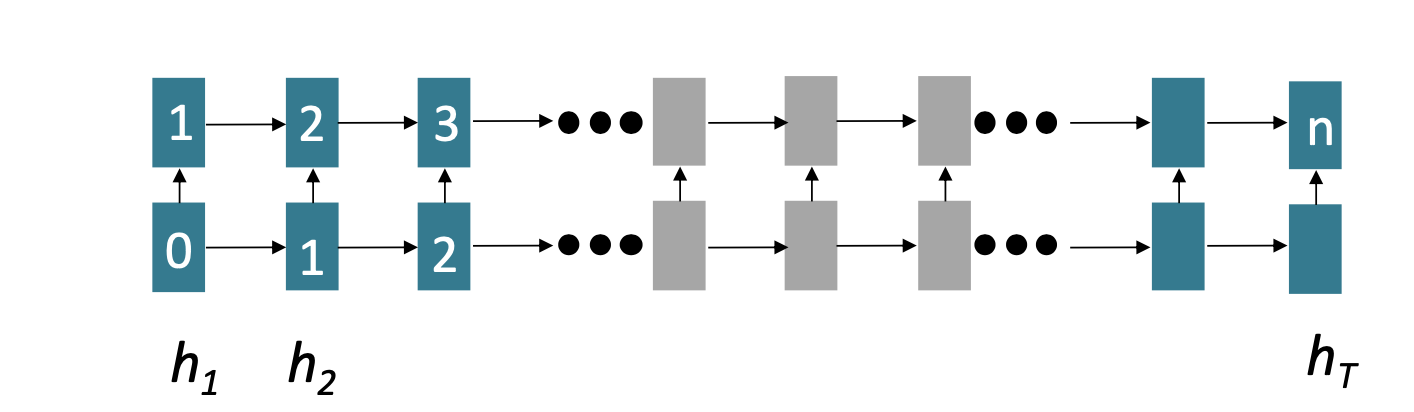
O(sequence length) steps for distant word pairs to interact means:
Hard to learn long-distance dependencies (because gradient problems!)
Linear order of words is “baked in”; we already know linear order isn’t the right way to think about sentences…
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
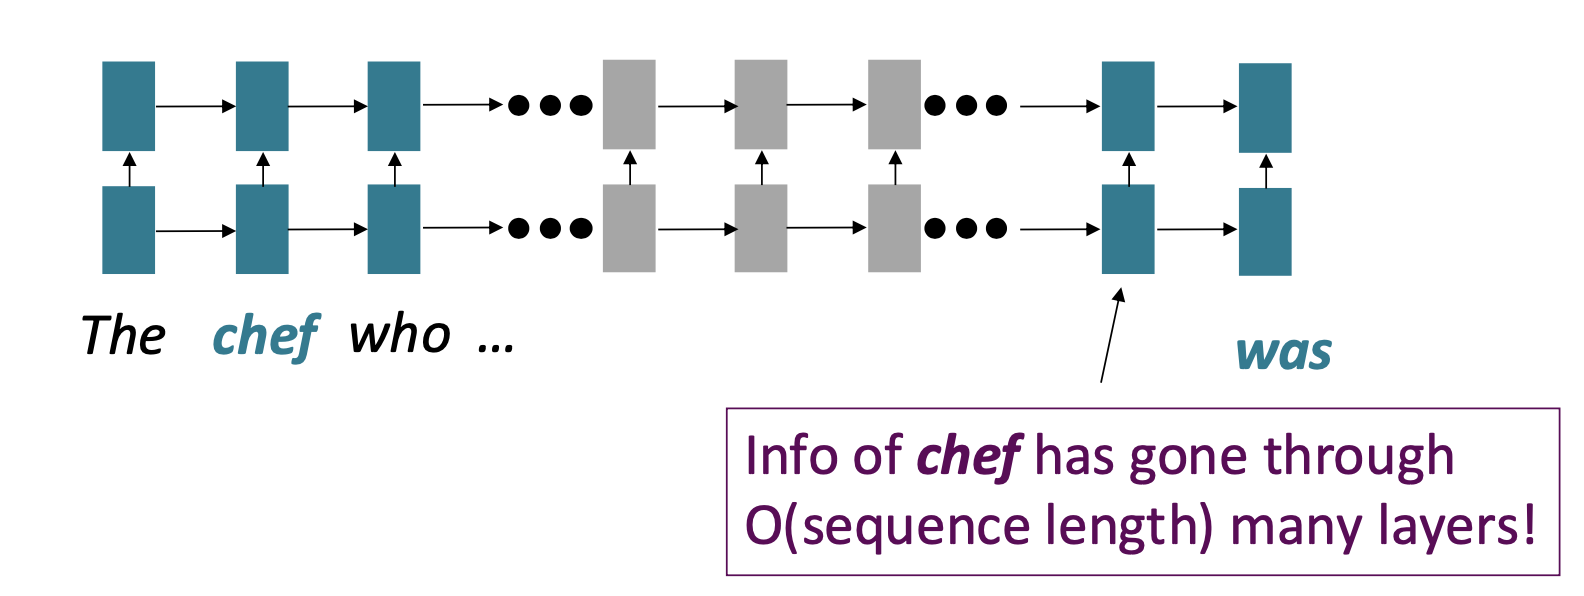
Limitations: Lack of Parallelizability
Limitations: Lack of Parallelizability
Forward/backward have O(sequence length) unparallelizable operations
Inhibits training on very large datasets!
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
2.2 Transformer 2.2.2 Background: Attention
2.2 Transformer 2.2.2 Background: Attention
Attention: Core Idea
Attention: Core Idea
Attention provides a solution to above limitations
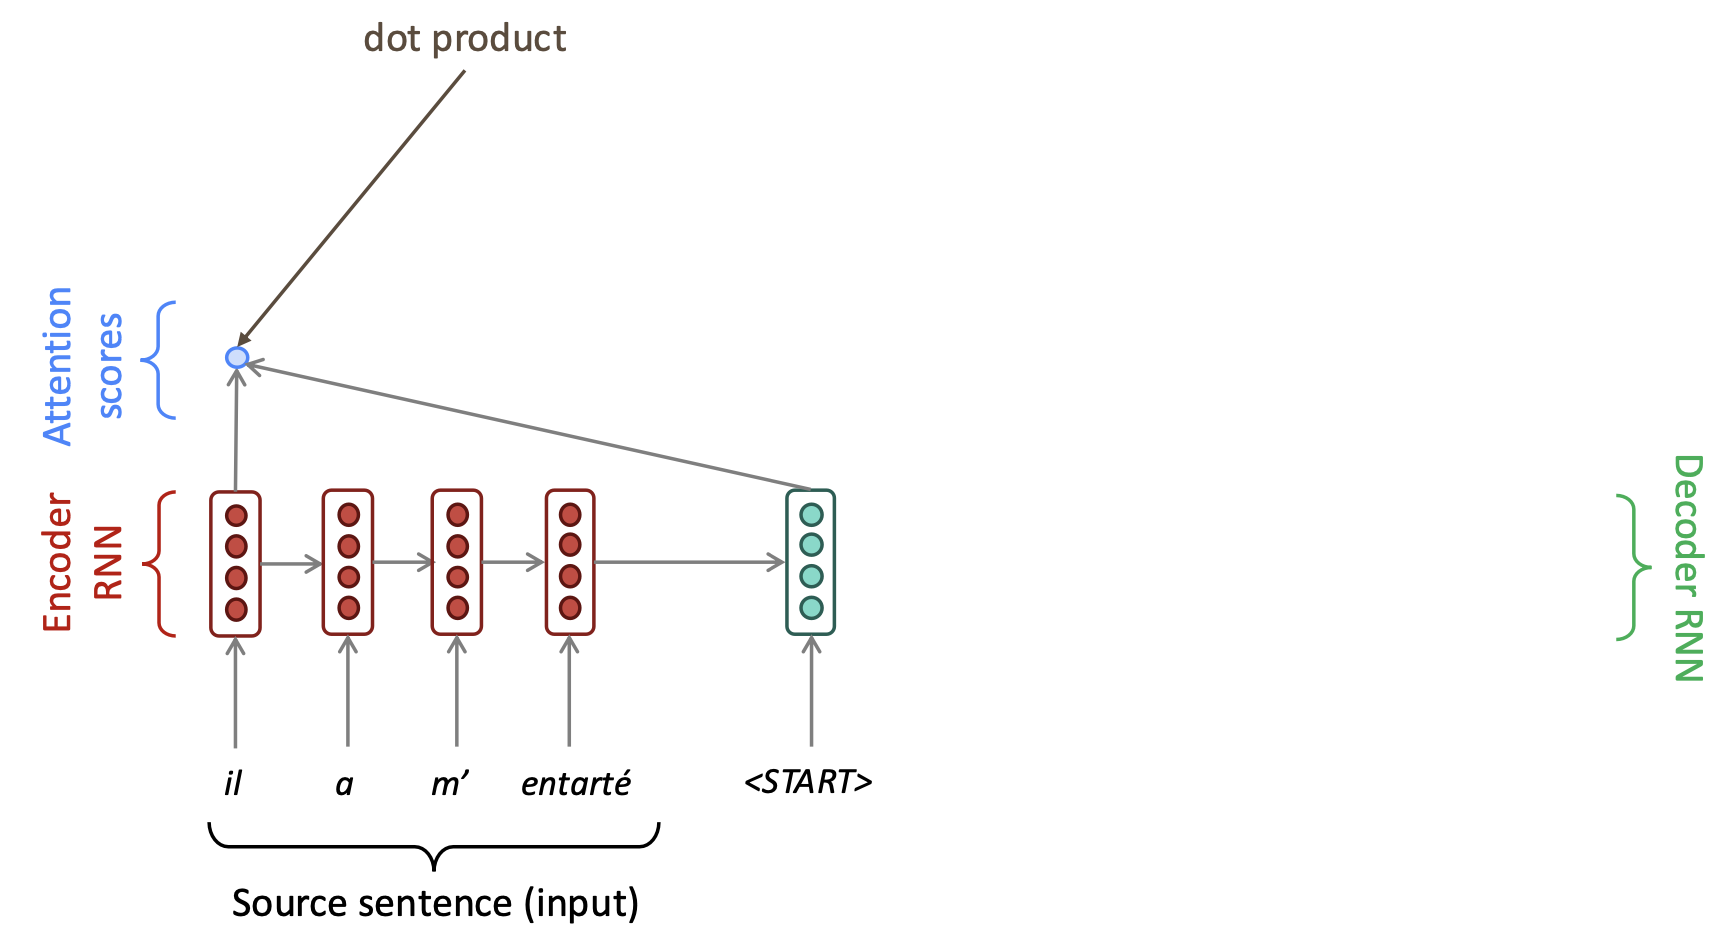
On each step of the decoder, use direct connection to the encoder to focus on a particular part of the source sequence.
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
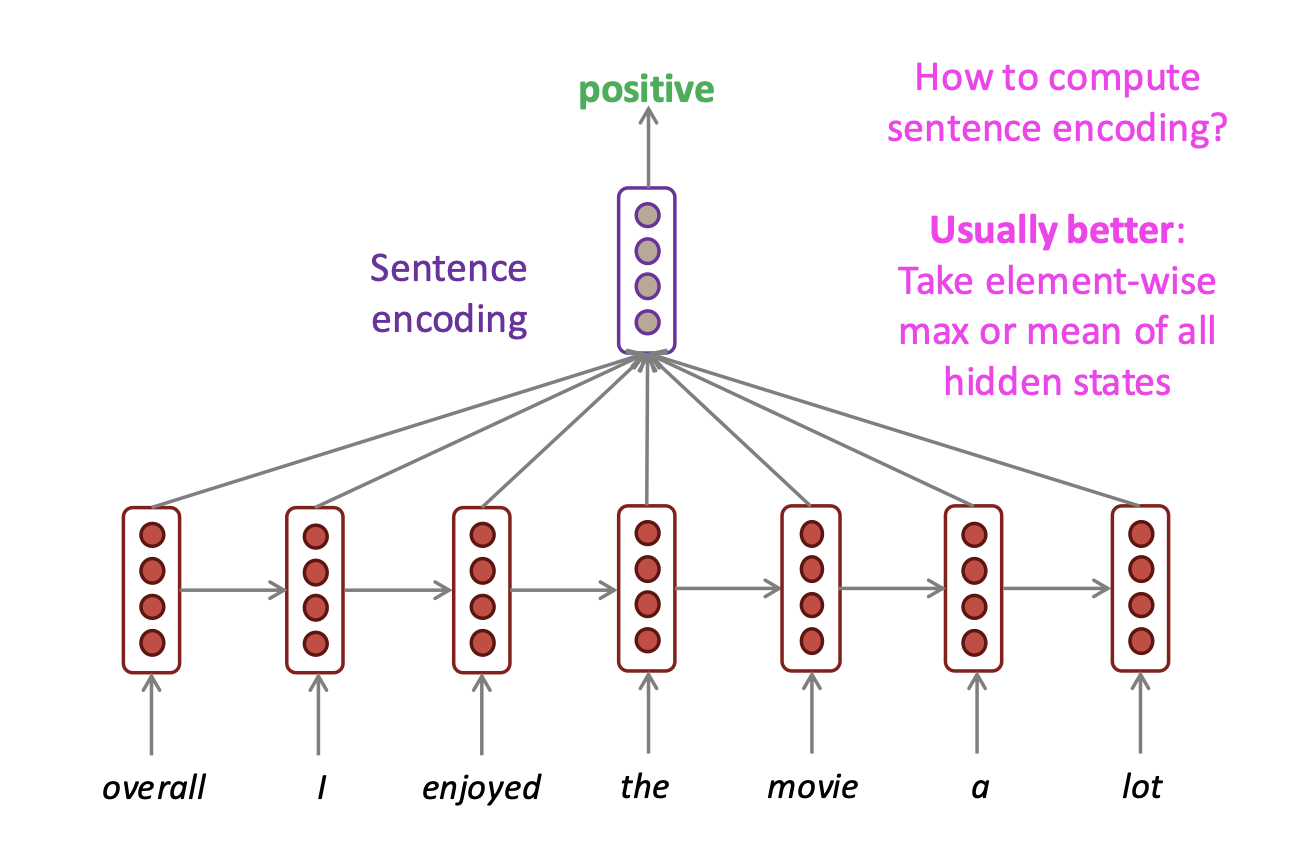
Starting from Meaning-Pooling for RNNs
Starting from Meaning-Pooling for RNNs
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
Attention is weighted averaging
Attention is weighted averaging
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
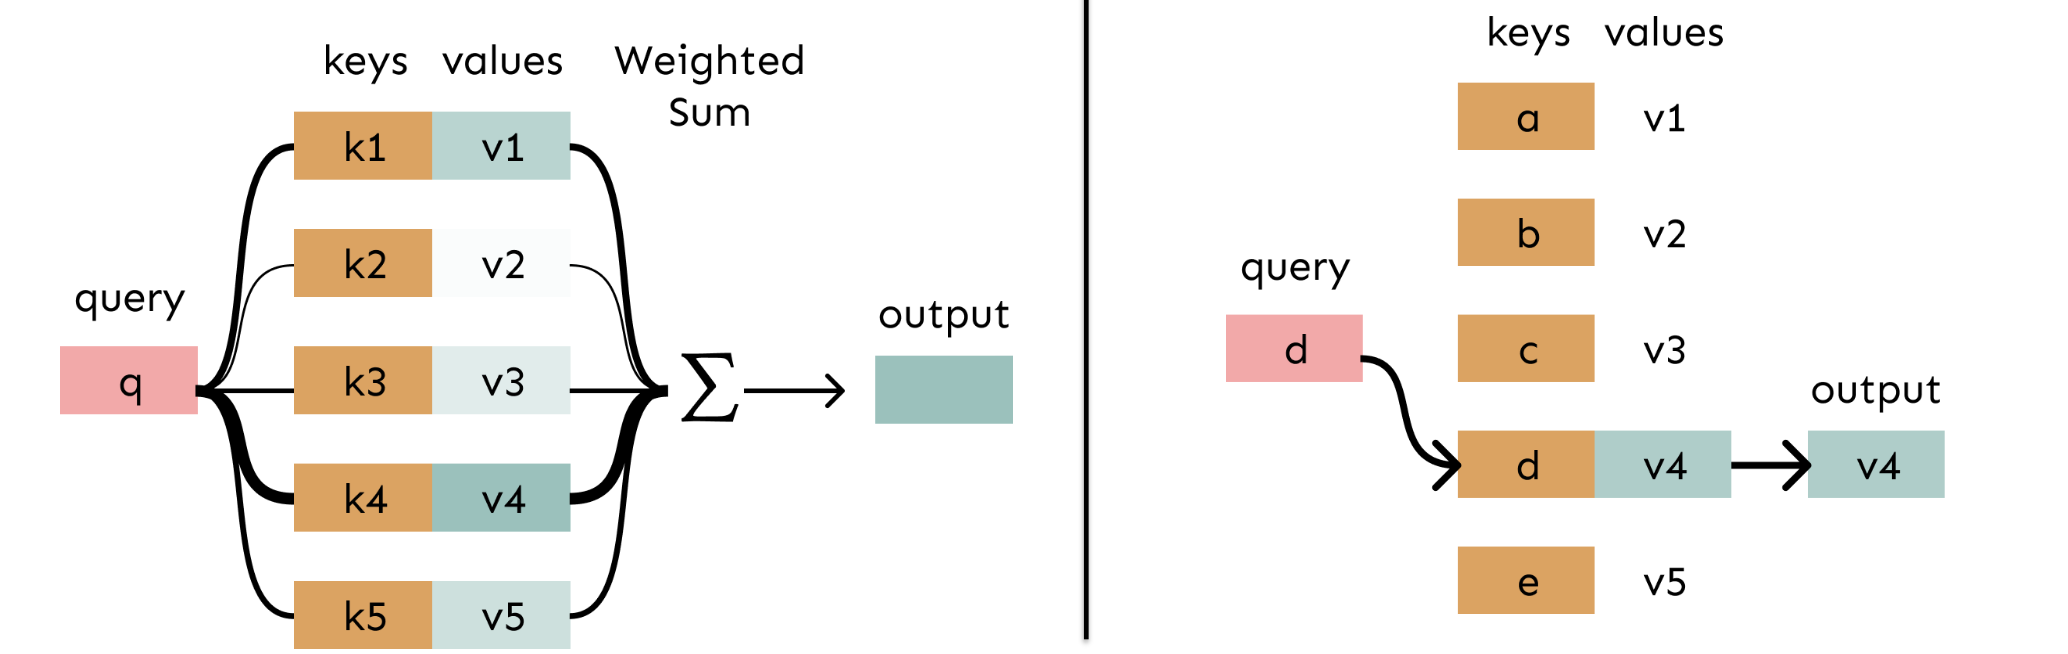
In attention, the query matches all keys softly,
to a weight between 0 and 1. The keys’ values
are multiplied by the weights and summed.
In a lookup table, we have a table of keys that map to values. The query matches one of the keys, returning its value.
Sequence-to-Sequence With Attention
Sequence-to-Sequence With Attention
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
Core Idea: use direct connection to the encoder to focus on a particular part of the source sequence.
Sequence-to-Sequence With Attention
Sequence-to-Sequence With Attention
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
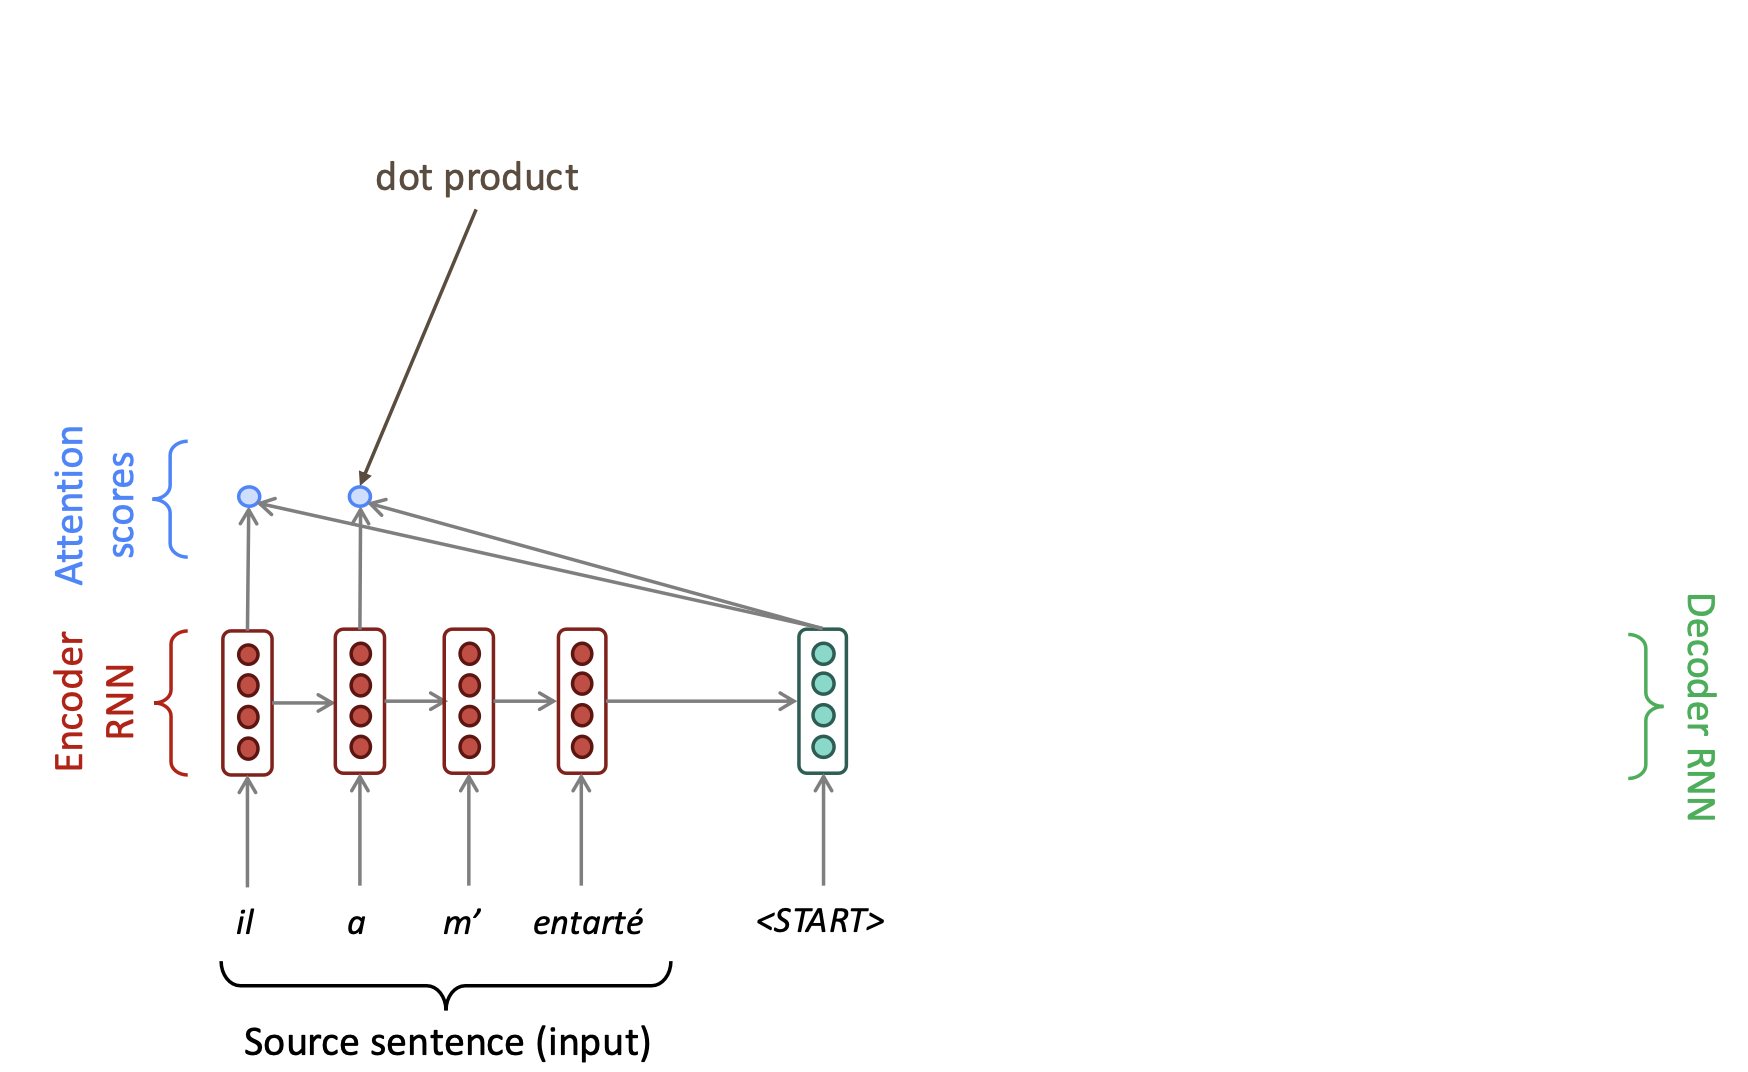
Core Idea: use direct connection to the encoder to focus on a particular part of the source sequence.
Sequence-to-Sequence With Attention
Sequence-to-Sequence With Attention
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
Core Idea: use direct connection to the encoder to focus on a particular part of the source sequence.
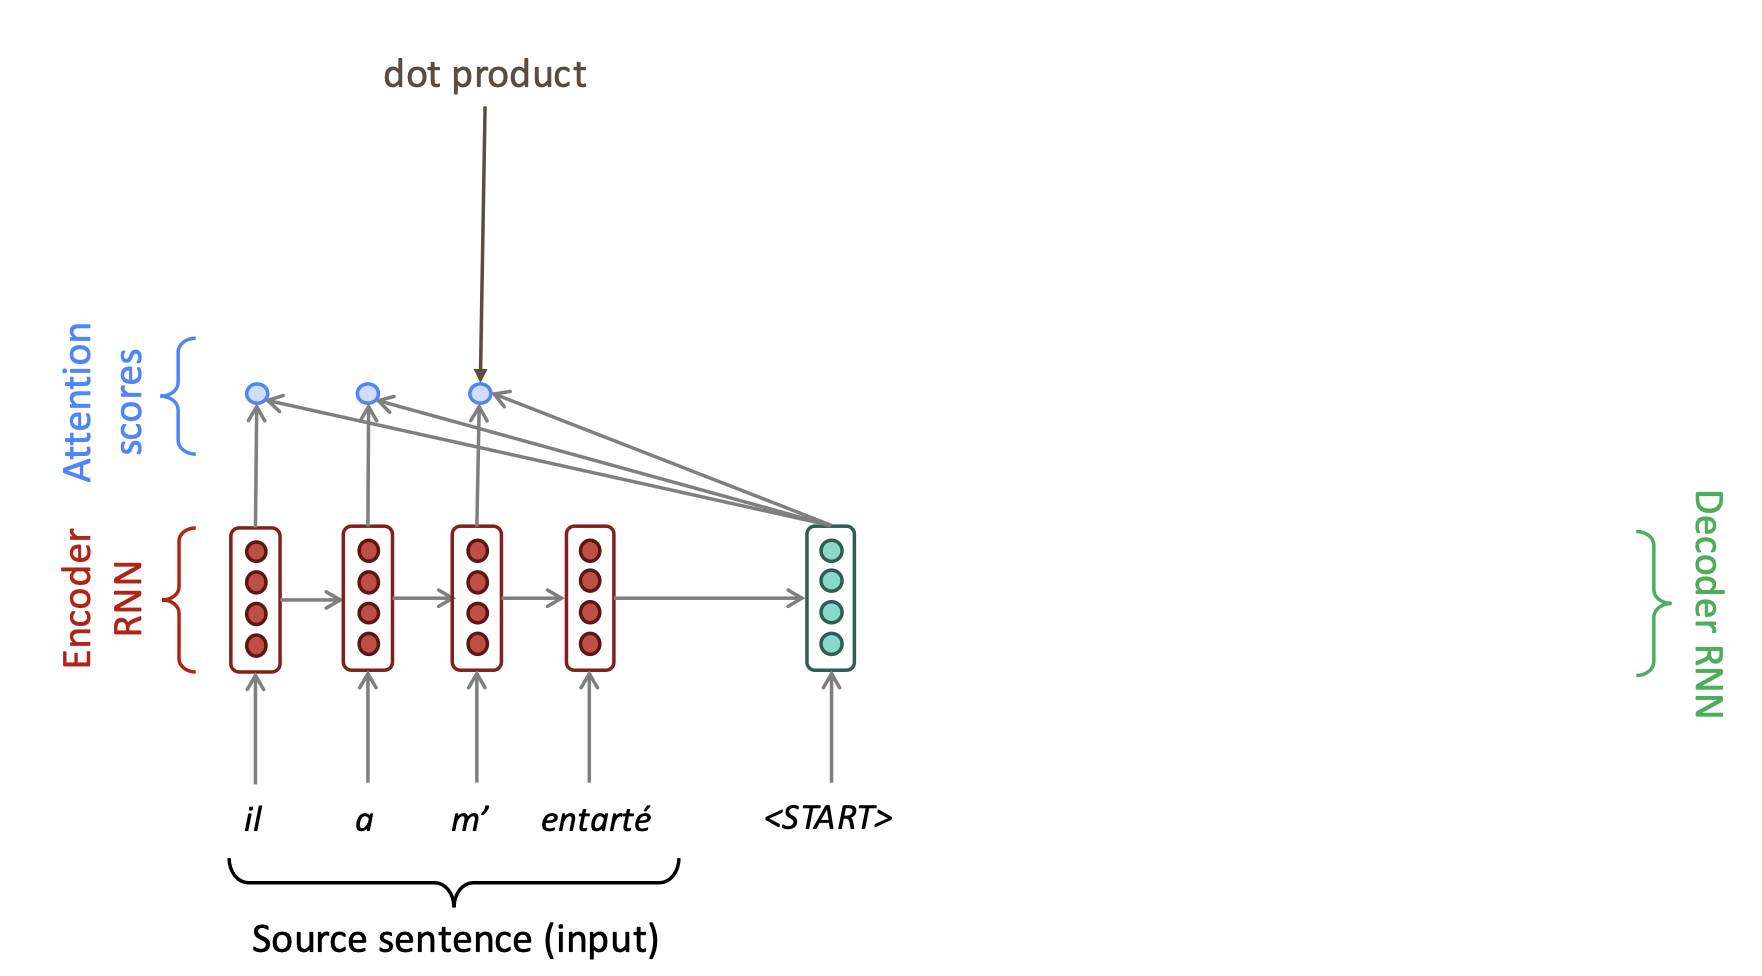
Sequence-to-Sequence With Attention
Sequence-to-Sequence With Attention
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
Core Idea: use direct connection to the encoder to focus on a particular part of the source sequence.
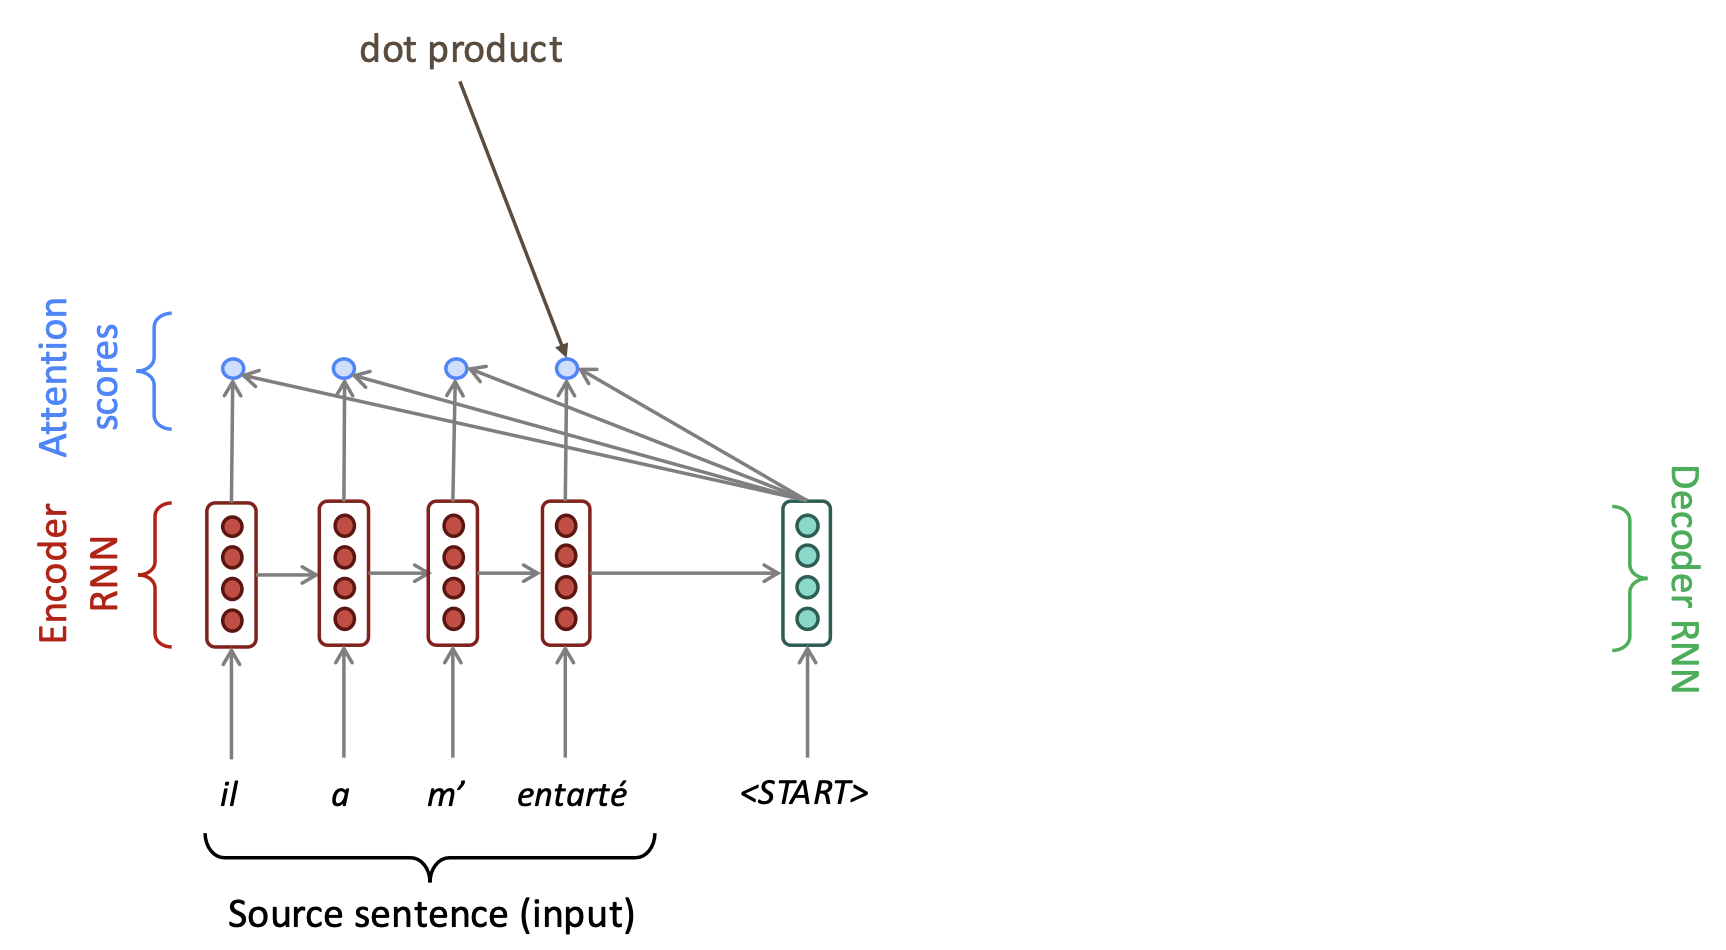
Sequence-to-Sequence With Attention
Sequence-to-Sequence With Attention
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
Core Idea: use direct connection to the encoder to focus on a particular part of the source sequence.
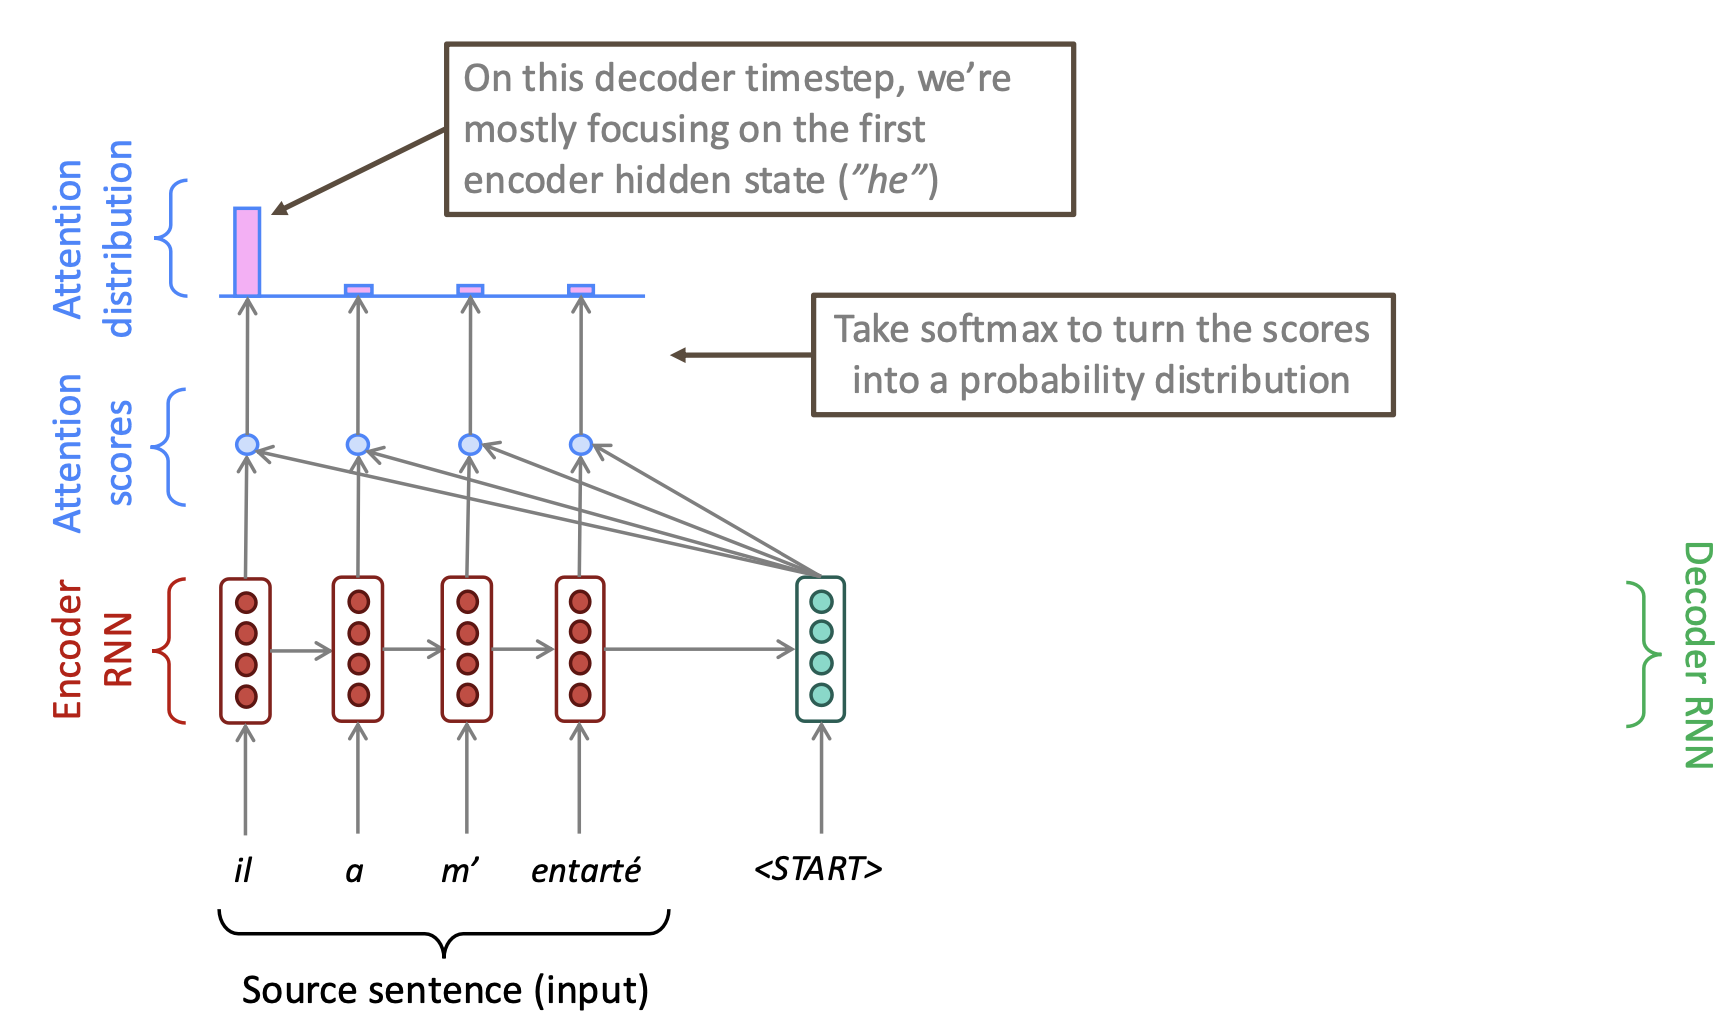
Sequence-to-Sequence With Attention
Sequence-to-Sequence With Attention
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
Core Idea: use direct connection to the encoder to focus on a particular part of the source sequence.
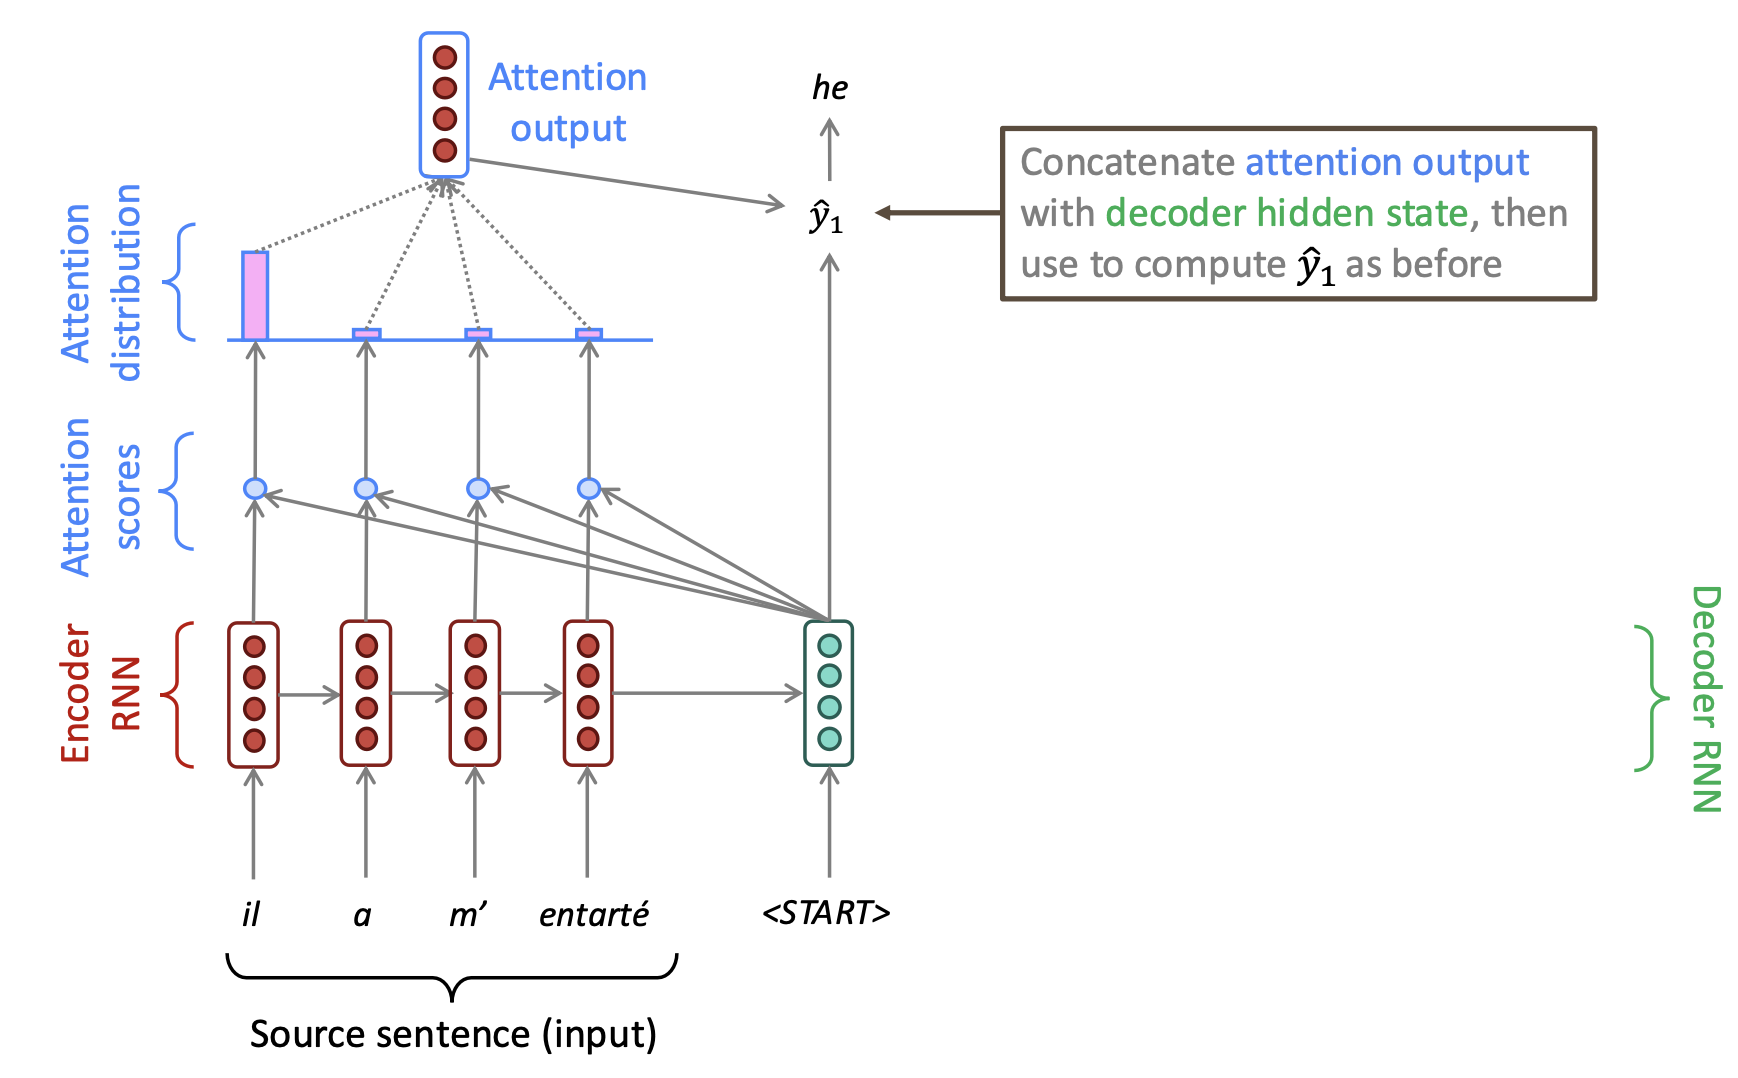
Sequence-to-Sequence With Attention
Sequence-to-Sequence With Attention
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
Core Idea: use direct connection to the encoder to focus on a particular part of the source sequence.
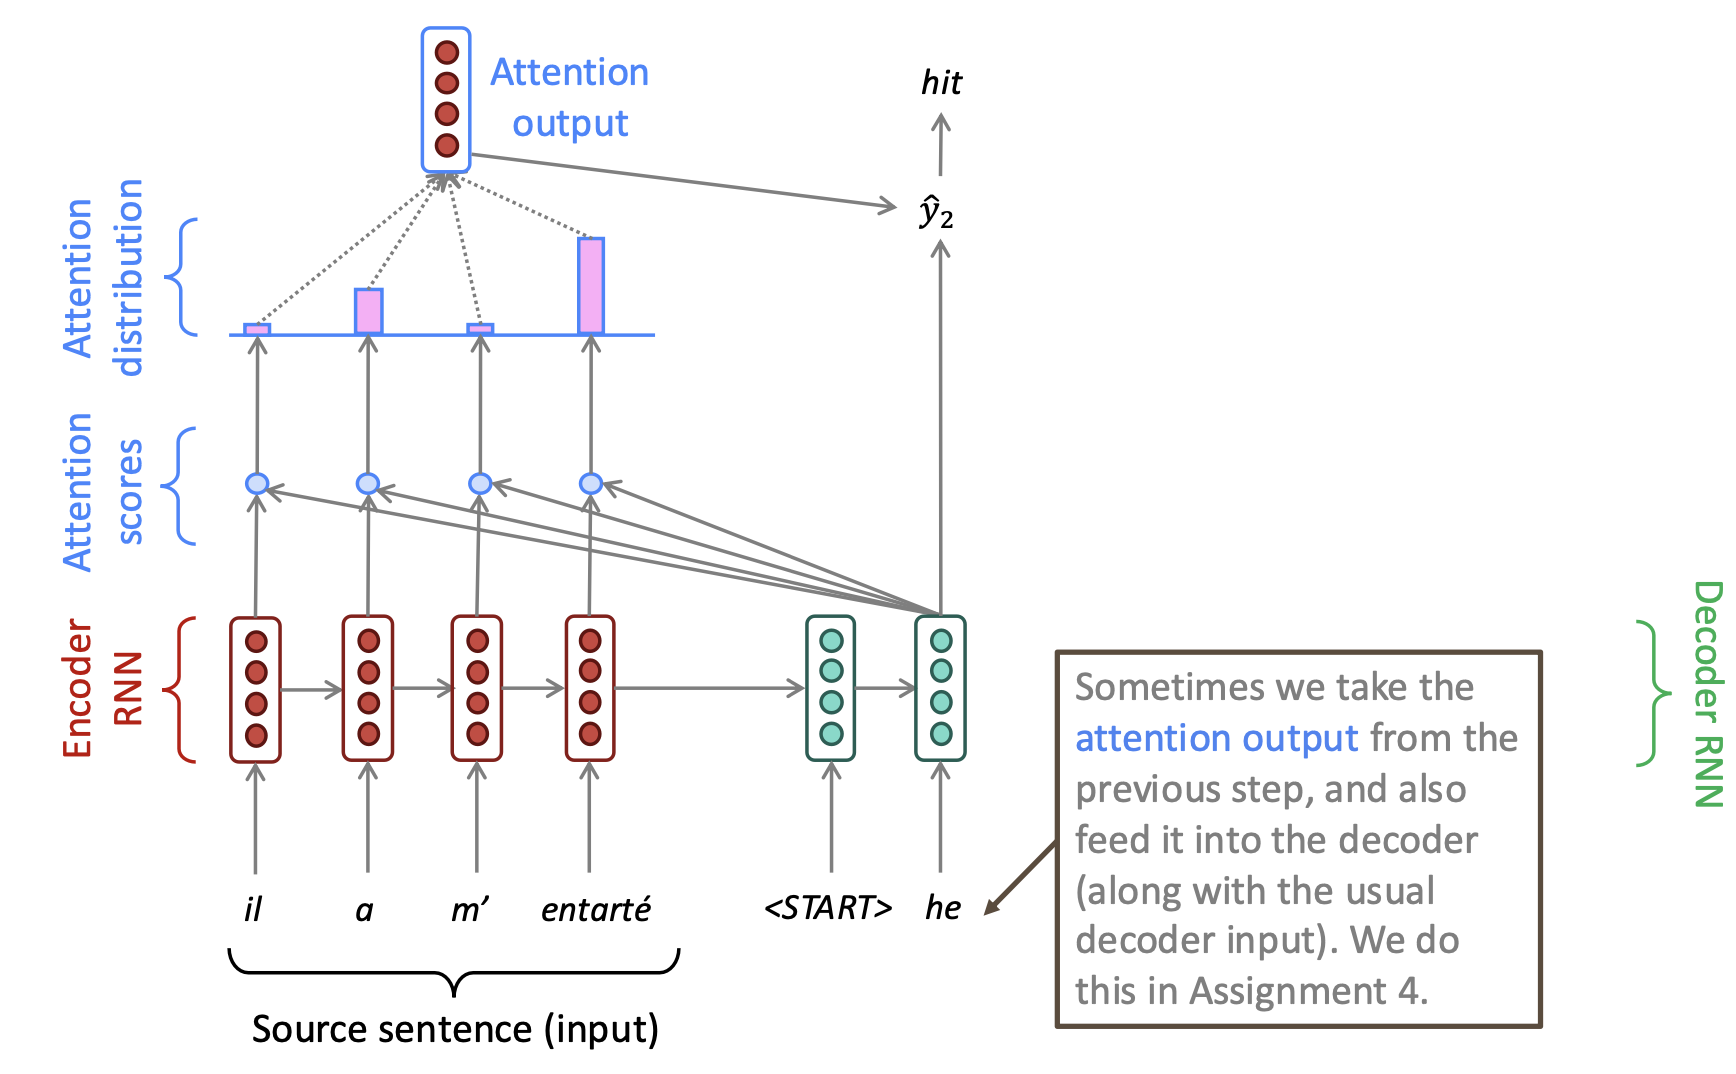
Sequence-to-Sequence With Attention
Sequence-to-Sequence With Attention
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
Core Idea: use direct connection to the encoder to focus on a particular part of the source sequence.
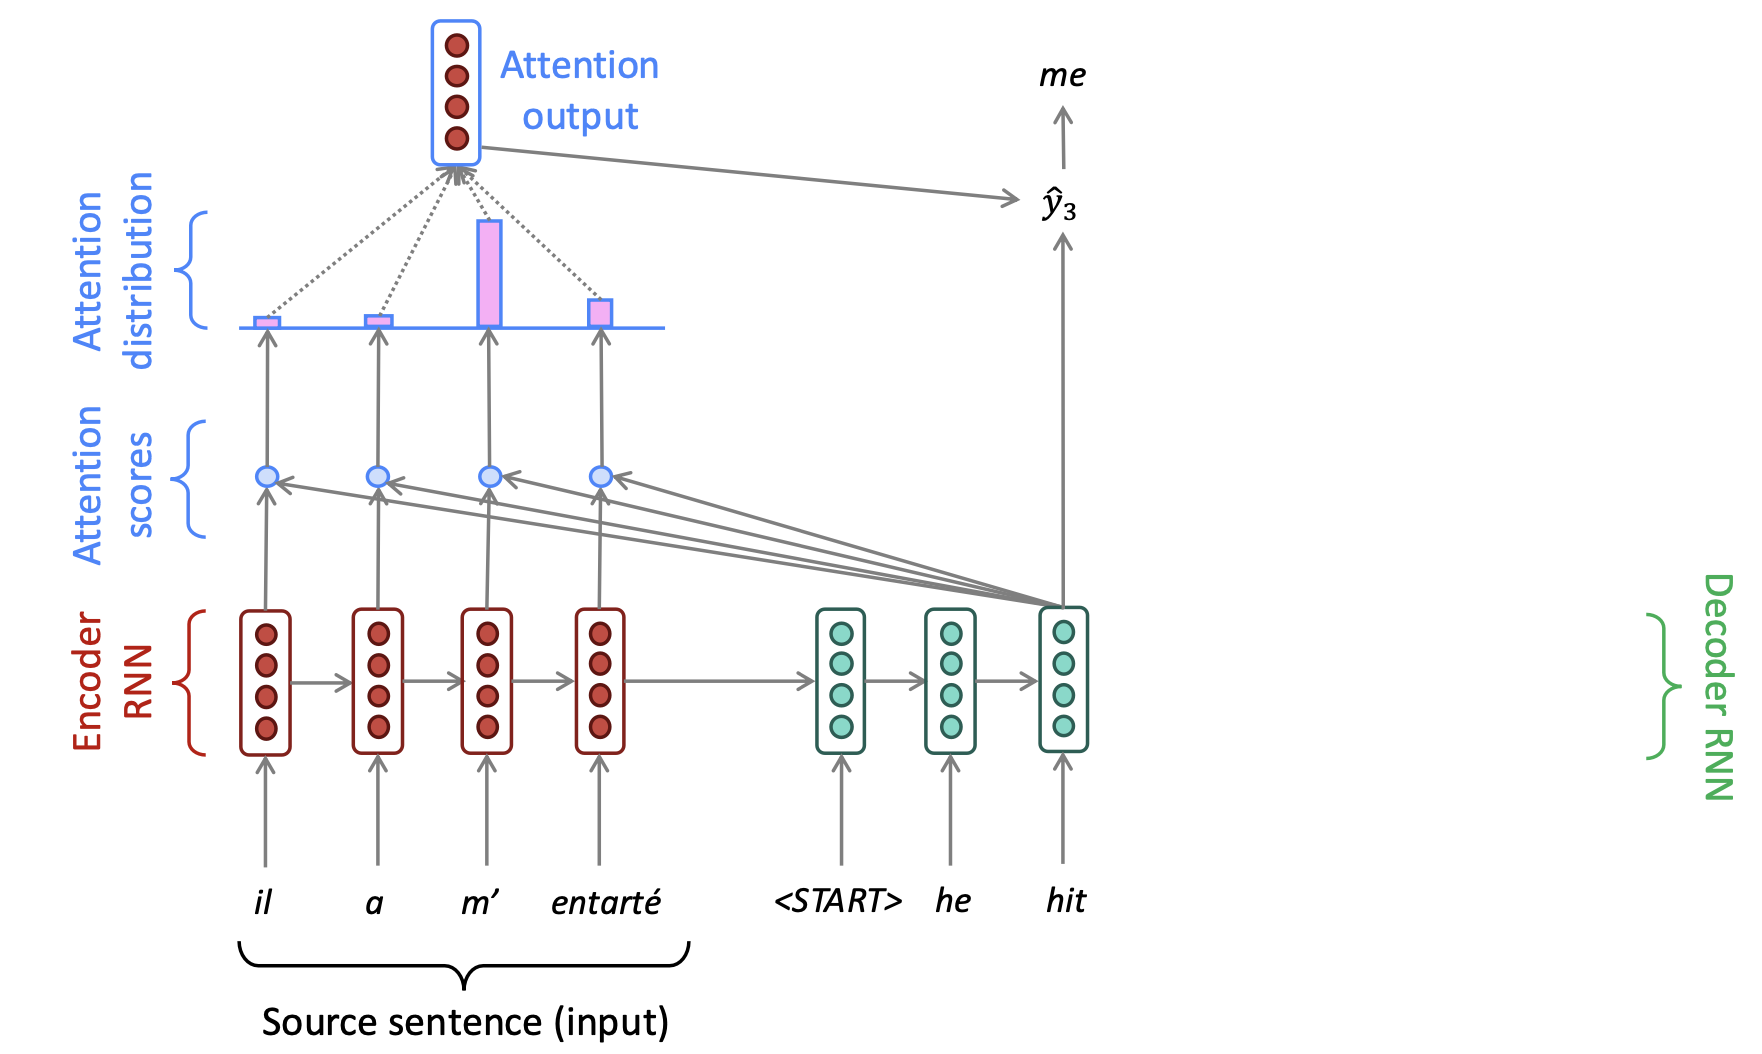
Sequence-to-Sequence With Attention
Sequence-to-Sequence With Attention
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
Core Idea: use direct connection to the encoder to focus on a particular part of the source sequence.
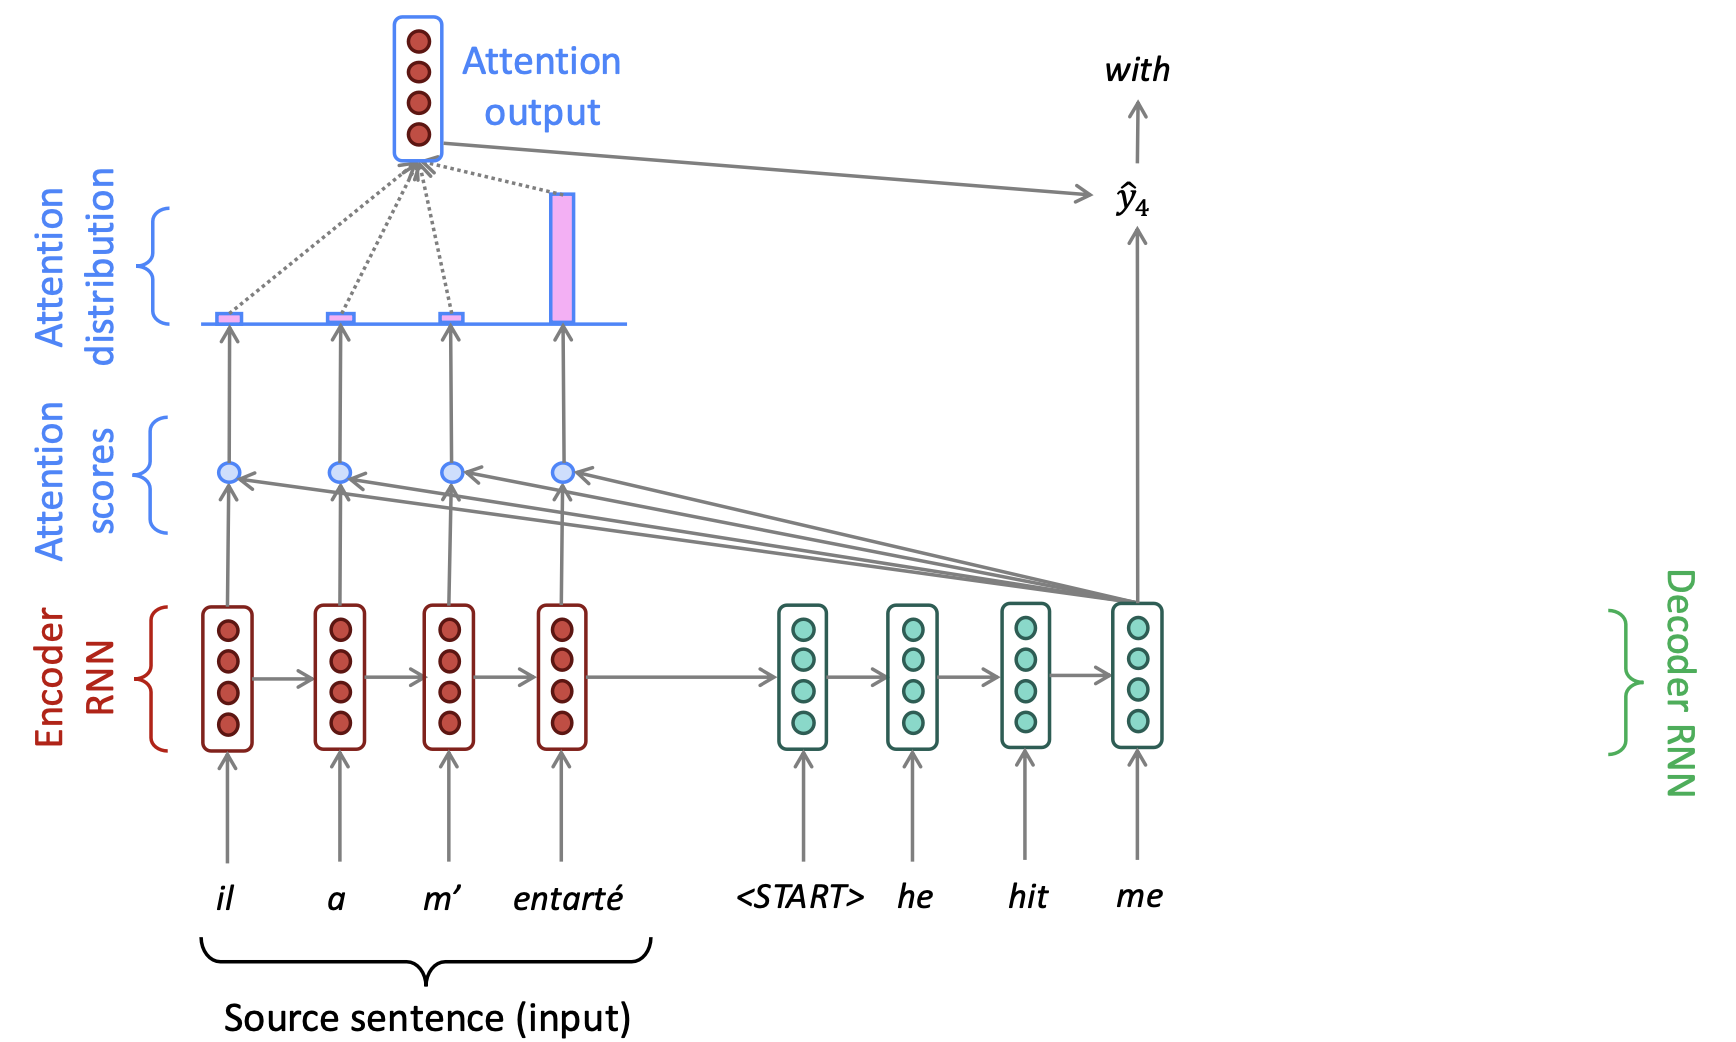
Sequence-to-Sequence With Attention
Sequence-to-Sequence With Attention
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
Core Idea: use direct connection to the encoder to focus on a particular part of the source sequence.
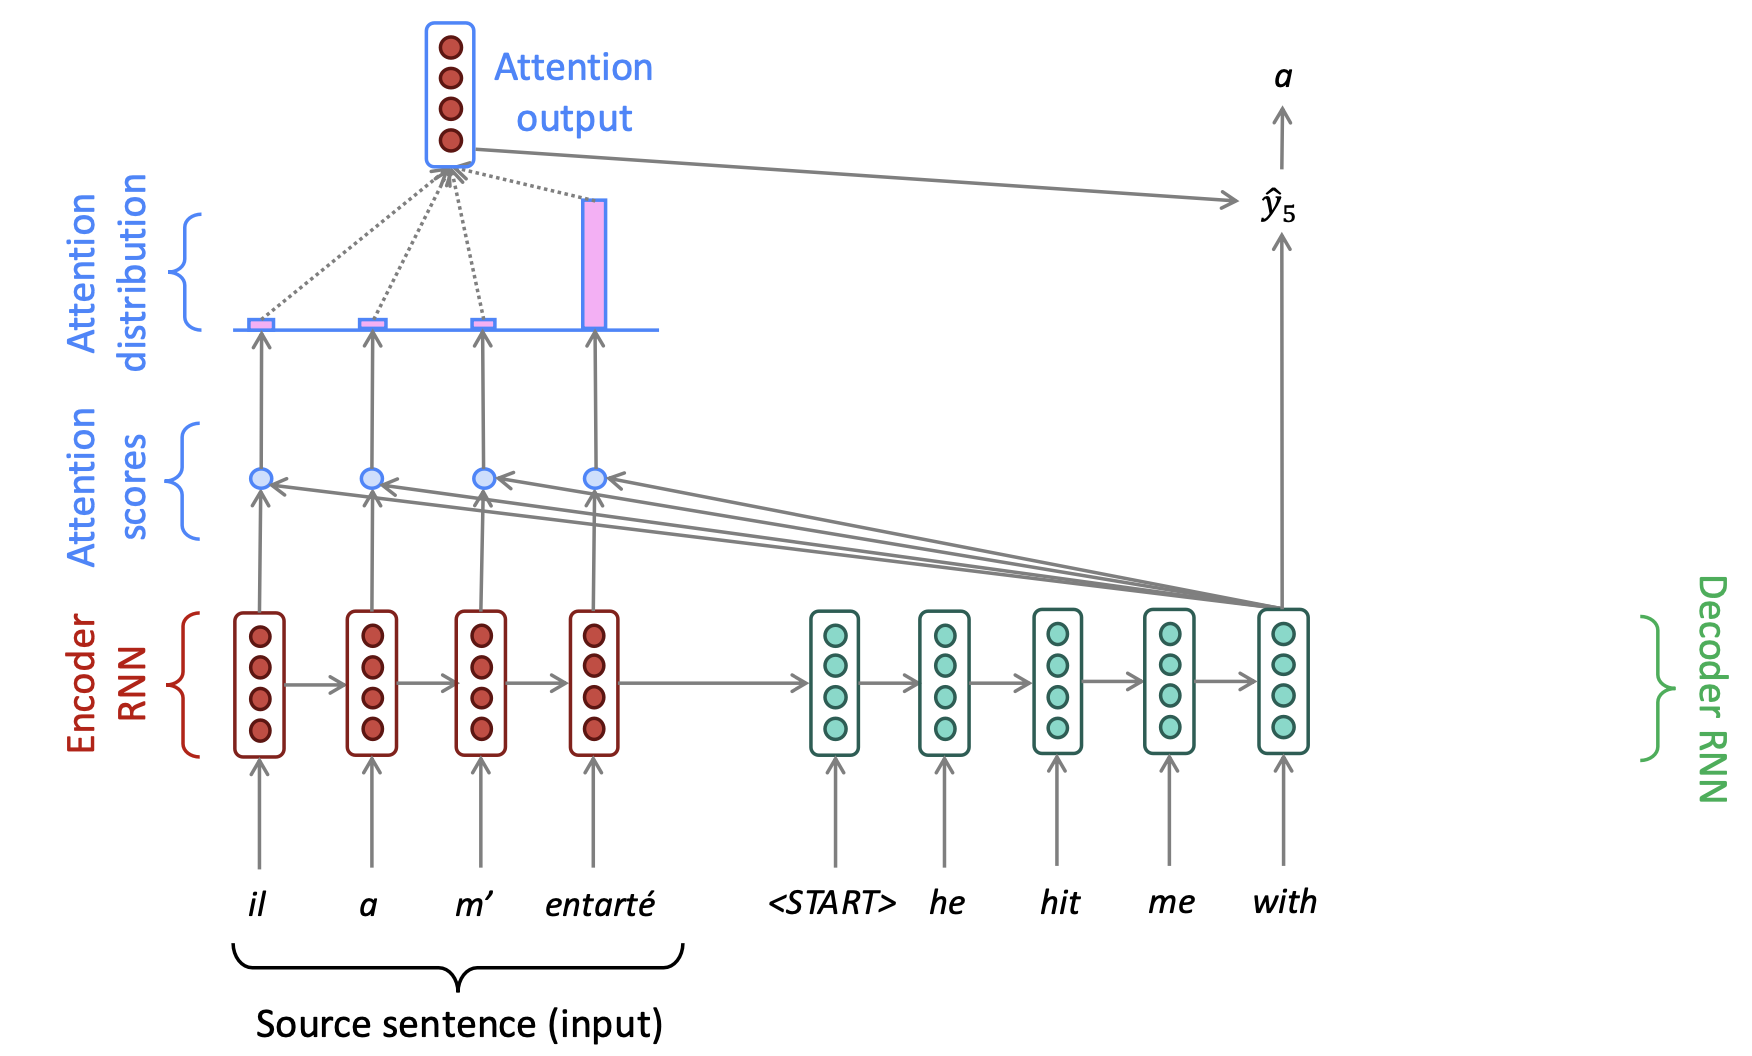
Sequence-to-Sequence With Attention
Sequence-to-Sequence With Attention
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
Core Idea: use direct connection to the encoder to focus on a particular part of the source sequence.
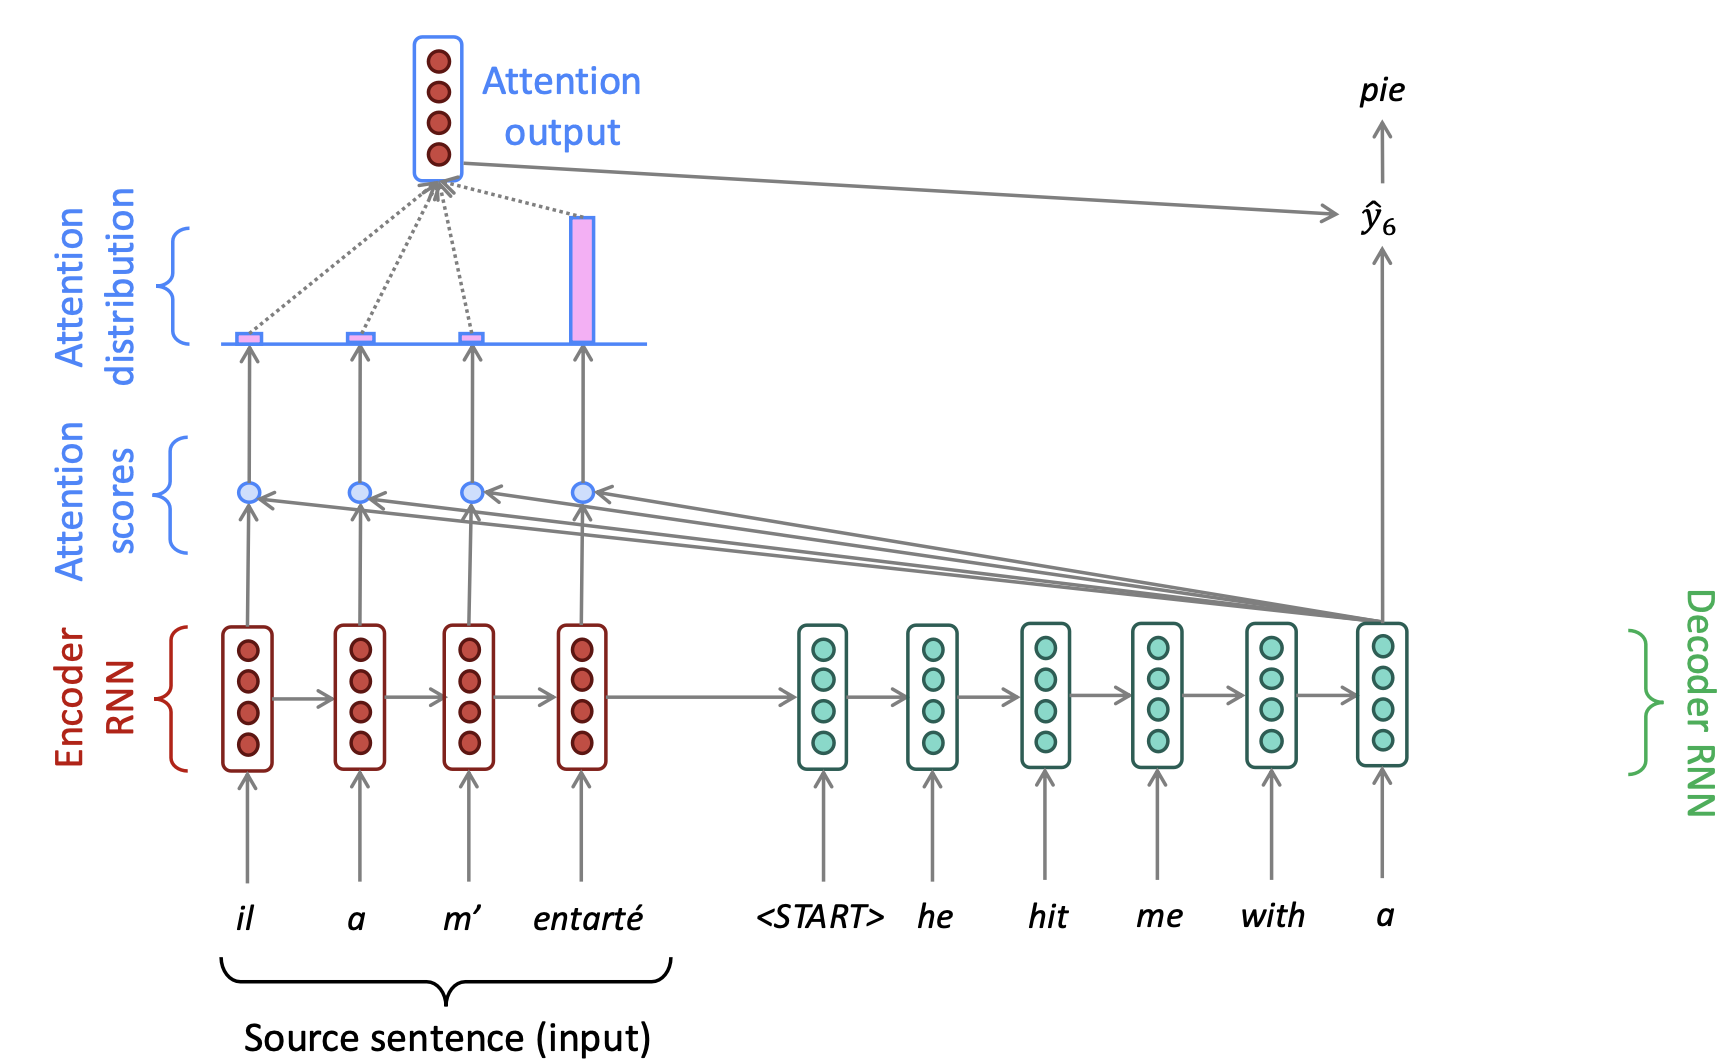
Attention: Formulation
Attention: Formulation
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
Given encoder hidden states:
Decoder hidden state on timestep :
The attention scores for this step:
The attention distribution:
The attention output by weighted sum:
Final decoder hidden state:
Attention solves Limitations of RNN
Attention solves Limitations of RNN
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
Number of unparallelizable operations does not increase with sequence length.
Maximum interaction distance: O(1), since all words interact at every layer
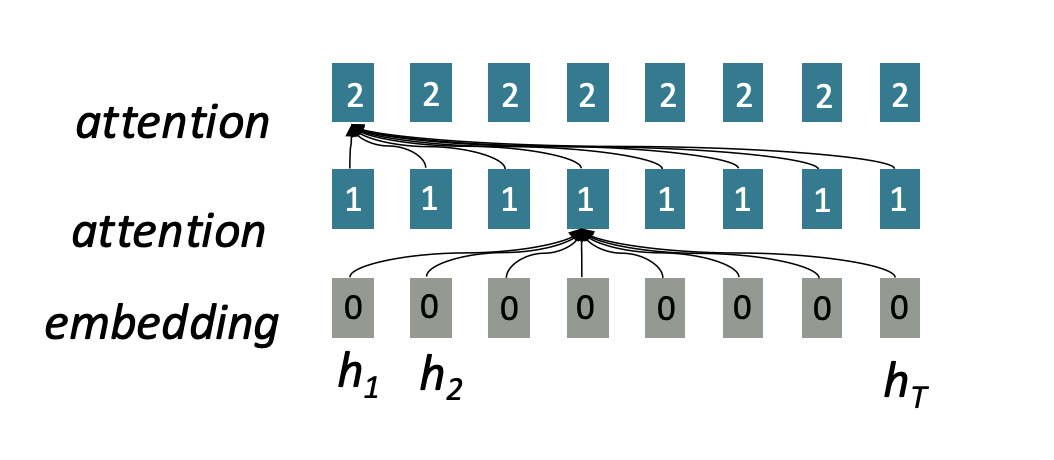
Attention becomes a General Technique
Attention becomes a General Technique
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture06-fancy-rnn.pdf
More general definition of attention:
Given a set of vector values, and a vector query, attention is a technique to compute a weighted sum of the values, dependent on the query.
Intuition:
The weighted sum is a selective summary of the information contained in the values, where the query determines which values to focus on.
Attention is a way to obtain a fixed-size representation of an arbitrary set of representations (the values), dependent on some other representation (the query).
Attention vs RNN
Attention vs RNN
Feature | Self-Attention | Traditional RNN |
Processing Style | ✅ Processes all tokens simultaneously (parallel) | ❌Processes tokens one by one (sequential) |
Information Flow | ✅ Any two tokens connect in 1 step | ❌Long-range dependencies require many steps |
Parallelism | ✅ Fully parallelizable (fast) | ❌ Inherently sequential (slow) |
Dependency Modeling | ✅ Excellent at long-range dependencies | ❌Poor at long-range dependencies (vanishing gradients) |
Interpretability | ✅ Attention weights show what is focused on | ❌ Hard to interpret hidden states |
Linearity | ❌ Linear | ✅ Nonlinear |
Order Sensitive | ❌ No | ✅ Yes |
2.2 Transformer 2.2.3 Transformer Overview
2.2 Transformer 2.2.3 Transformer Overview
Motivation
Motivation
Attention had to be used with RNN, so the architecture RNN+Attention still suffers from RNN’s limitation;
Key Idea:
Why Not Just Use Attention?
Difficulties:
How can Attention used as Encoder?
Attention is Linear
Attention omits the order information
The Solution:
Transformer Architecture
Attention is All You Need (2017)
Attention is All You Need (2017)
NMT Task
NMT Task
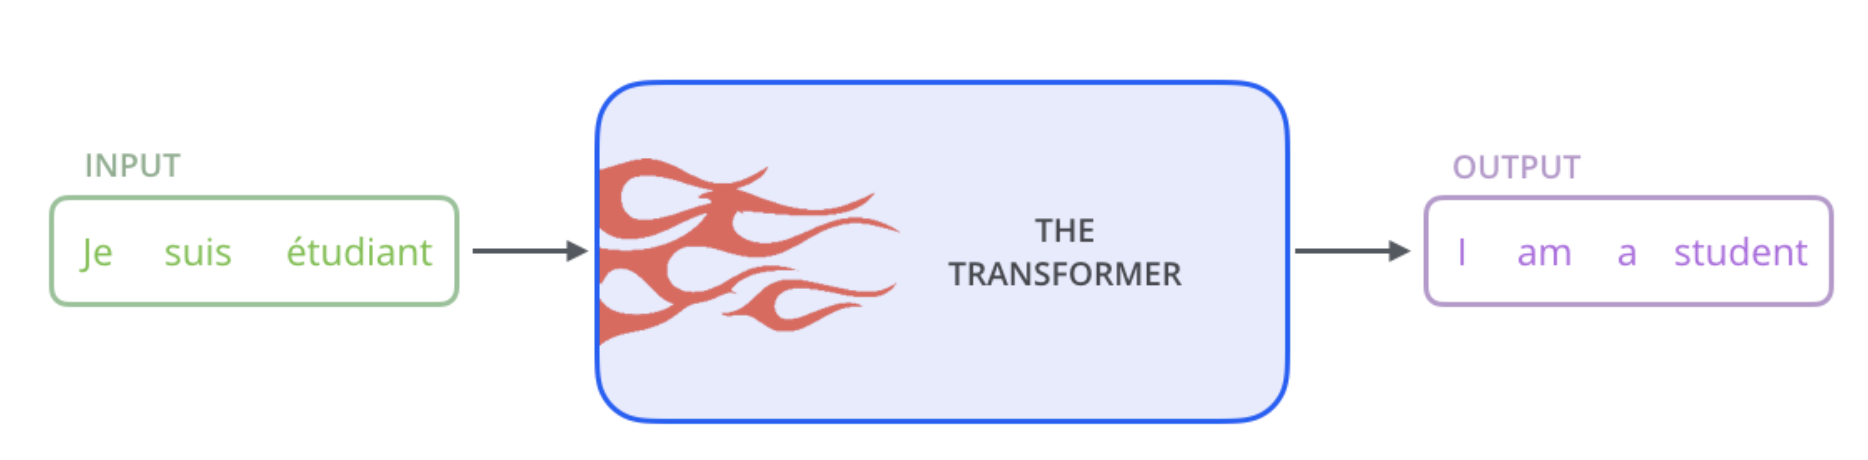
https://jalammar.github.io/illustrated-transformer/
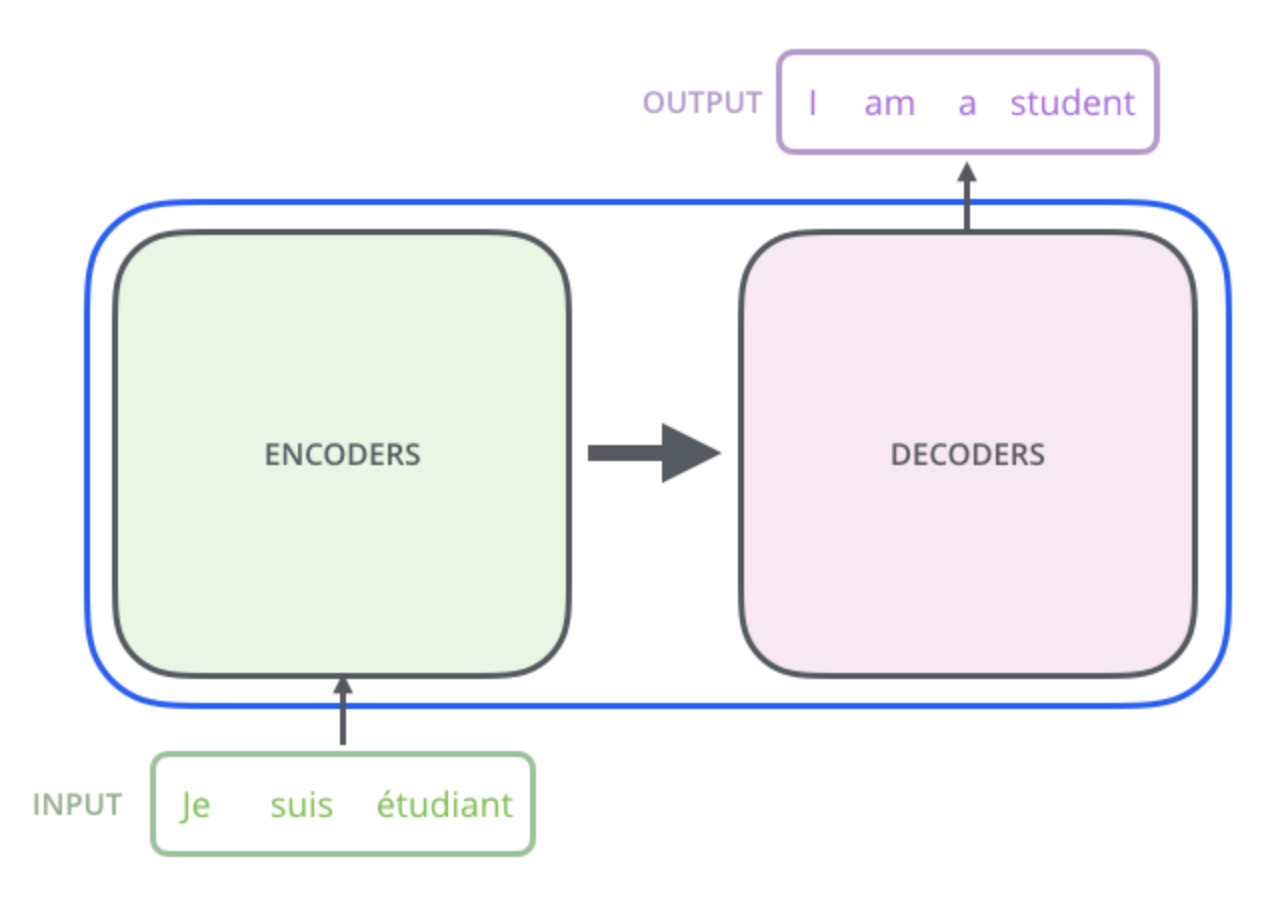
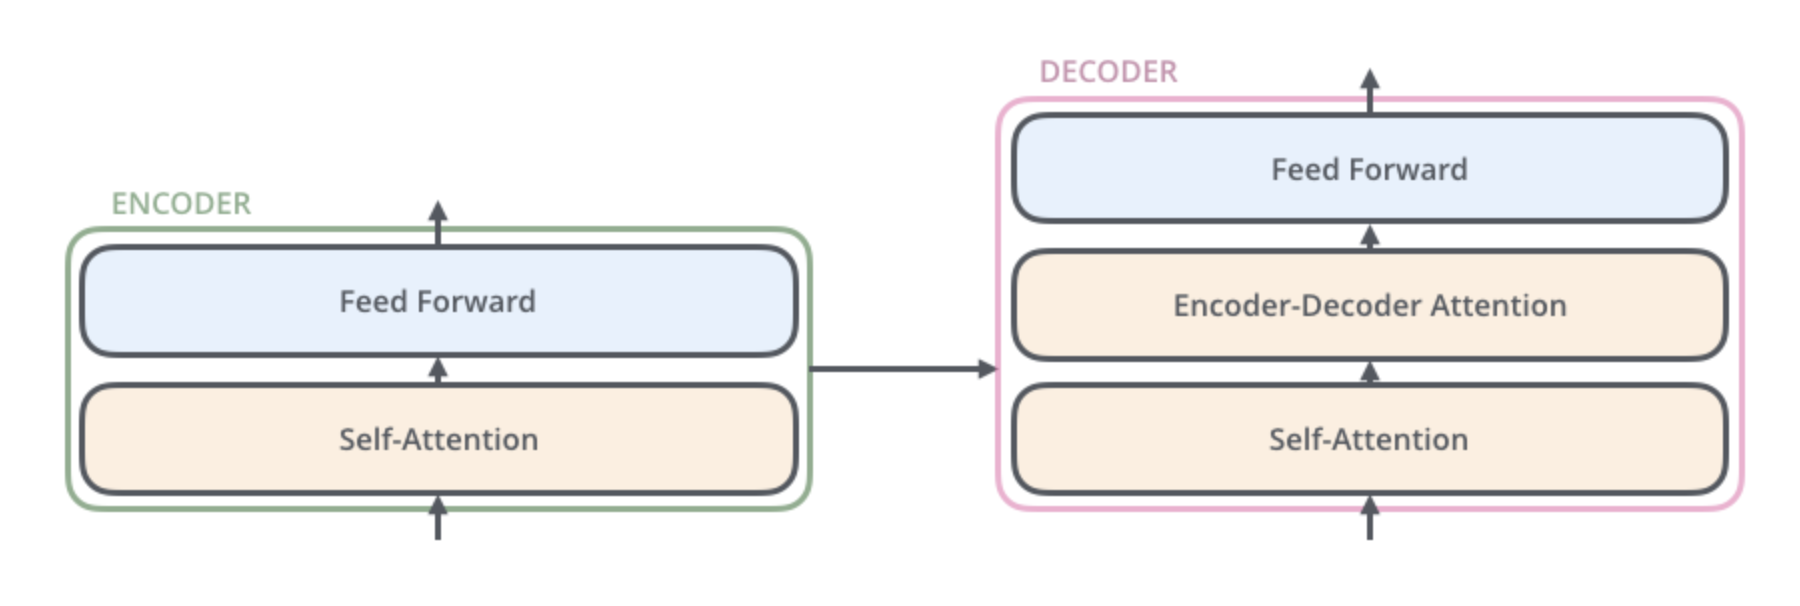
Decoder-Encoder
Decoder-Encoder
https://jalammar.github.io/illustrated-transformer/
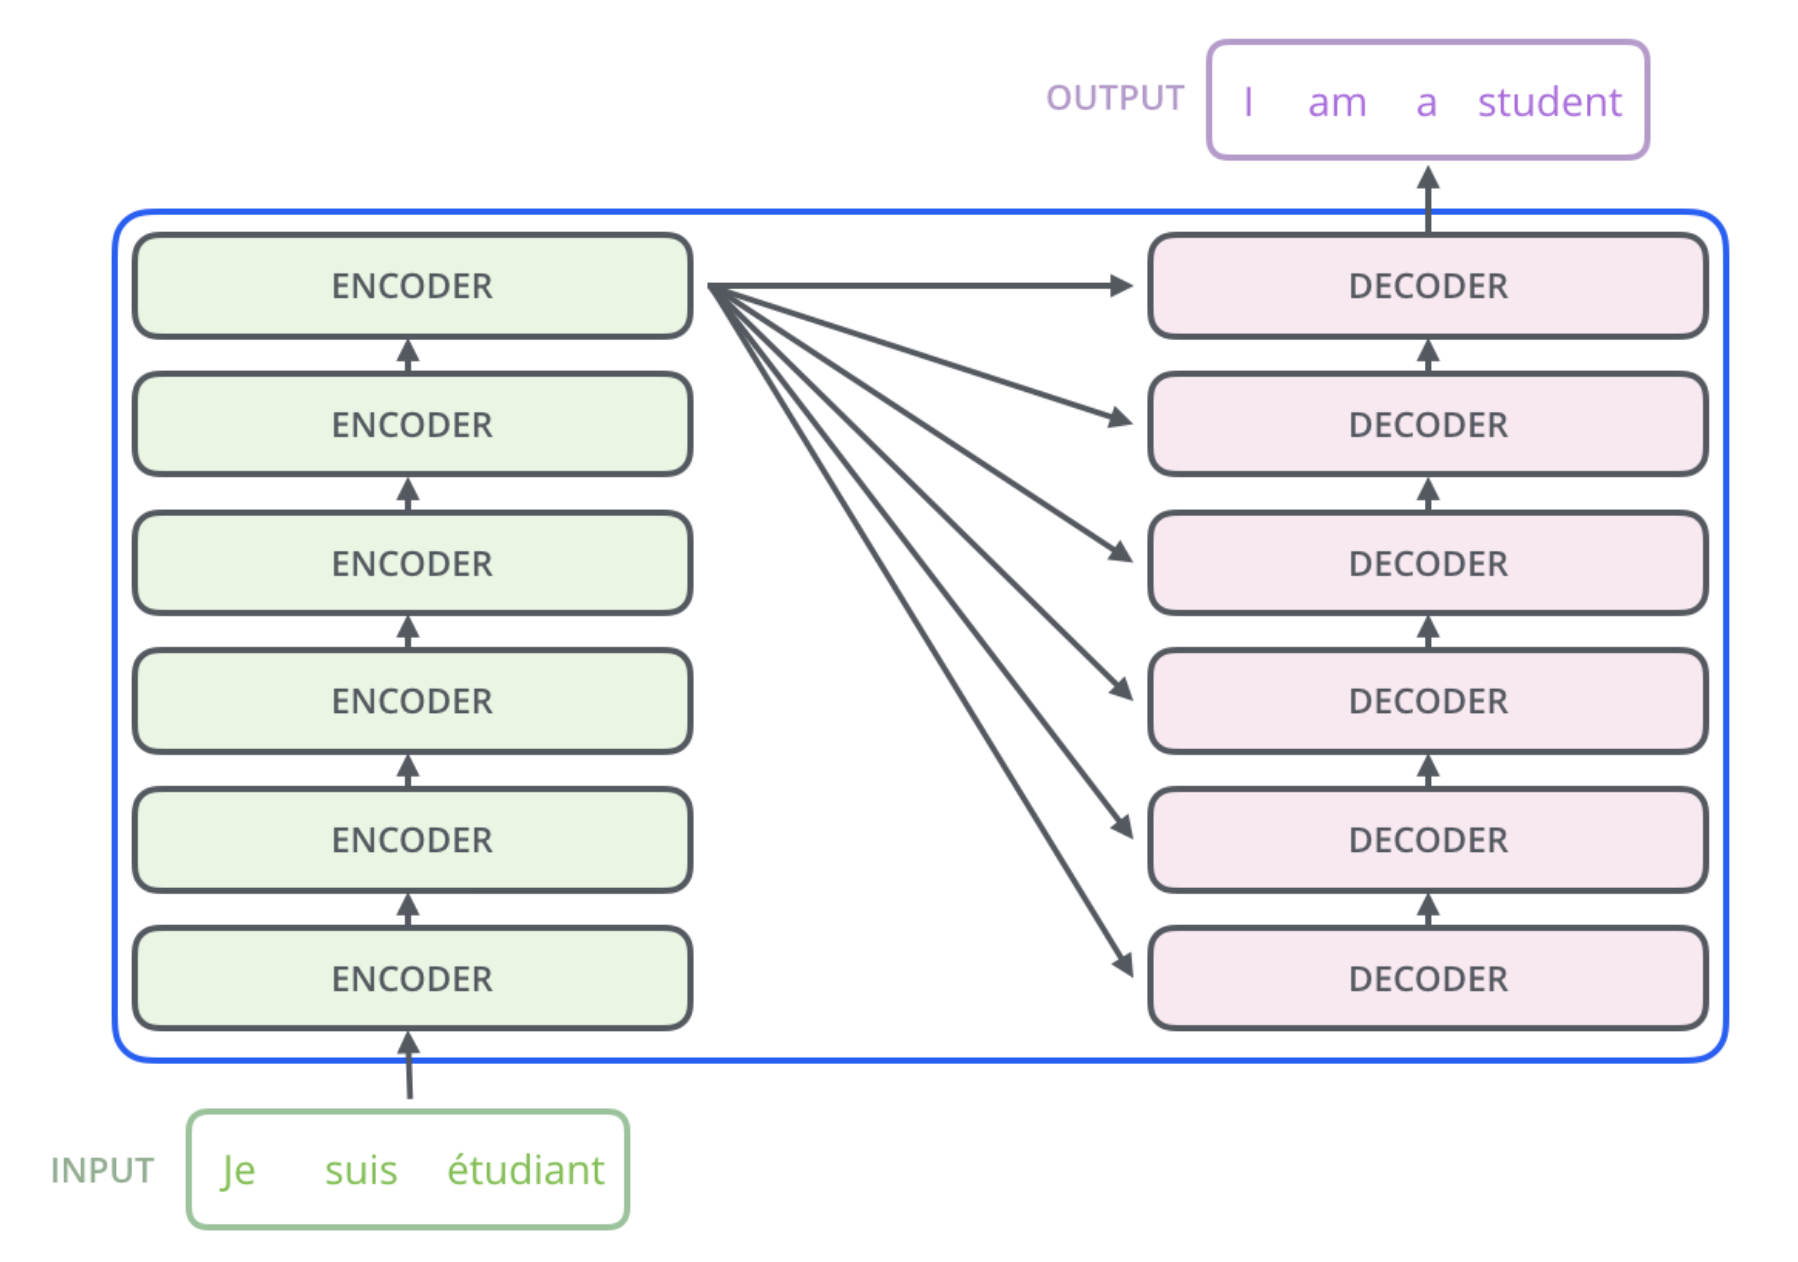
Stack of Layers
Stack of Layers
https://jalammar.github.io/illustrated-transformer/
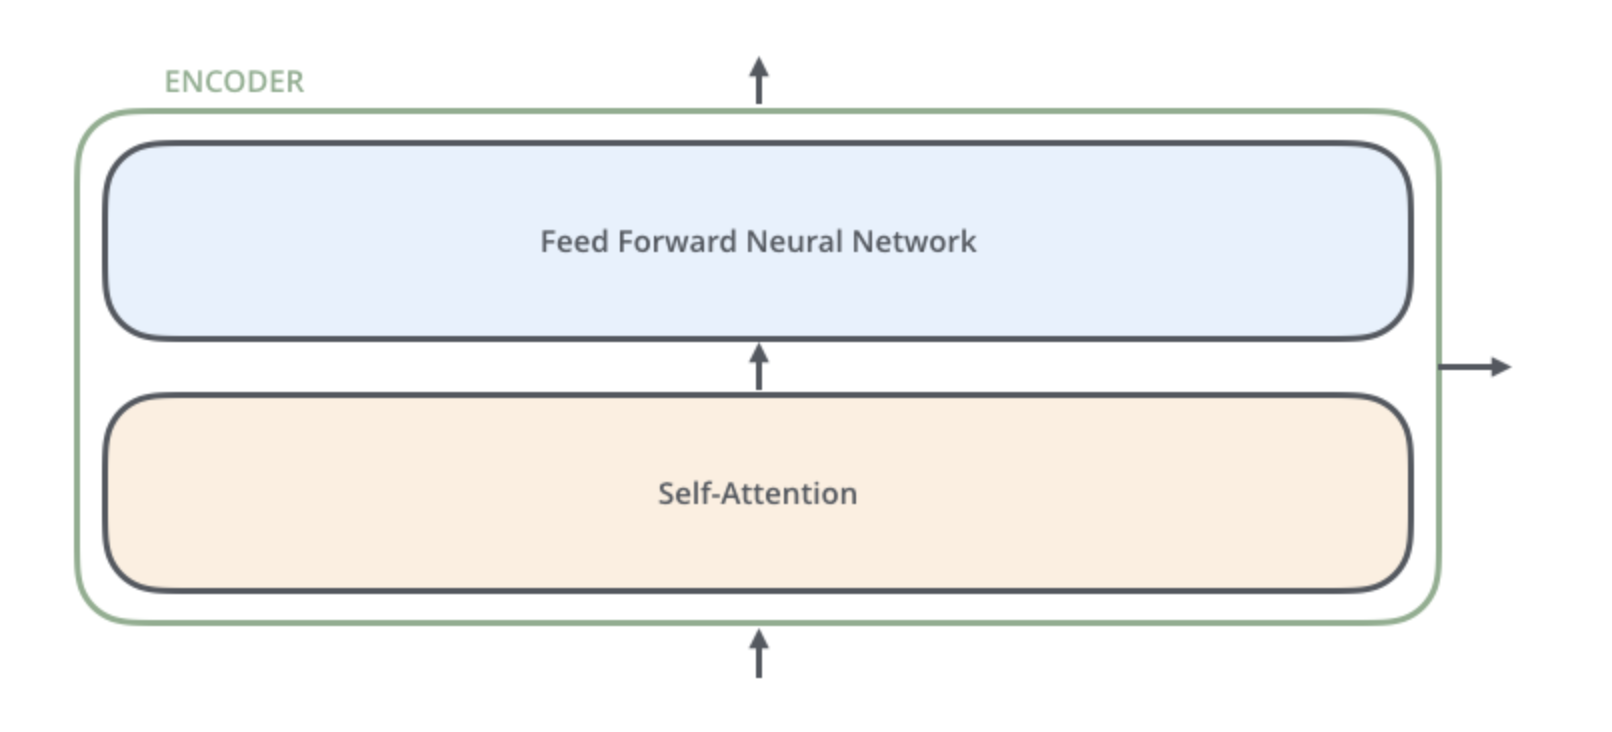
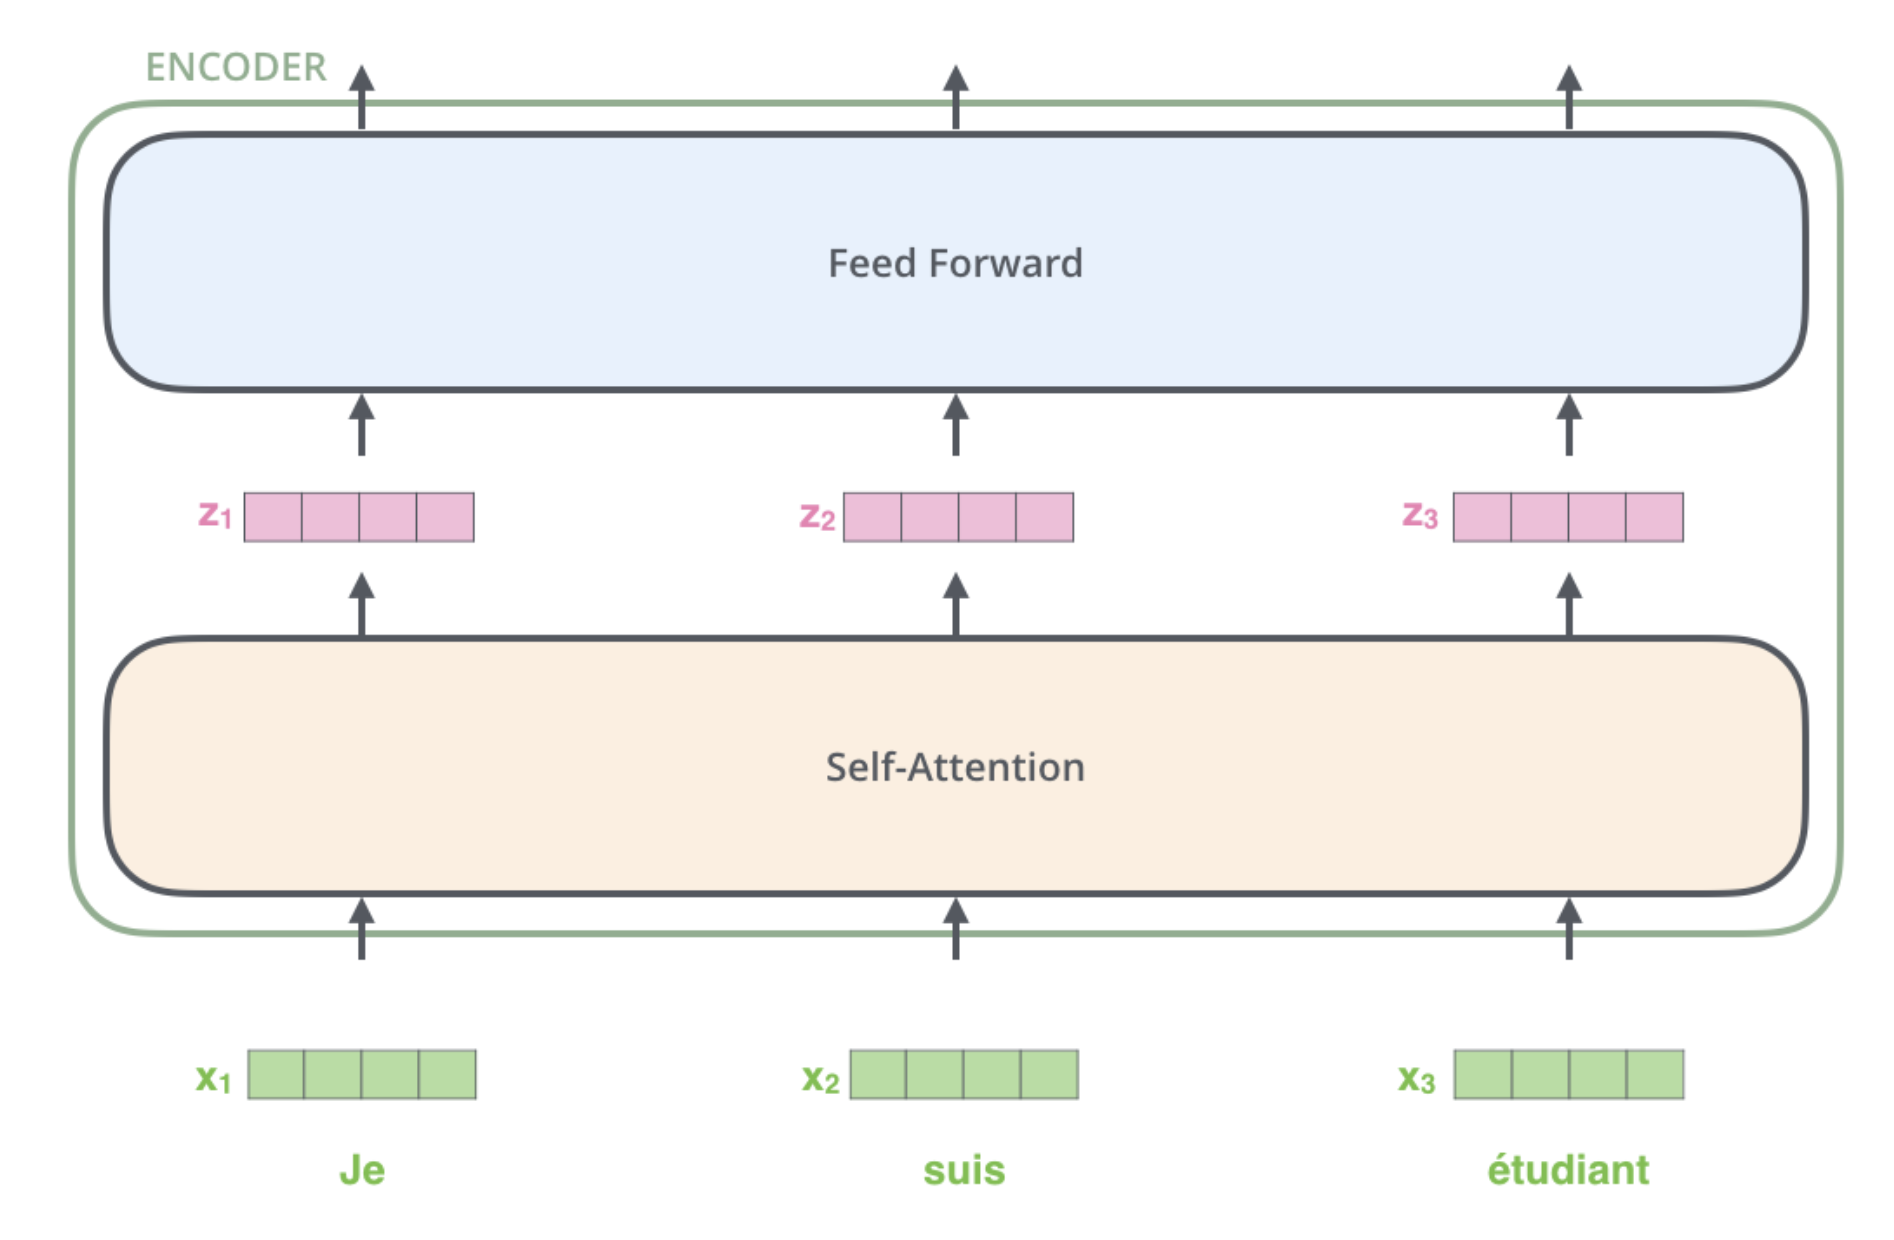
Encoder Layer
Encoder Layer
https://jalammar.github.io/illustrated-transformer/
Decoder Layer
Decoder Layer
https://jalammar.github.io/illustrated-transformer/
2.2 Transformer 2.2.4 Transformer Blocks
2.2 Transformer 2.2.4 Transformer Blocks
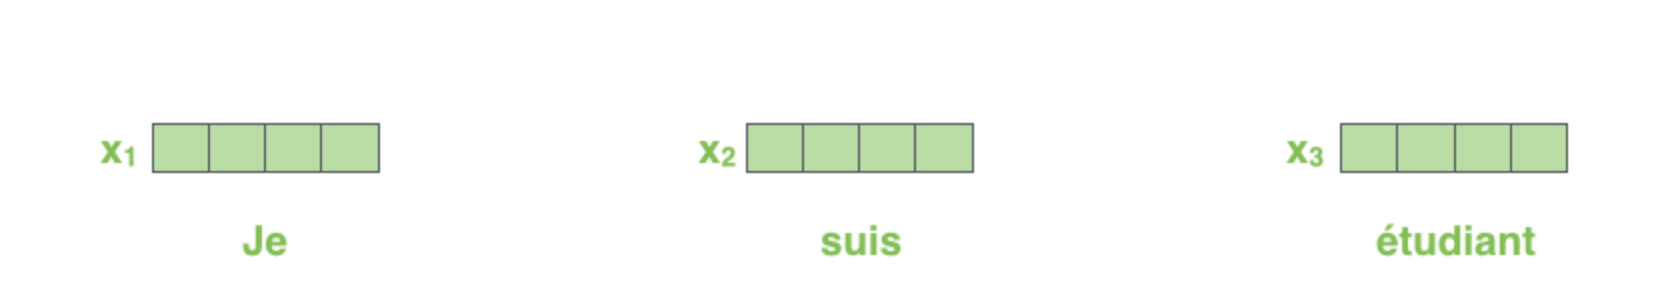
Input Embedding
Input Embedding
https://jalammar.github.io/illustrated-transformer/
Embedding in the Block
Embedding in the Block
https://jalammar.github.io/illustrated-transformer/
2.2 Transformer 2.2.5 Self-Attention
2.2 Transformer 2.2.5 Self-Attention
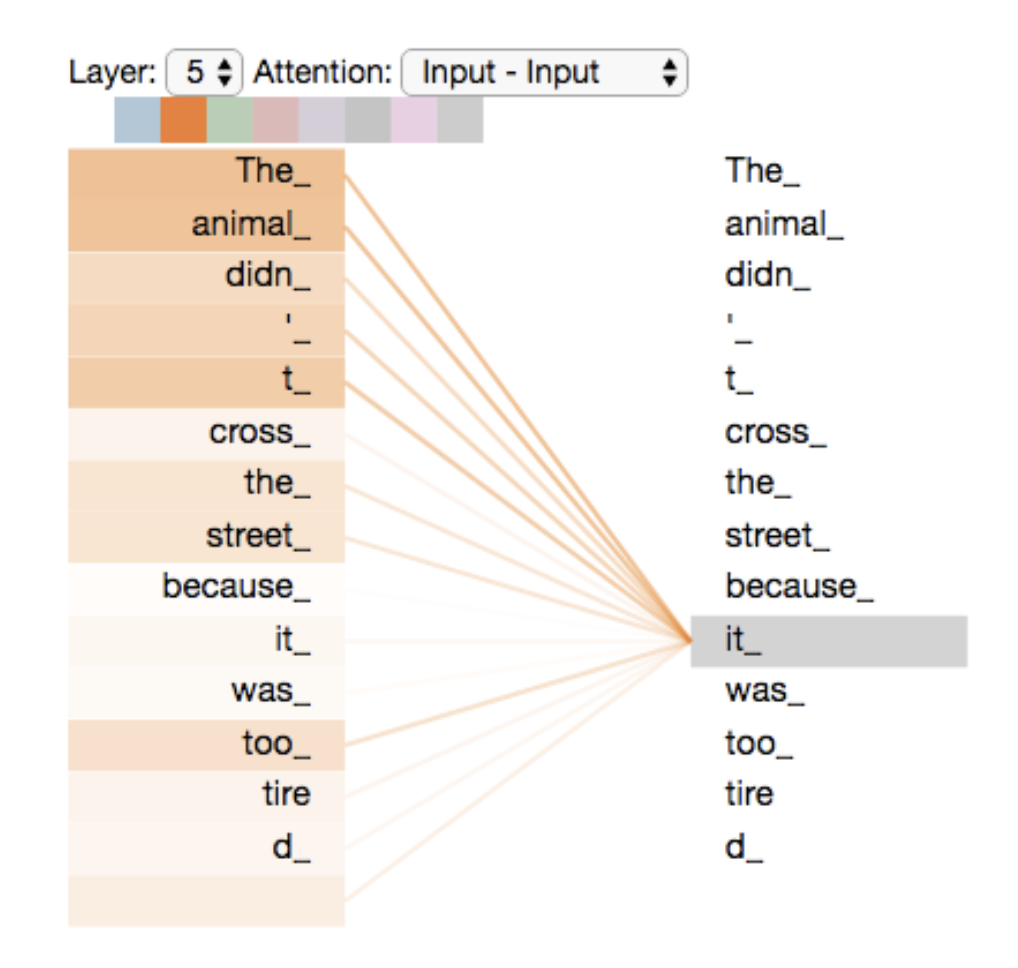
Self-Attention
Self-Attention
https://jalammar.github.io/illustrated-transformer/
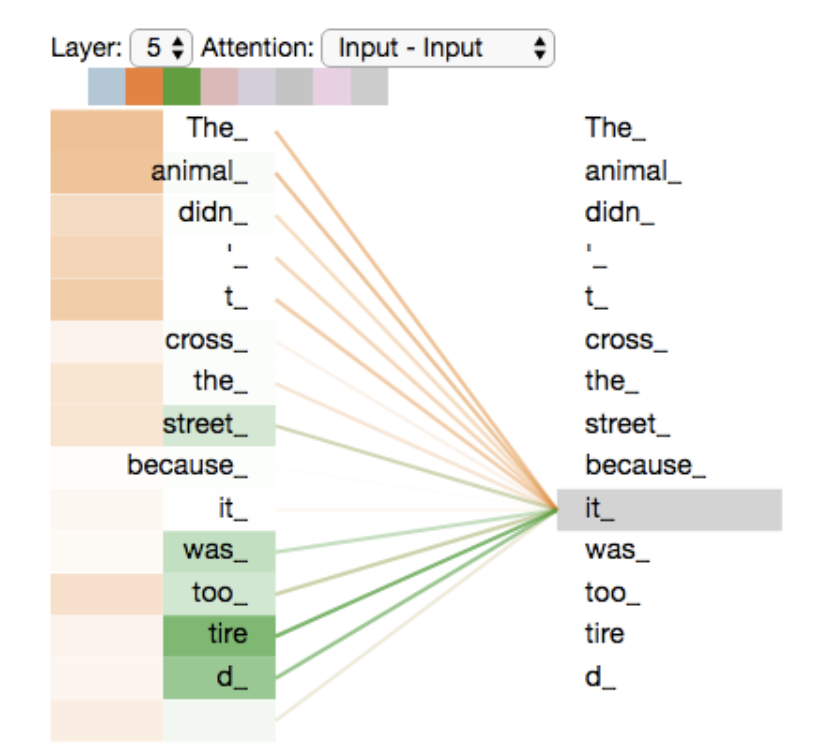
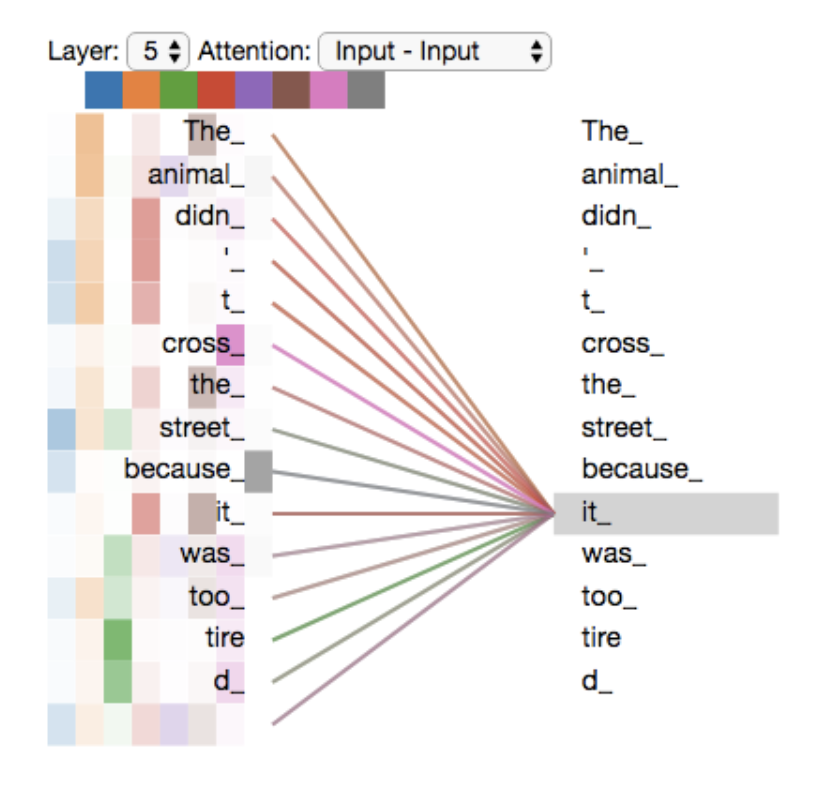
”The animal didn't cross the street because it was too tired”
For each word, what is the relationship between me and other words?
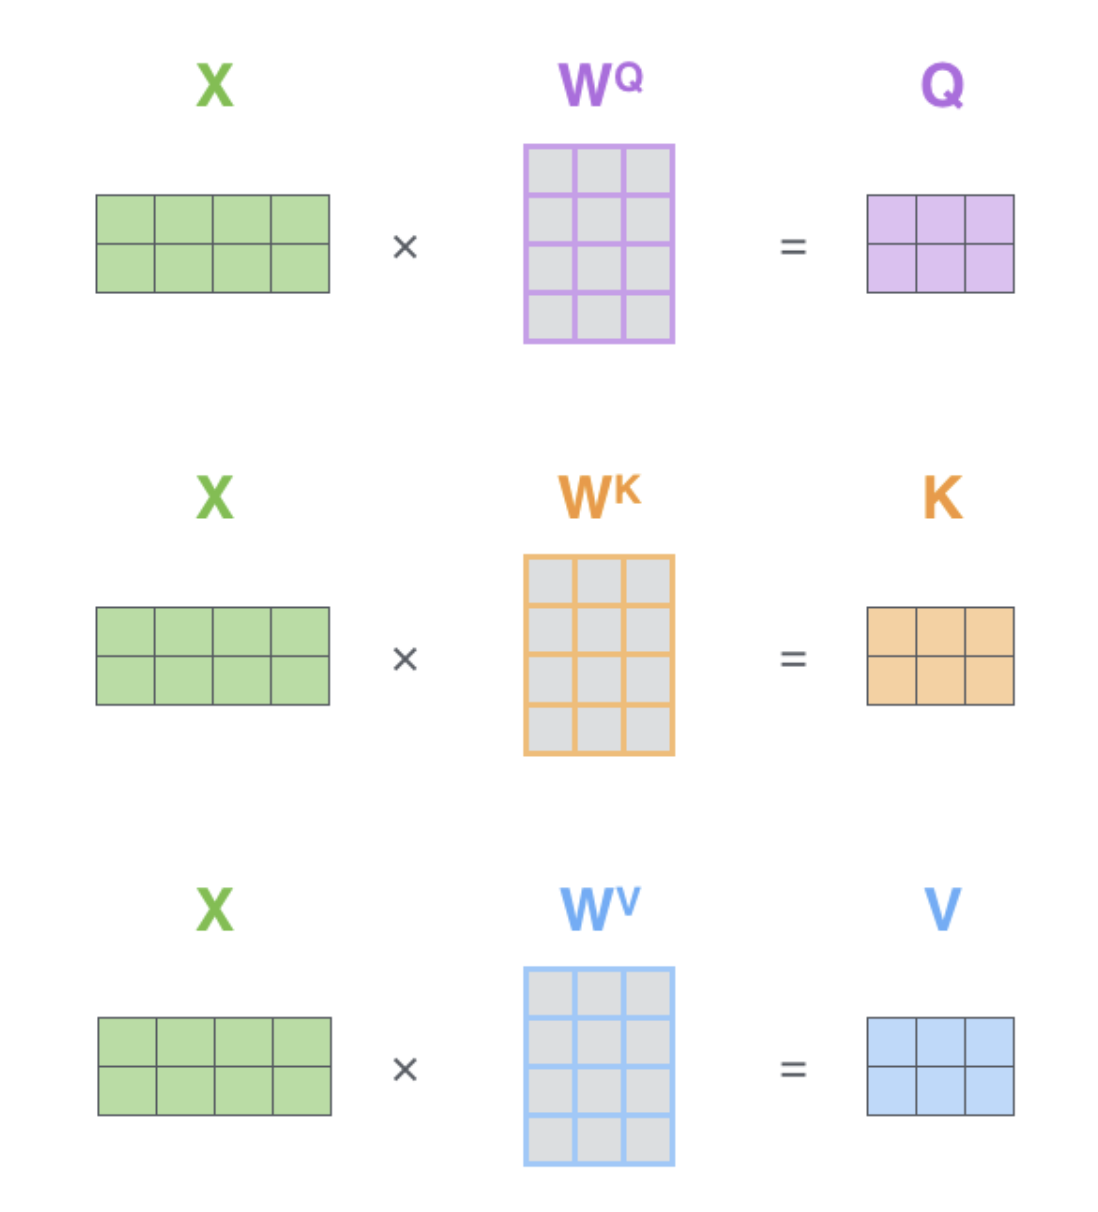
Mechanism Design: Q, K, V
Mechanism Design: Q, K, V
Each token acts like a “questioner,” using its own Query to “ask” the Keys of other tokens, and then obtains a weighted combination of their Values — which becomes the final attention output.
📌 Query (Q)
Represents the type of information the token at the current position is seeking.
For example, if the current token is “ate,” it might want to know: “Who did the eating?”
📌 Key (K)
Represents the “tag” or “description” of the information each token provides.
For instance, the token “He” might have a key representing “subject-type pronoun,” so it will be matched accordingly.
📌 Value (V)
Is the actual content or information provided by each token, and will be selected as part of the final output.
The token “He” might provide the actual semantic content like “male third-person singular subject” — this is the Value.
Q and K determine who you pay attention to, but you ultimately receive is the information provided by those you pay attention to — that is, the Values (V).
Mechanism Design: Q, K, V
Mechanism Design: Q, K, V
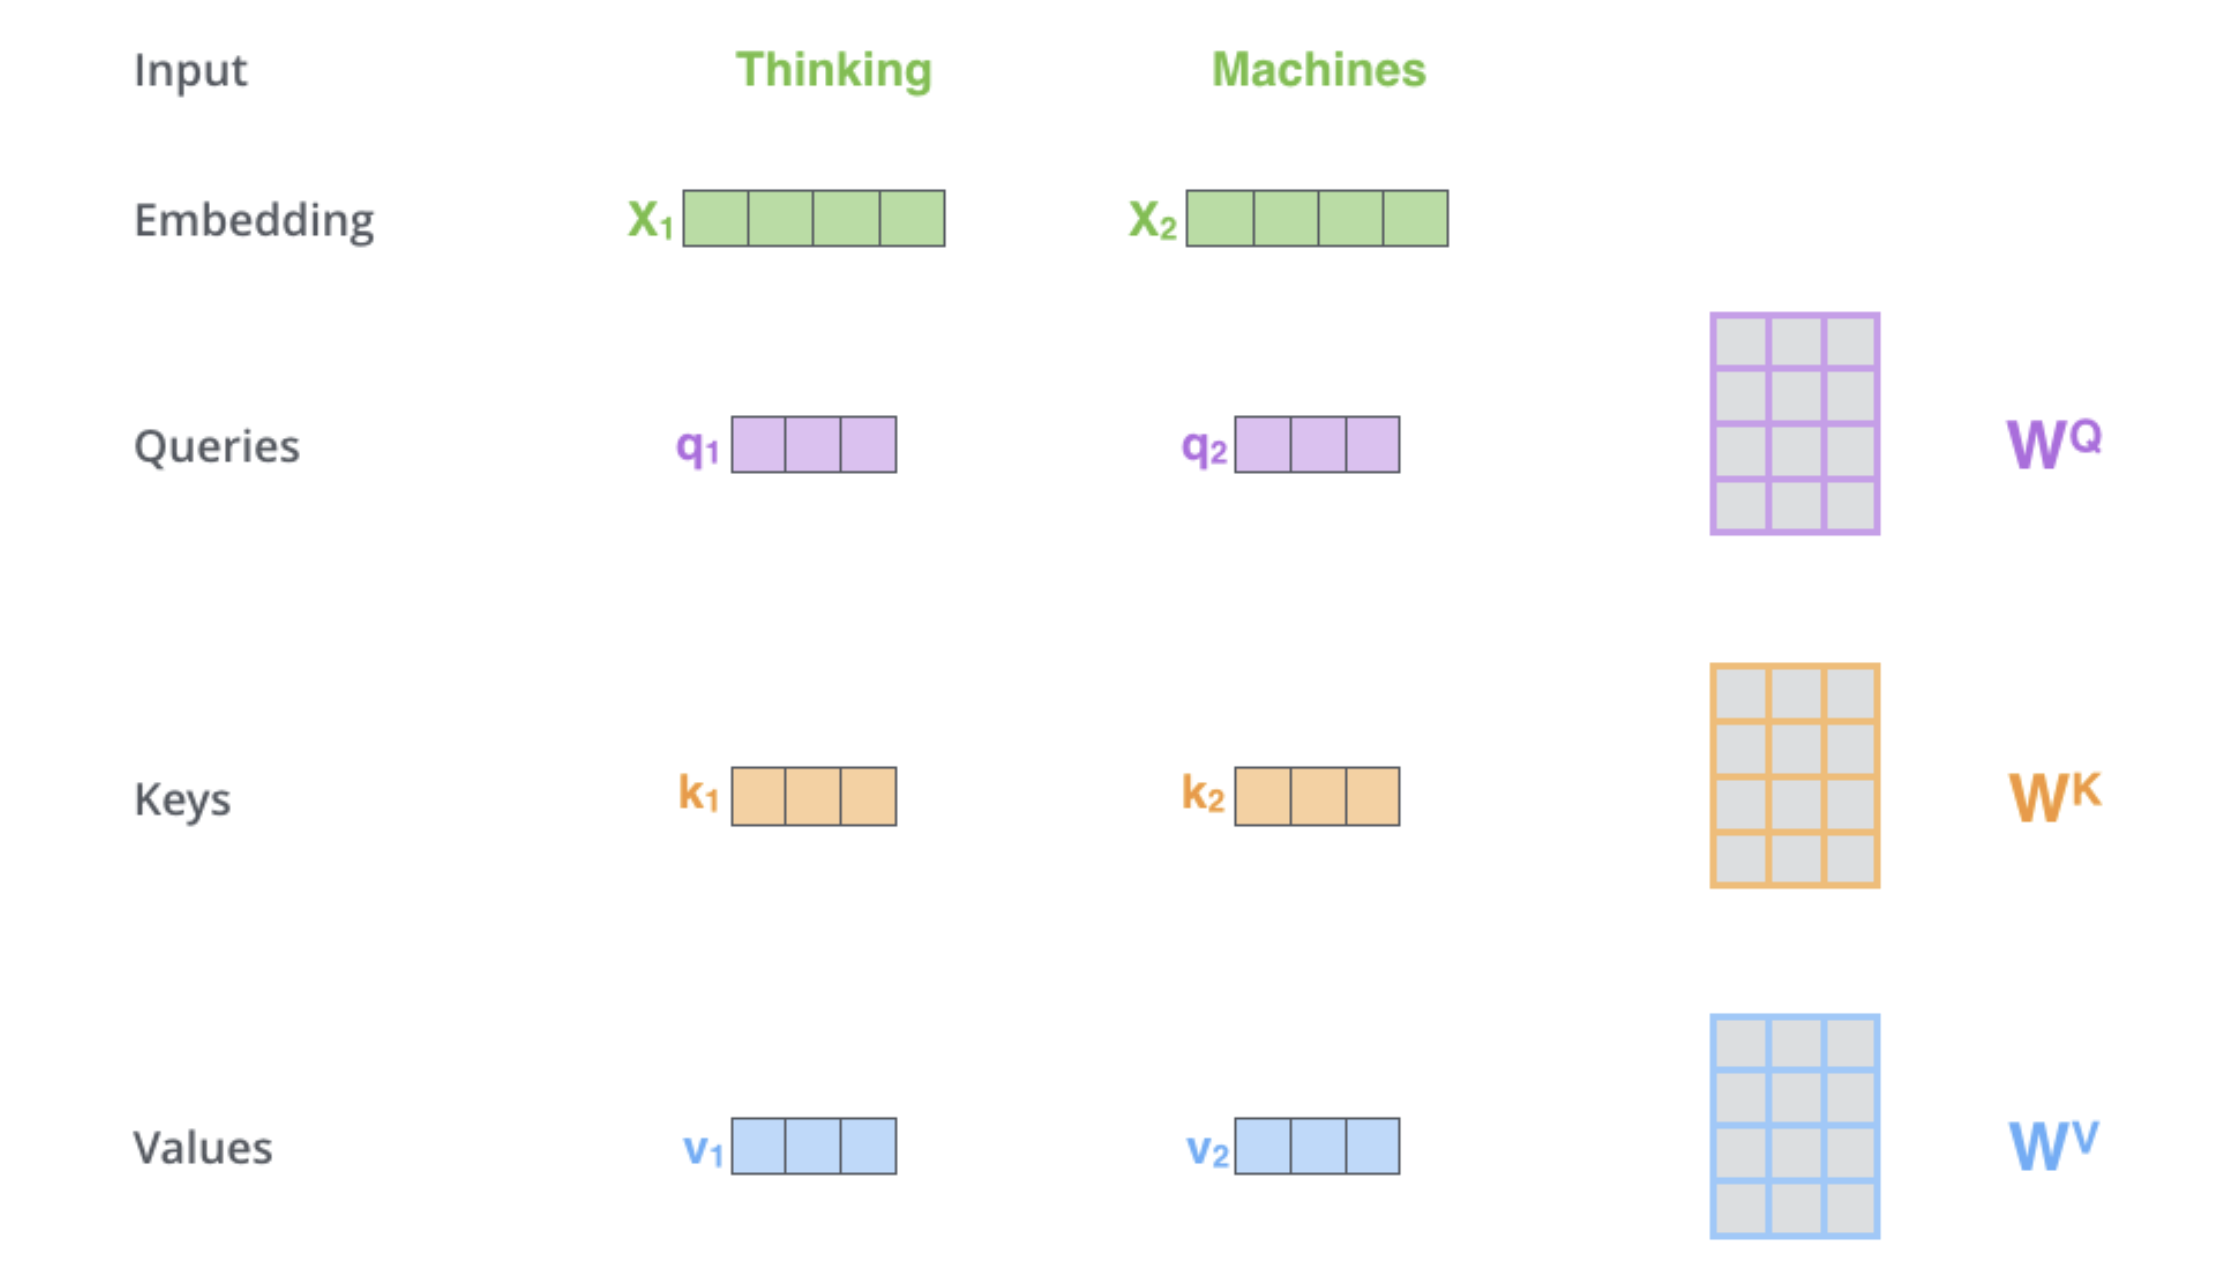
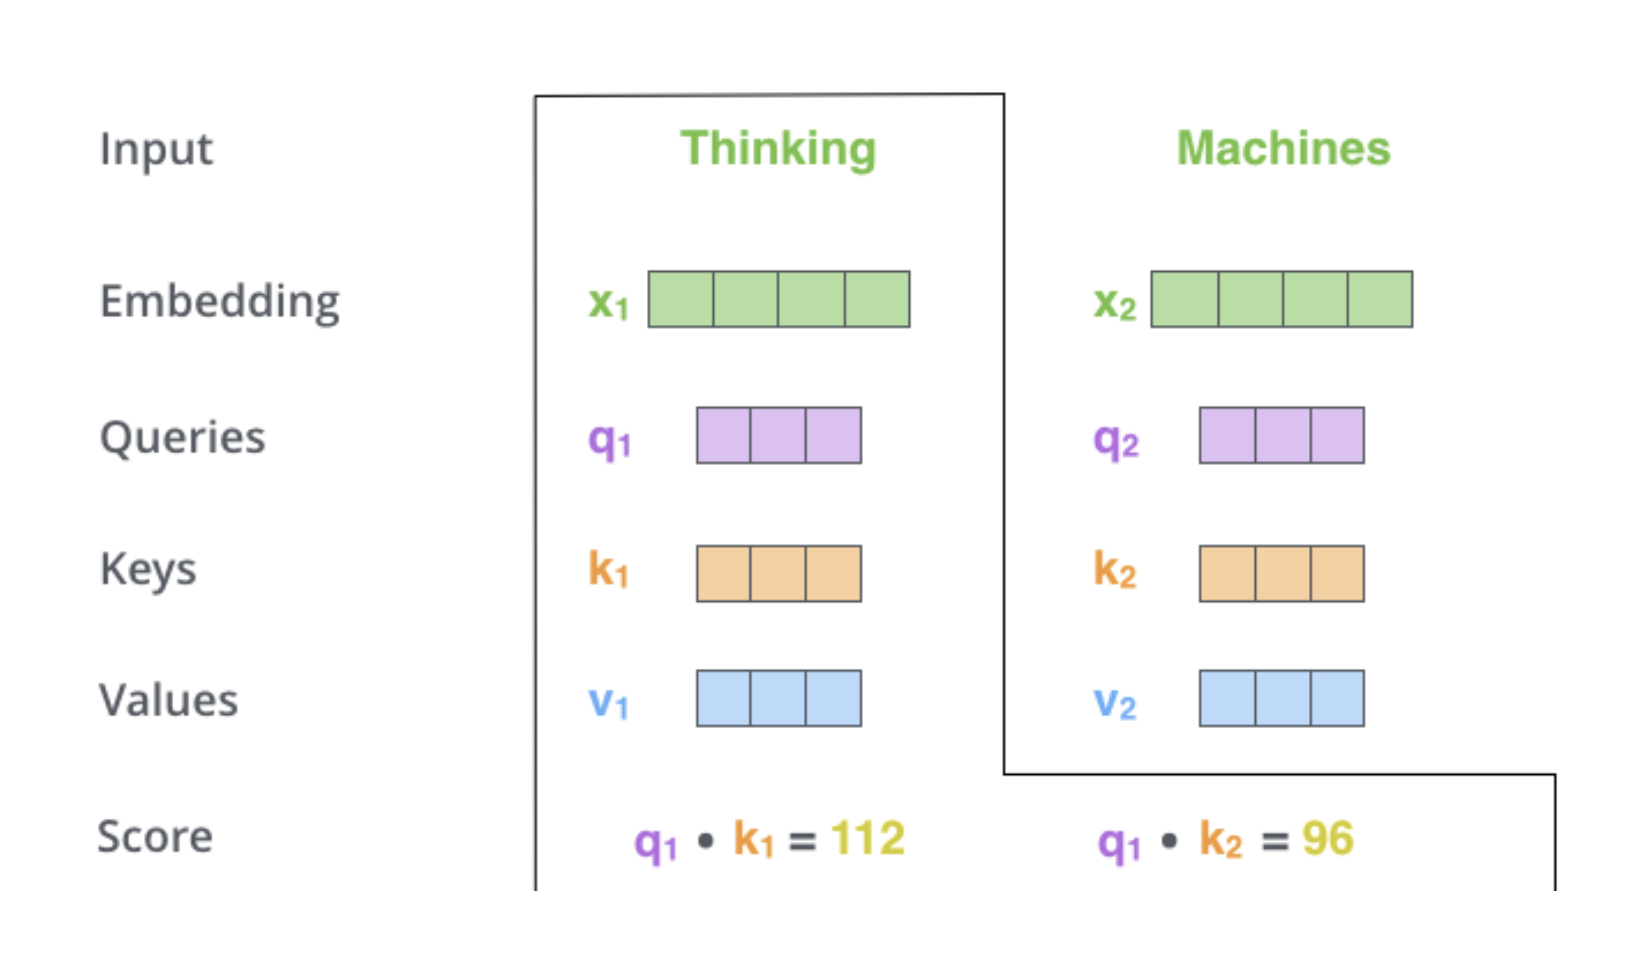
Let be a sequence of words in vocabulary 𝑉, like Zuko made his uncle tea.
For each , let , where is an embedding matrix.
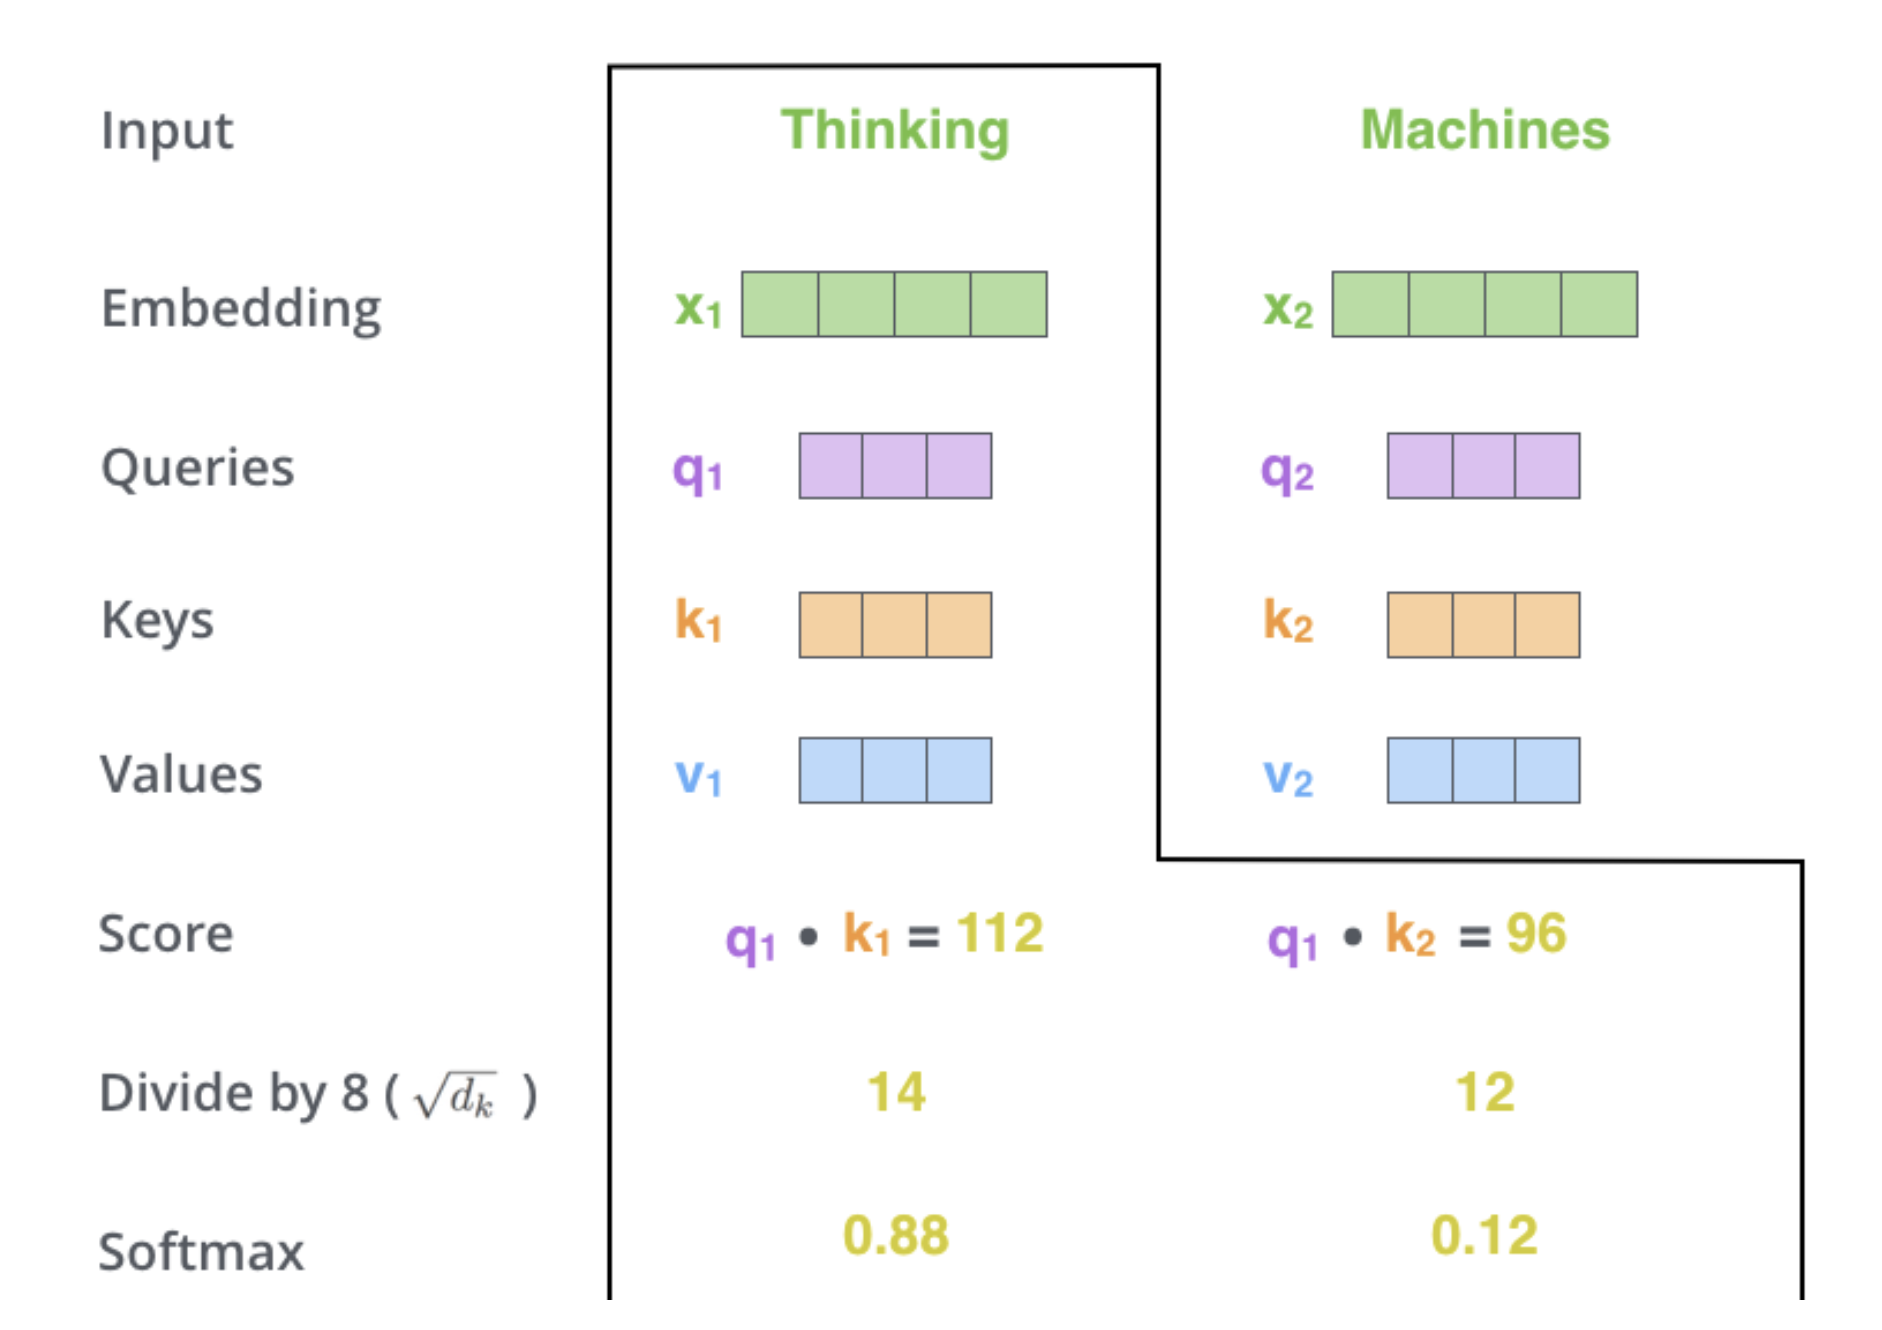
Transform each word embedding with weight matrices , each in
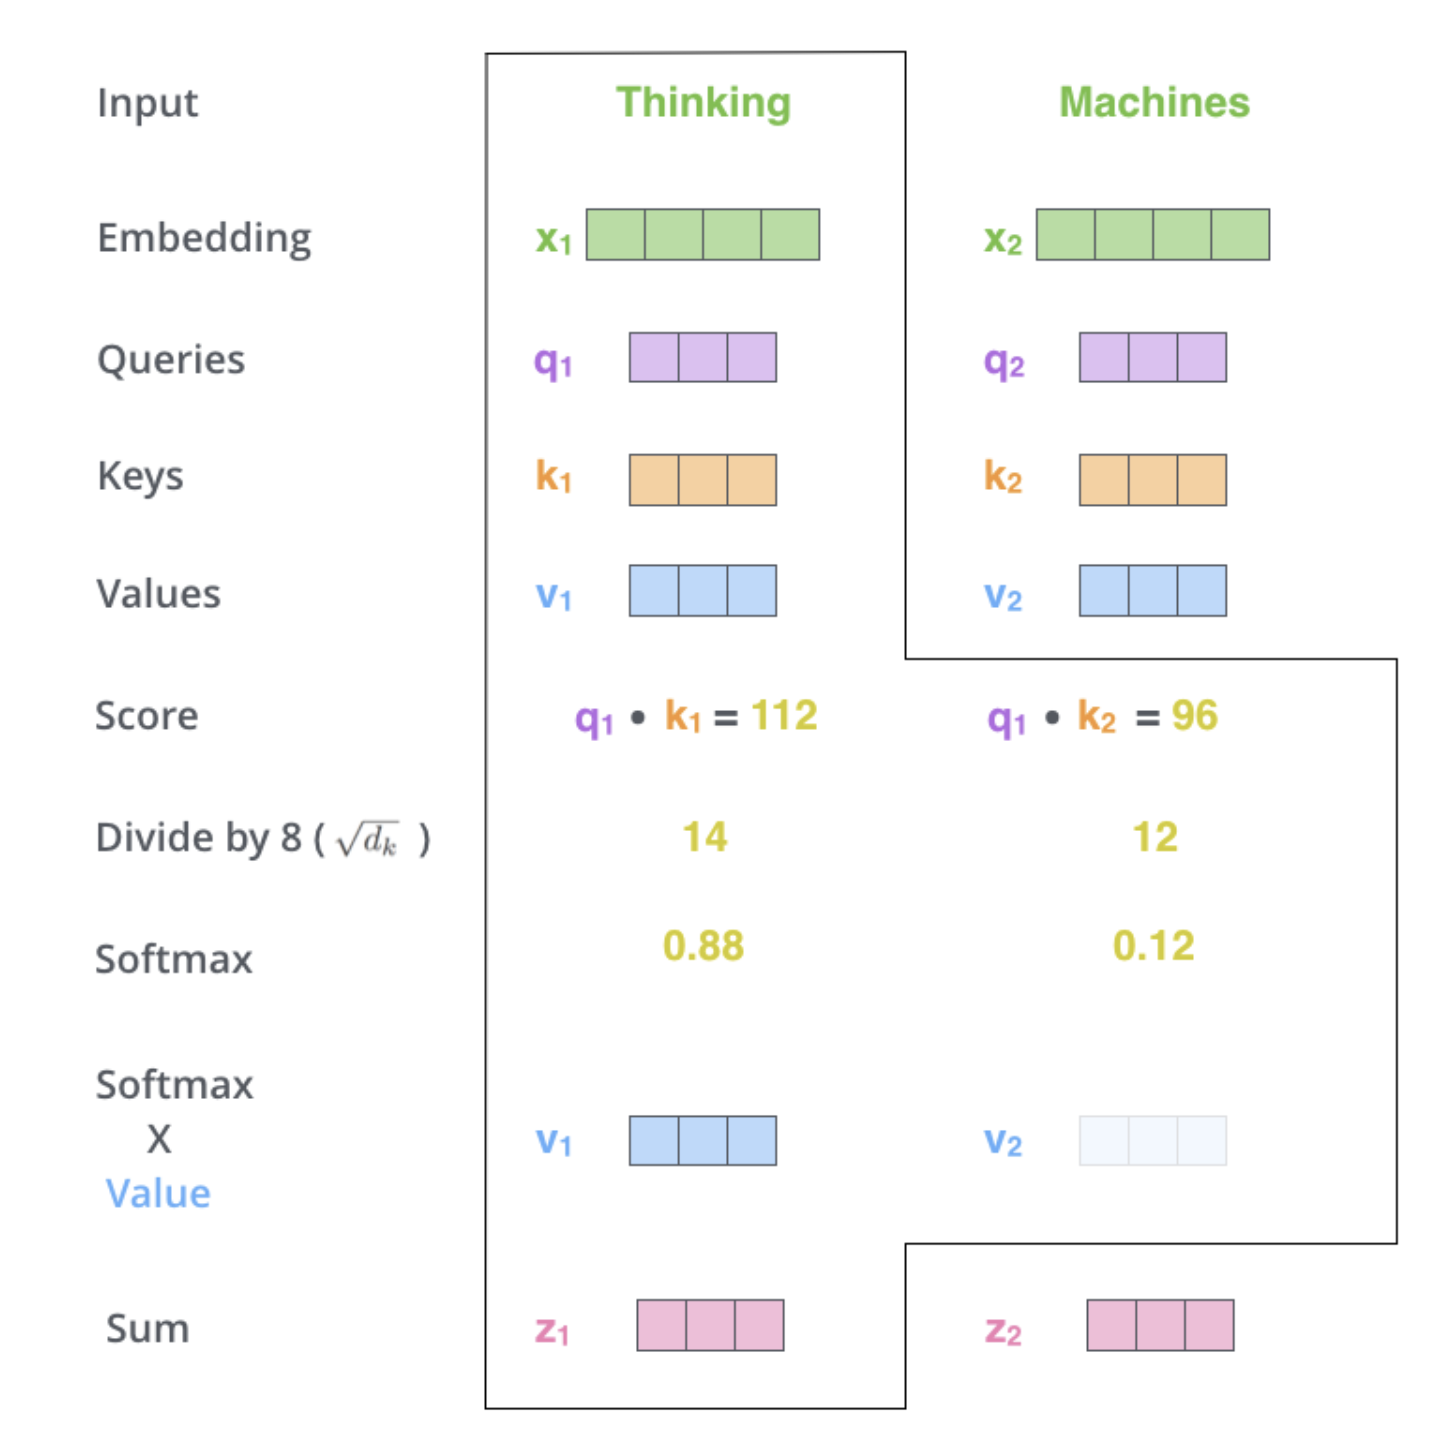
Compute pairwise similarities between keys and queries; normalize with softmax
Compute output for each word as weighted sum of values
Implementation
Implementation
https://jalammar.github.io/illustrated-transformer/
Implementation
Implementation
https://jalammar.github.io/illustrated-transformer/
Implementation
Implementation
https://jalammar.github.io/illustrated-transformer/
Implementation
Implementation
https://jalammar.github.io/illustrated-transformer/
Matrix Calculation
Matrix Calculation
https://jalammar.github.io/illustrated-transformer/
Matrix Calculation
Matrix Calculation
https://jalammar.github.io/illustrated-transformer/
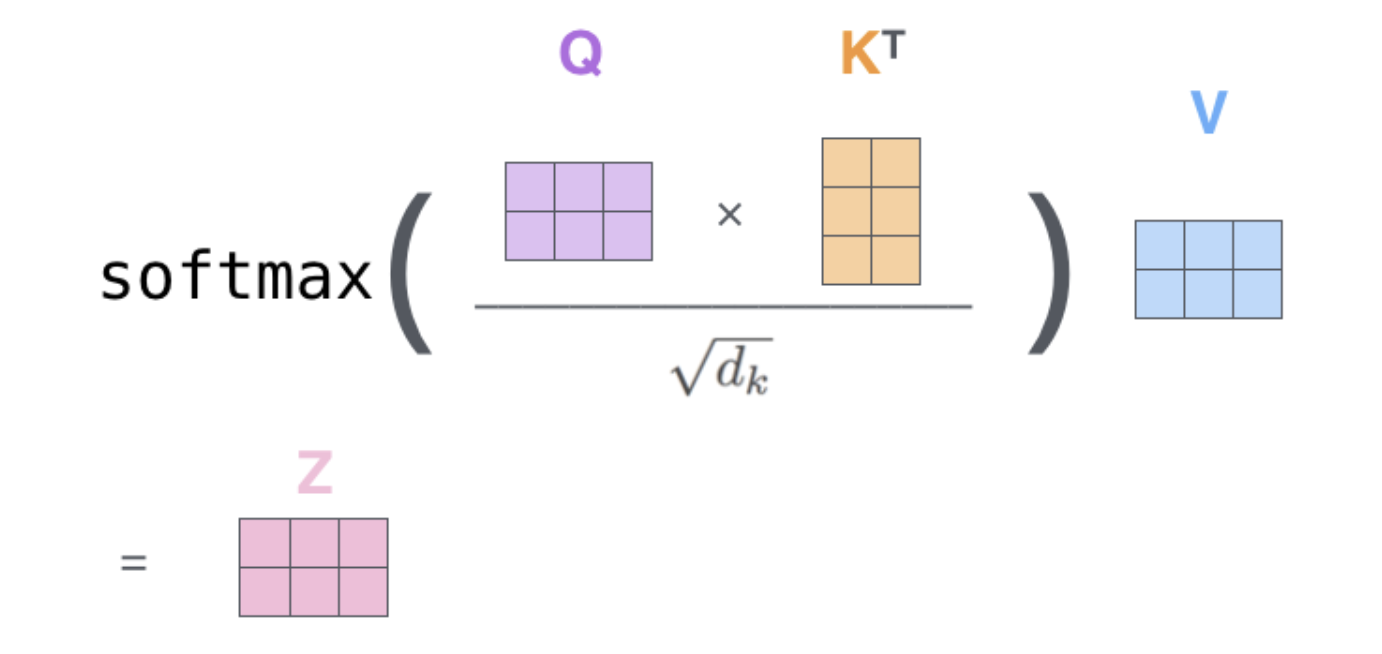
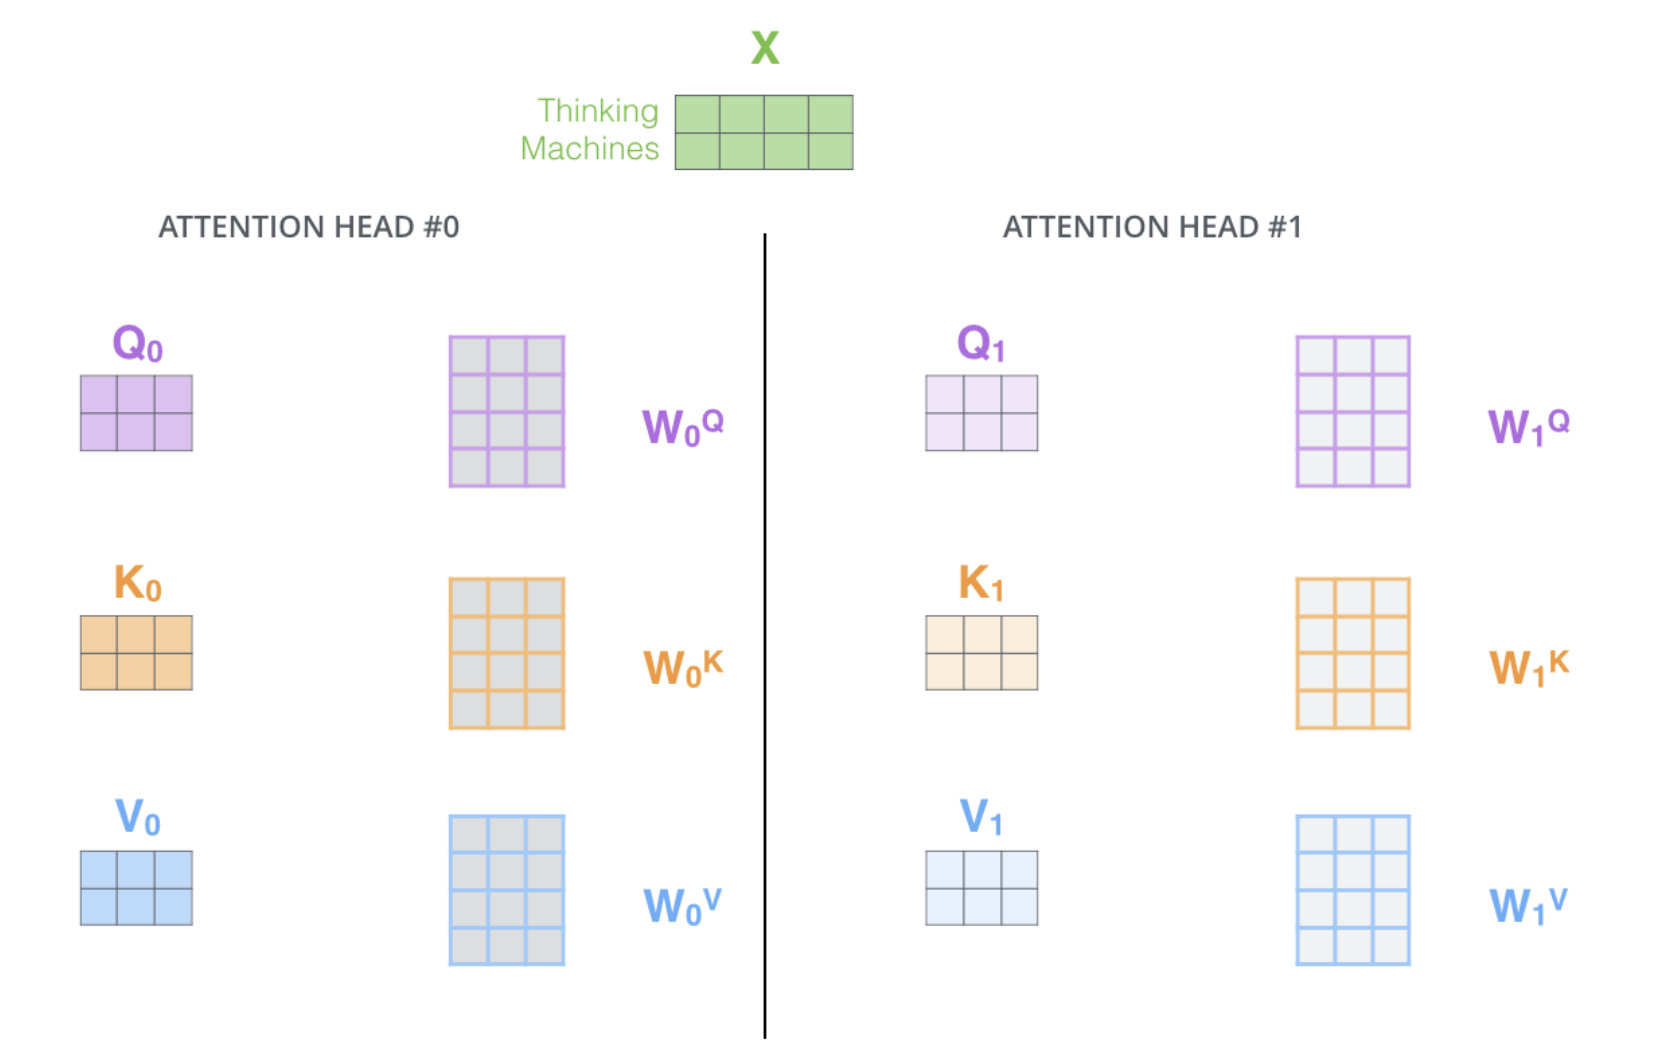
Multi-Head
Multi-Head
https://jalammar.github.io/illustrated-transformer/
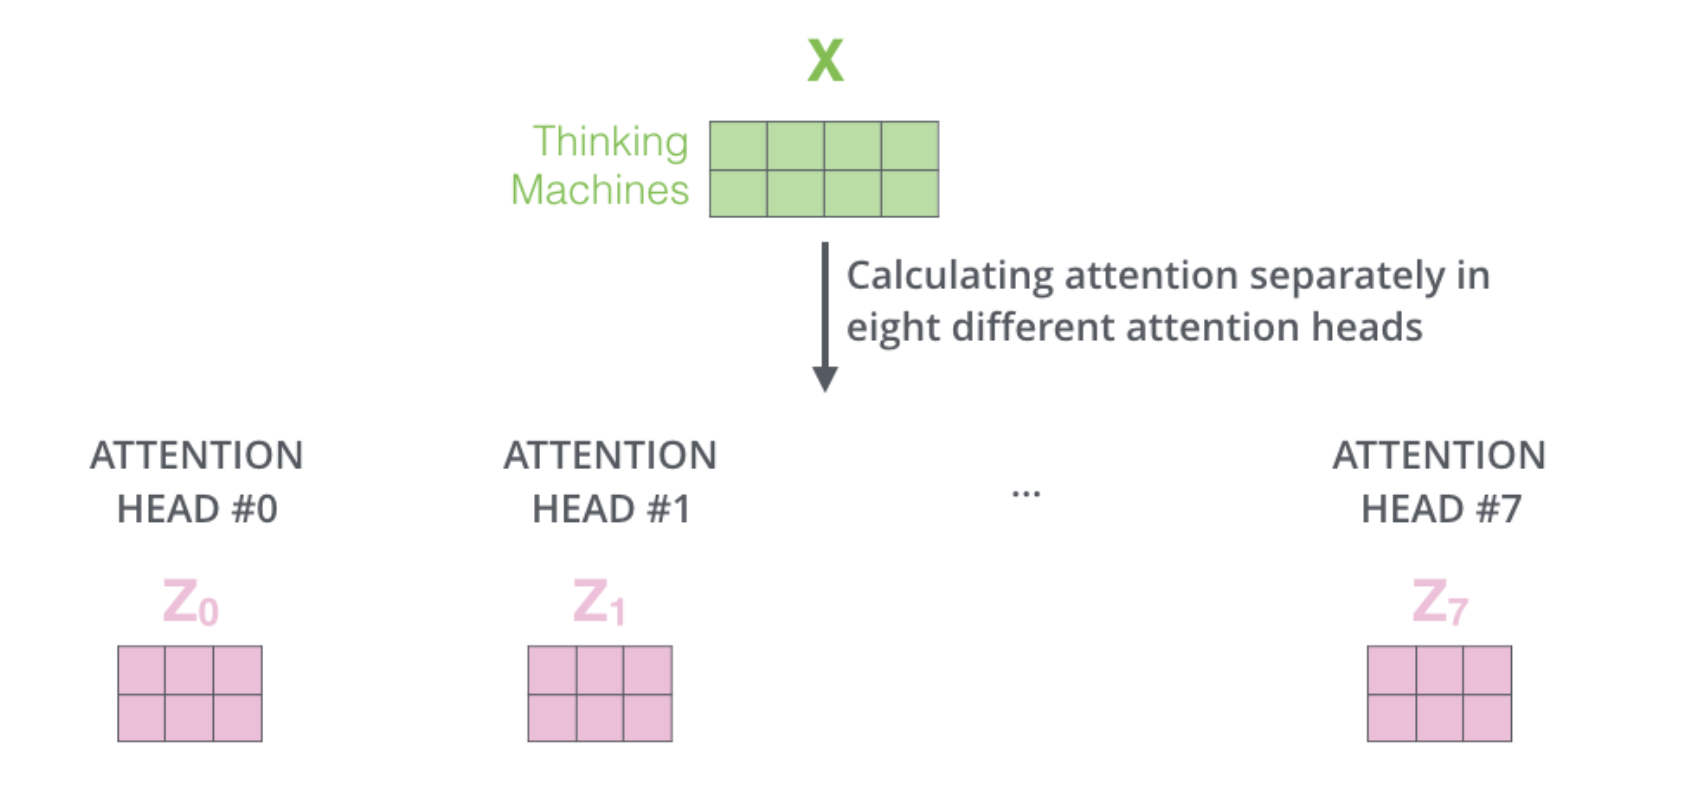
Multi-Head
Multi-Head
https://jalammar.github.io/illustrated-transformer/
Multi-Head
Multi-Head
https://jalammar.github.io/illustrated-transformer/
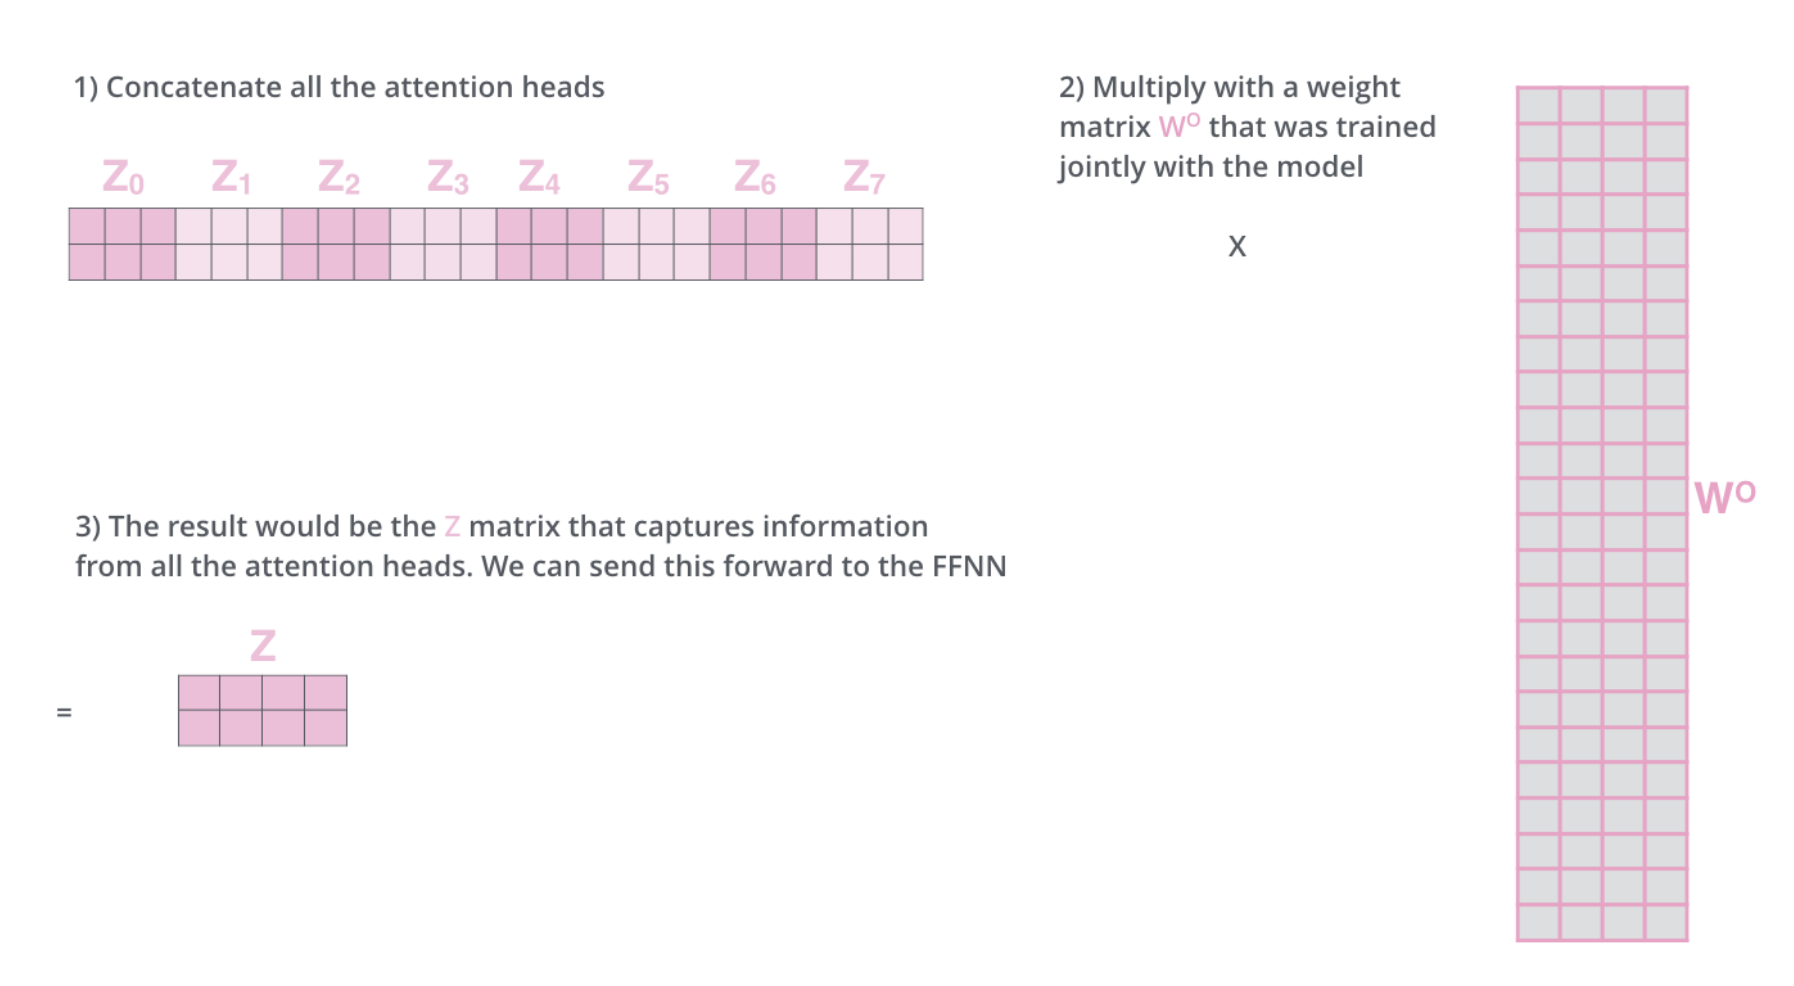
Multi-Head
Multi-Head
https://jalammar.github.io/illustrated-transformer/
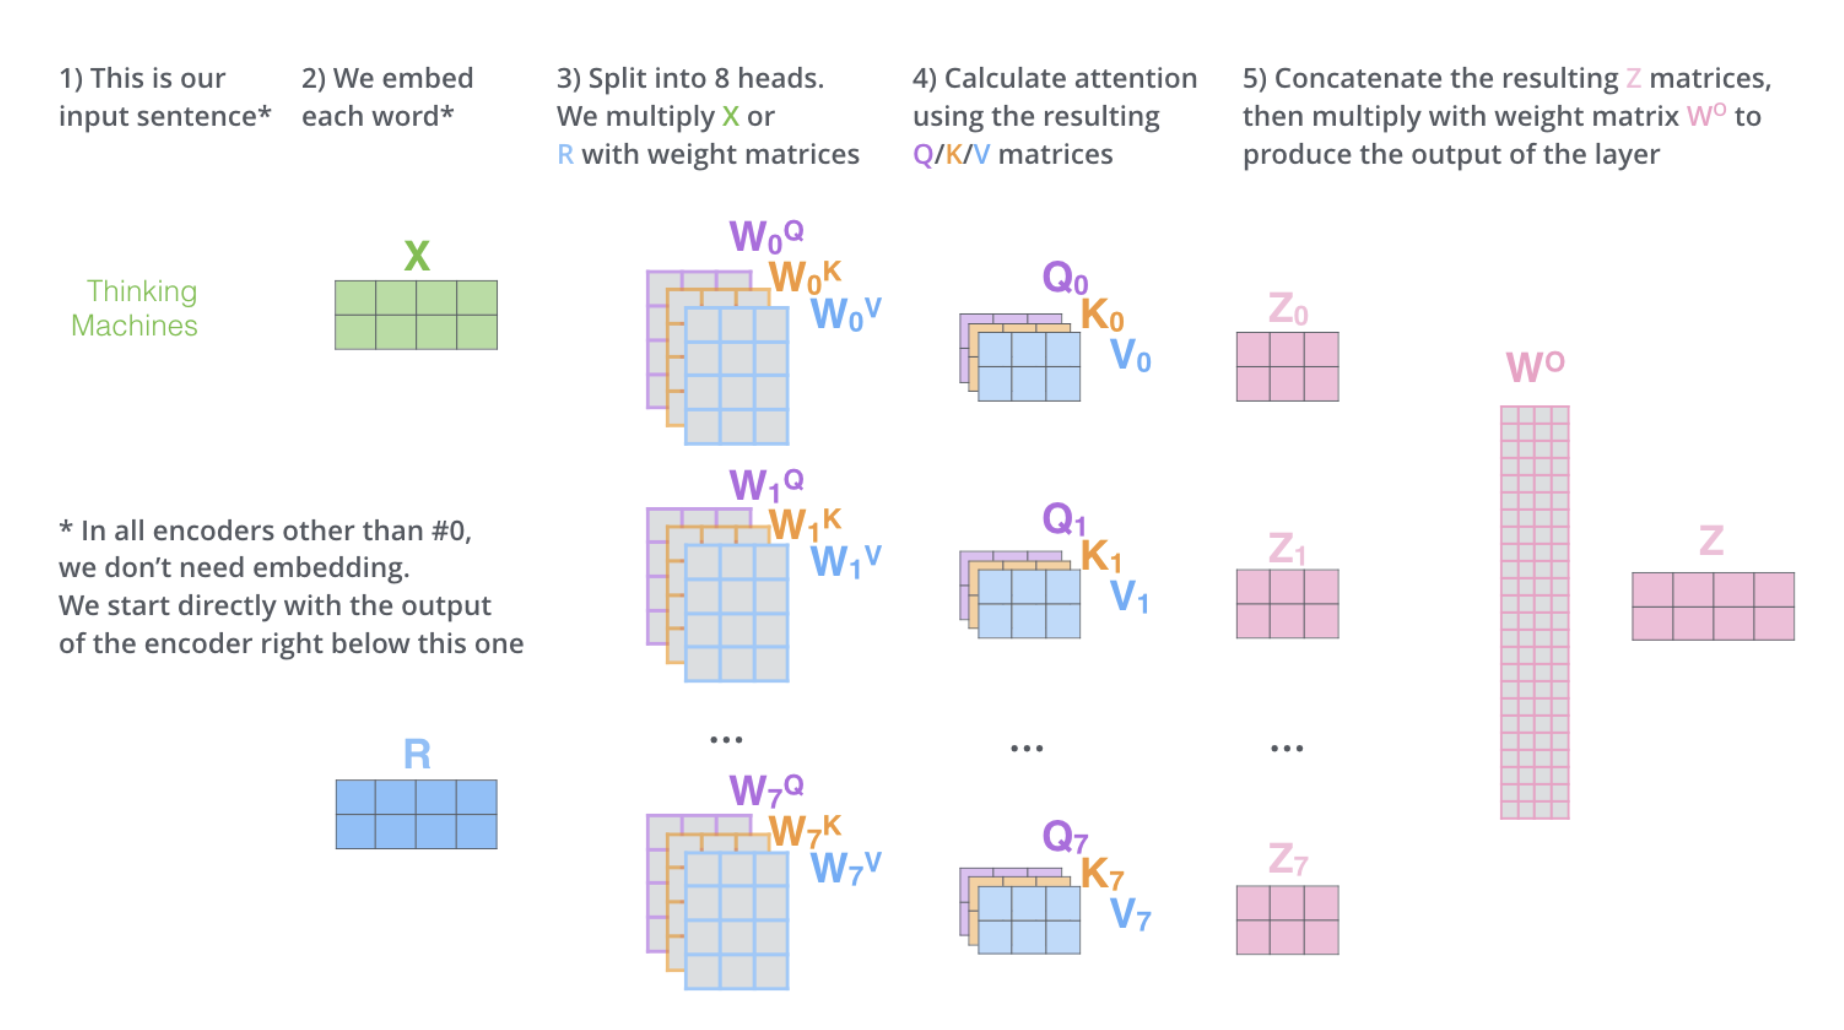
Multi-Head
Multi-Head
https://jalammar.github.io/illustrated-transformer/
2.2 Transformer 2.2.6 Feed-Forward Networks
2.2 Transformer 2.2.6 Feed-Forward Networks
Feed-Forward
Feed-Forward
https://jalammar.github.io/illustrated-transformer/
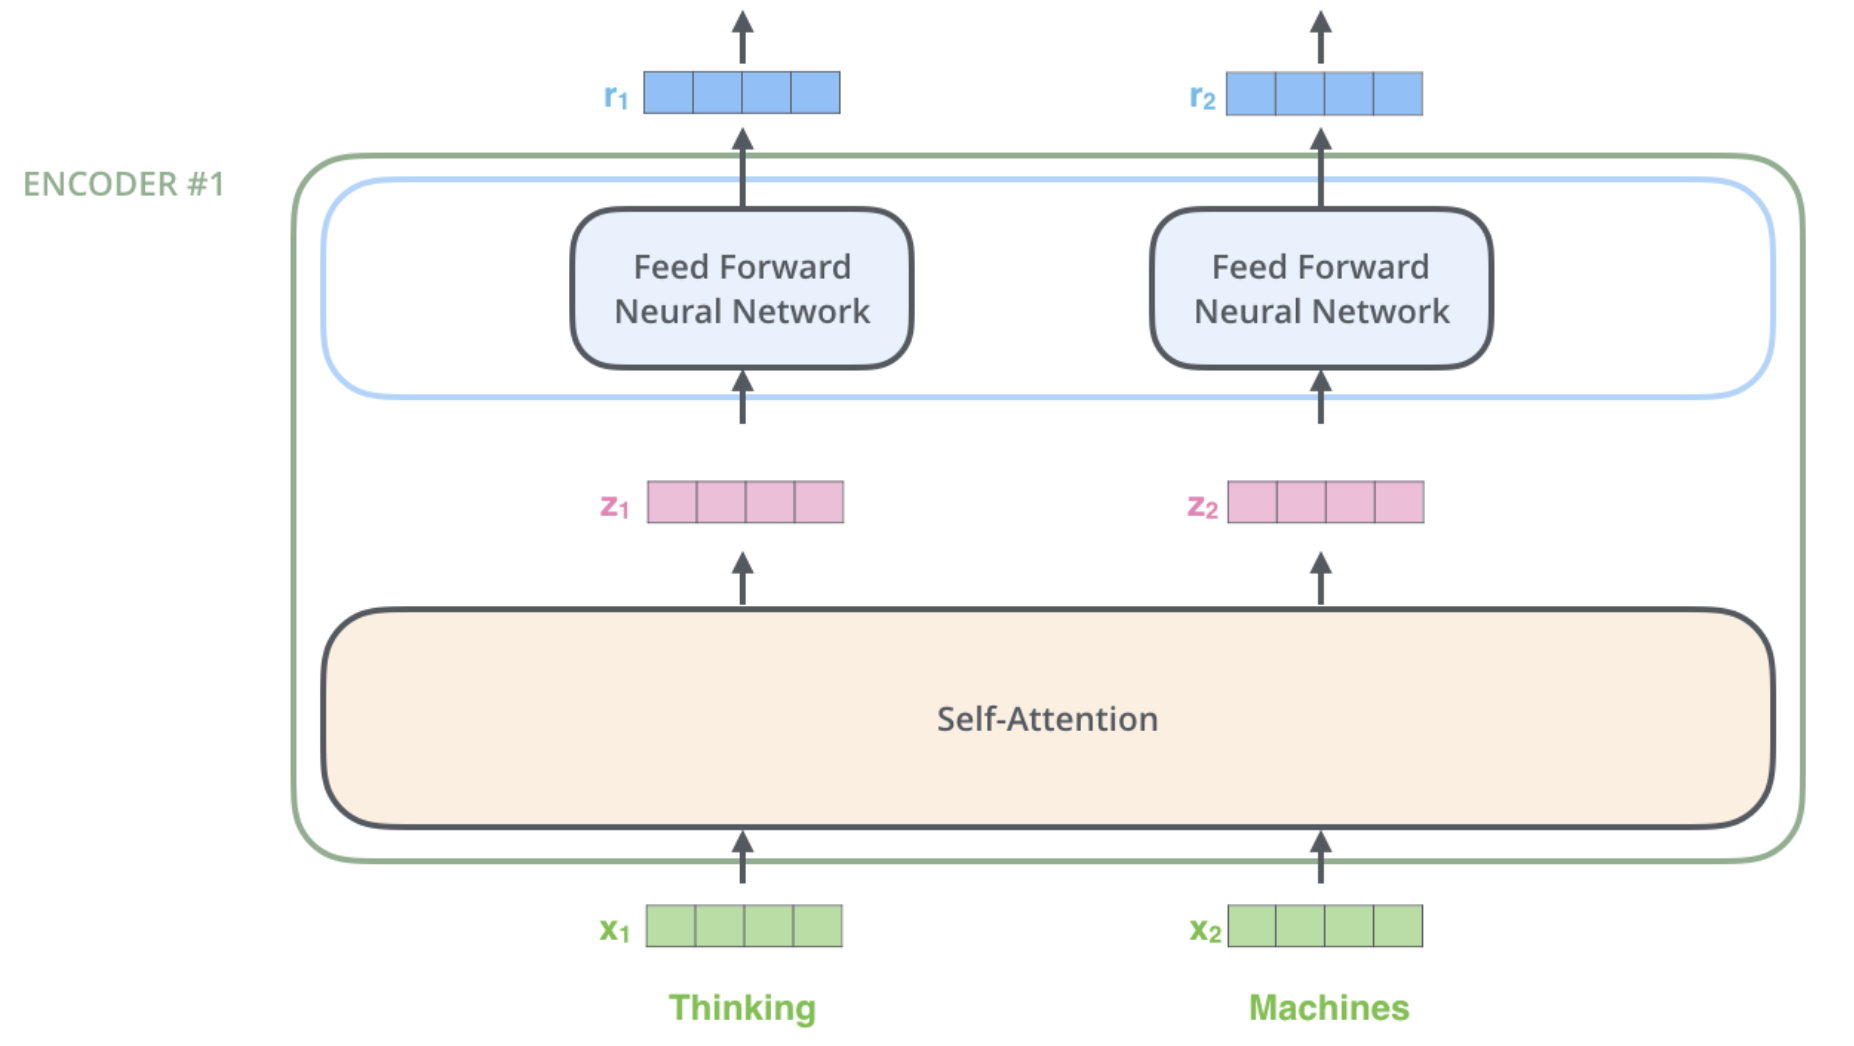
Feed-Forward
Feed-Forward
Attention decides “who is important”, while Feedforward decides “how to interpret this information.”
Expanding dimensions gives the model more room for transformation
Reducing dimensions back to the original size for residual connection
2.2 Transformer 2.2.7 Positional Encoding
2.2 Transformer 2.2.7 Positional Encoding
From hidden Order Info to Position Feature
From hidden Order Info to Position Feature
https://jalammar.github.io/illustrated-transformer/
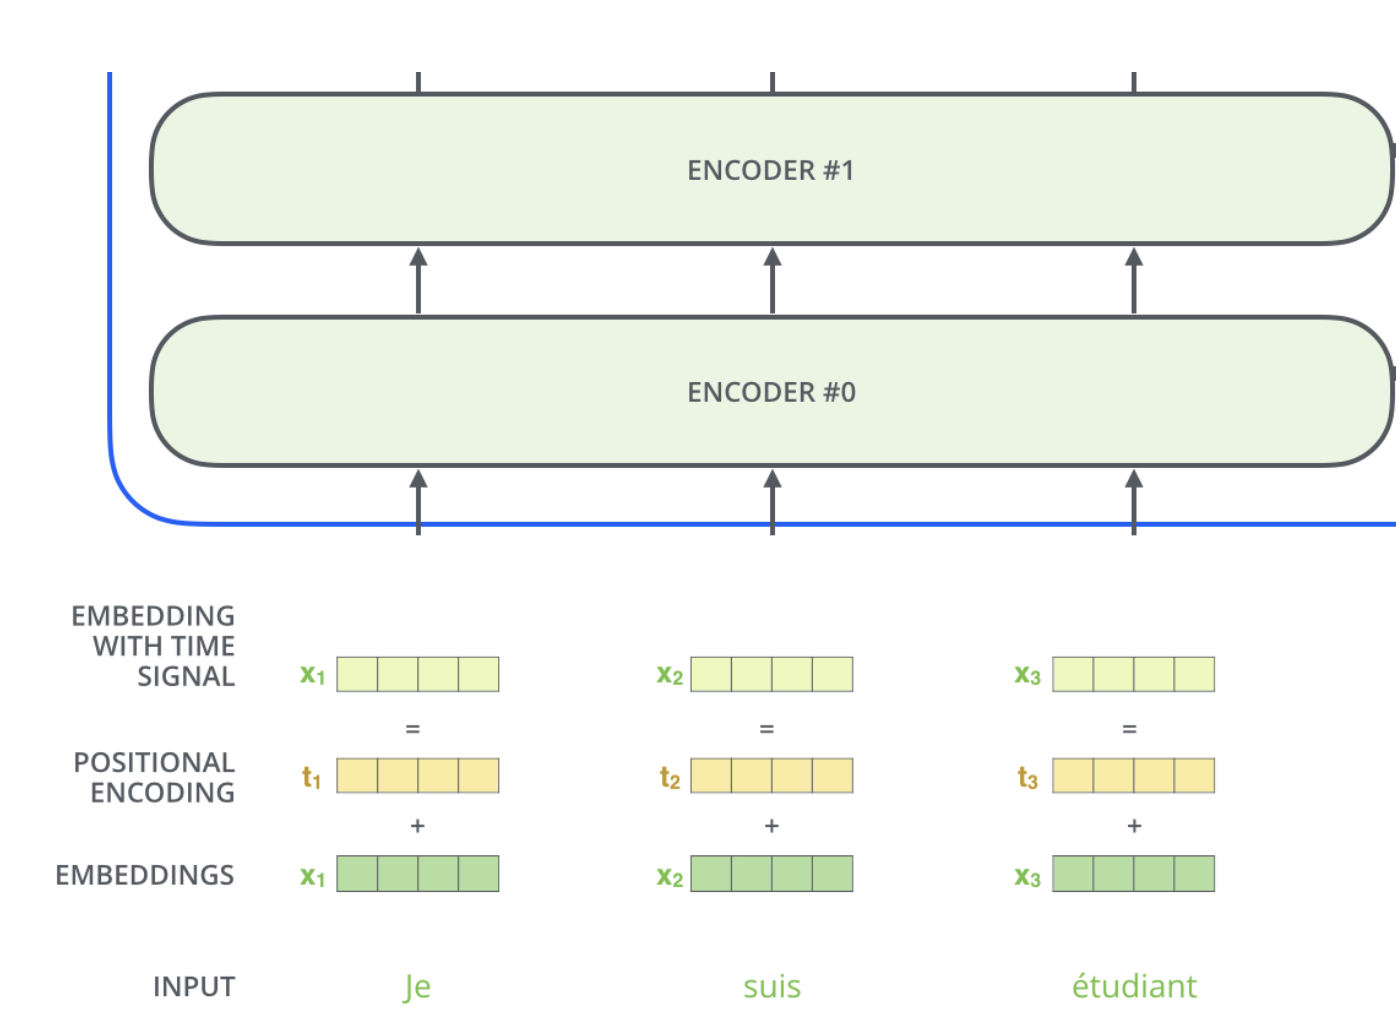
The Embedding of Position
The Embedding of Position
https://jalammar.github.io/illustrated-transformer/
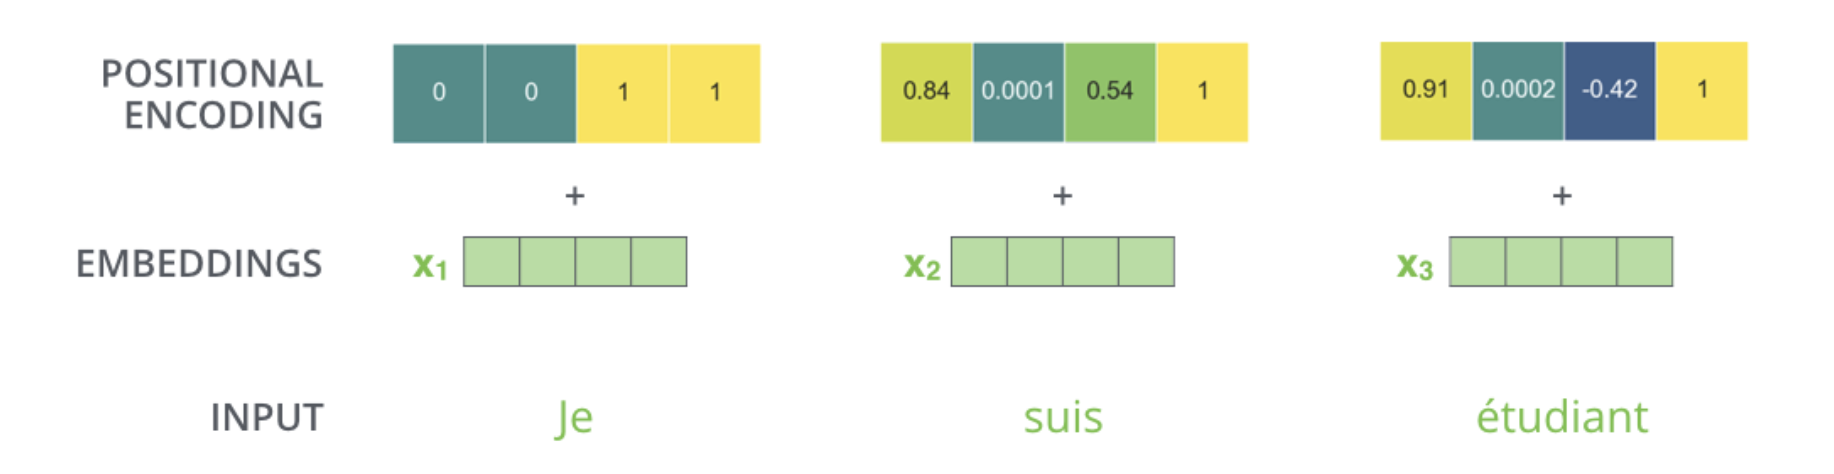
Consider representing each sequence index as a vector:
, for
Easy to incorporate into our self-attention block: just add the to our inputs!
Recall that is the embedding of the word at index . The positioned embedding is:
The Embedding of Position
The Embedding of Position
https://machinelearningmastery.com/a-gentle-introduction-to-positional-encoding-in-transformer-models-part-1/
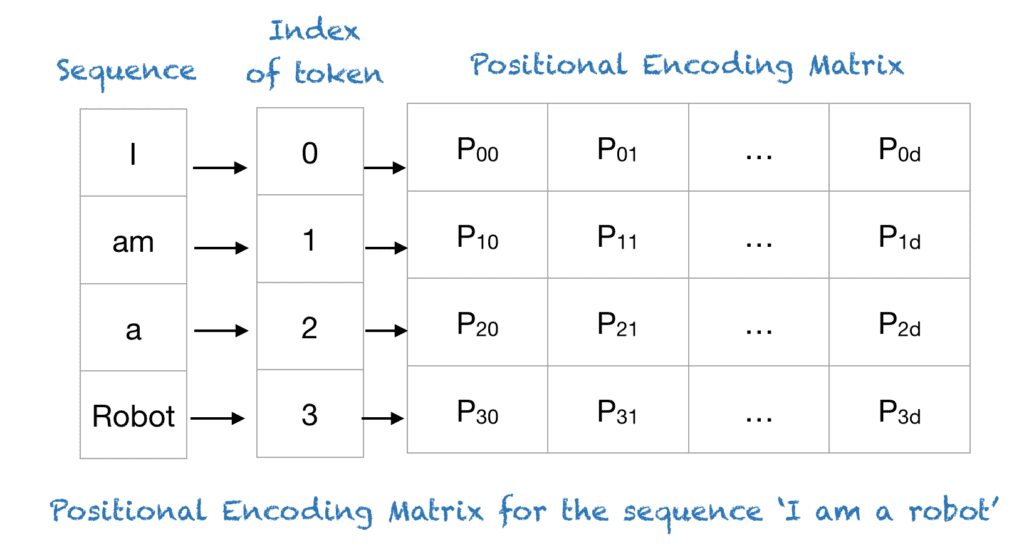
Sinusoidal Position Representations
Sinusoidal Position Representations
https://machinelearningmastery.com/a-gentle-introduction-to-positional-encoding-in-transformer-models-part-1/
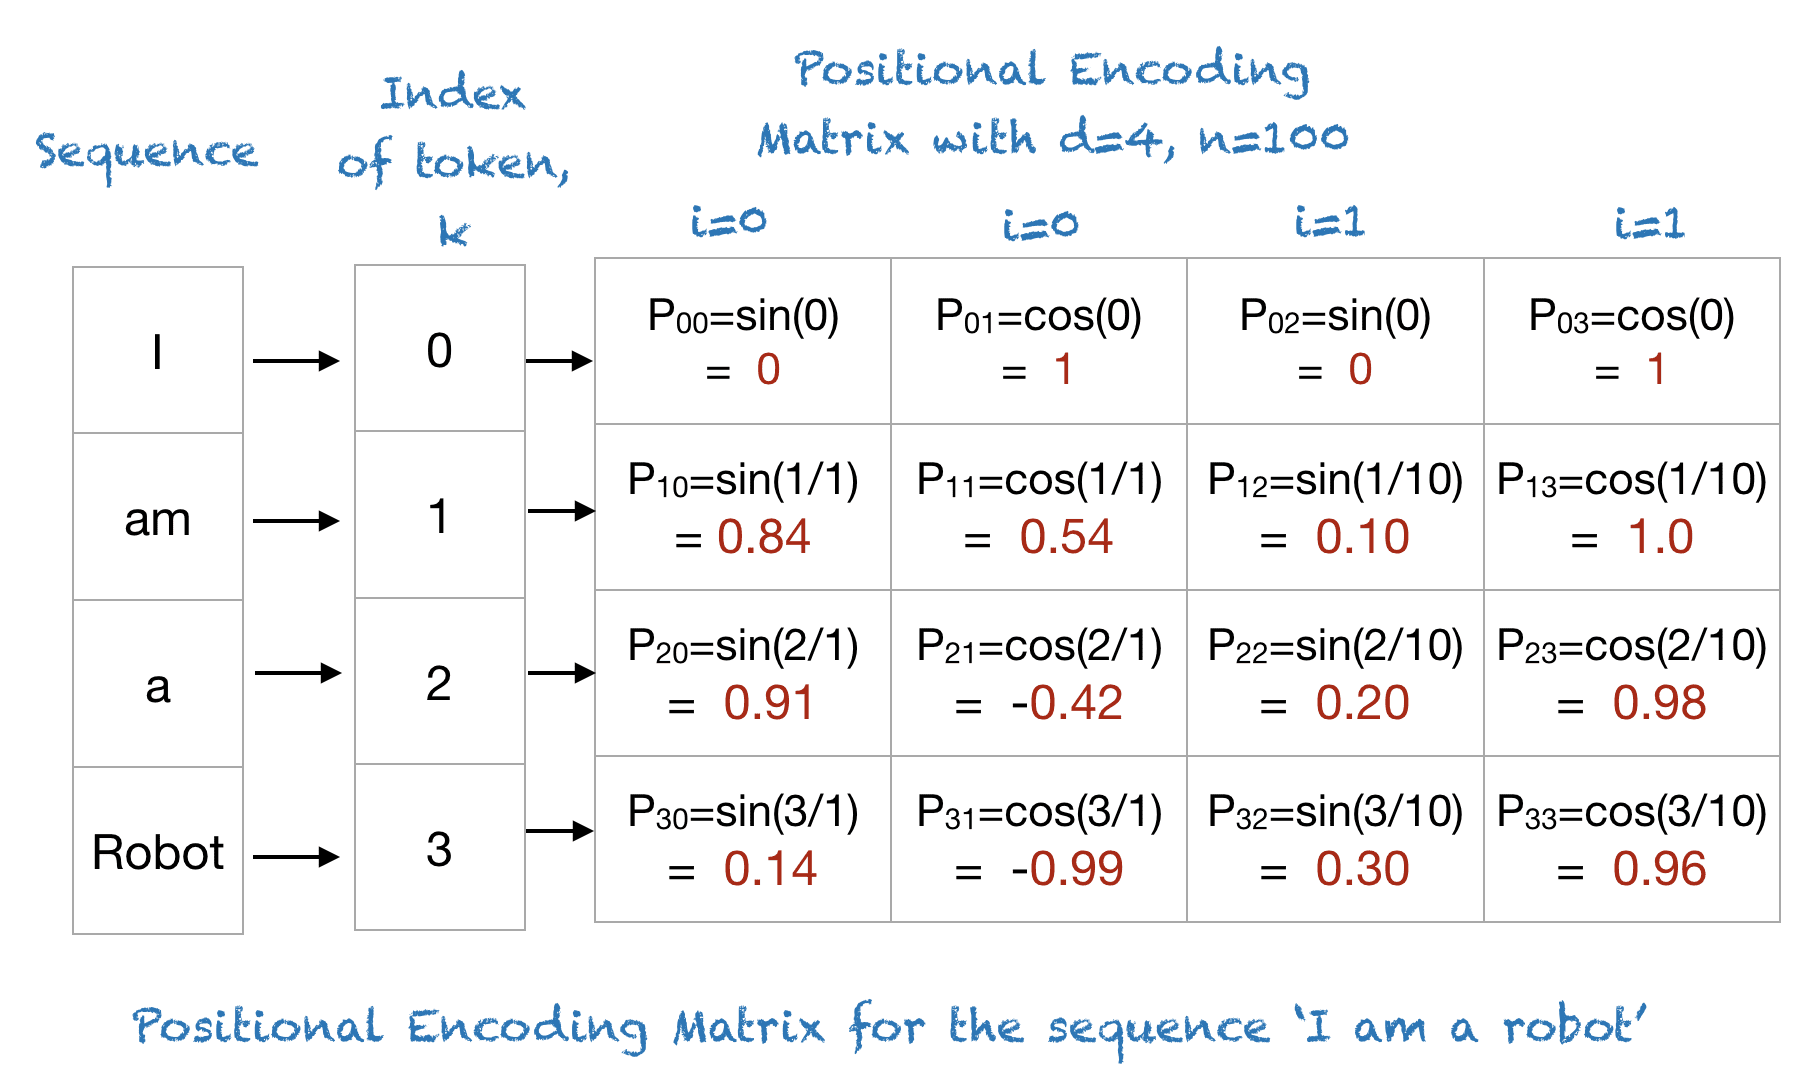
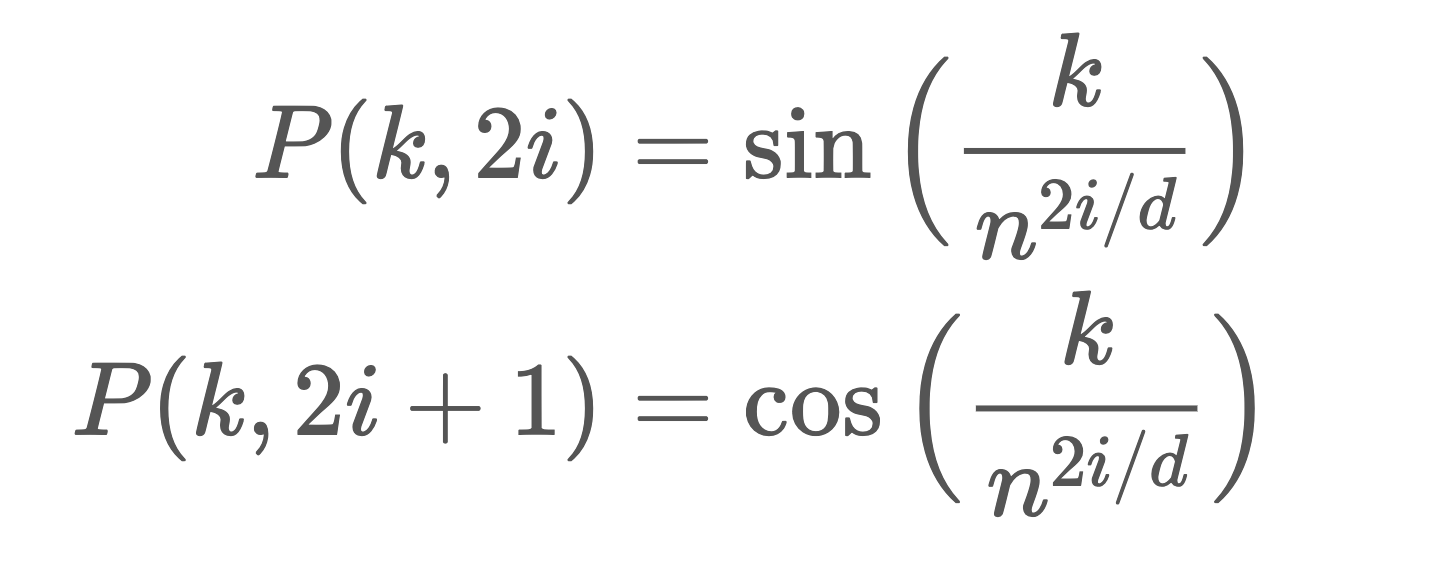
Why this Form?
Why this Form?
https://machinelearningmastery.com/a-gentle-introduction-to-positional-encoding-in-transformer-models-part-1/
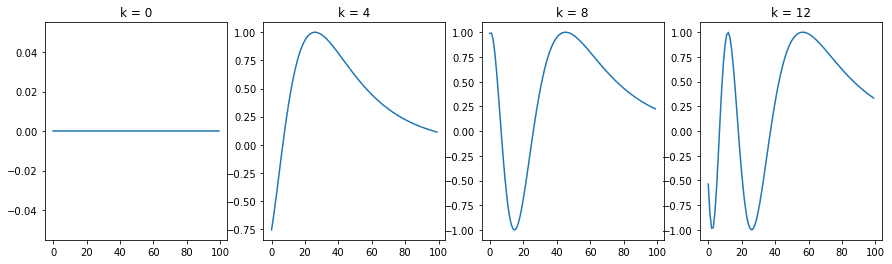
Visualization
Visualization
https://machinelearningmastery.com/a-gentle-introduction-to-positional-encoding-in-transformer-models-part-1/
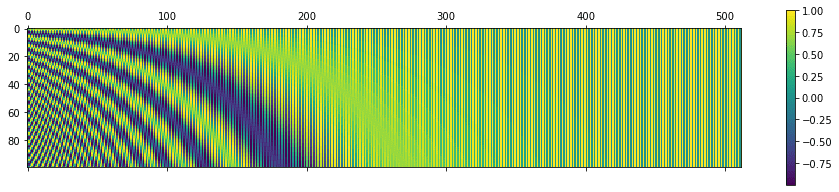
The positional encoding matrix for n=10,000, d=512, sequence length=100
2.2 Transformer 2.2.8 Masking the Future
2.2 Transformer 2.2.8 Masking the Future
Decoder: Mask the Future
Decoder: Mask the Future
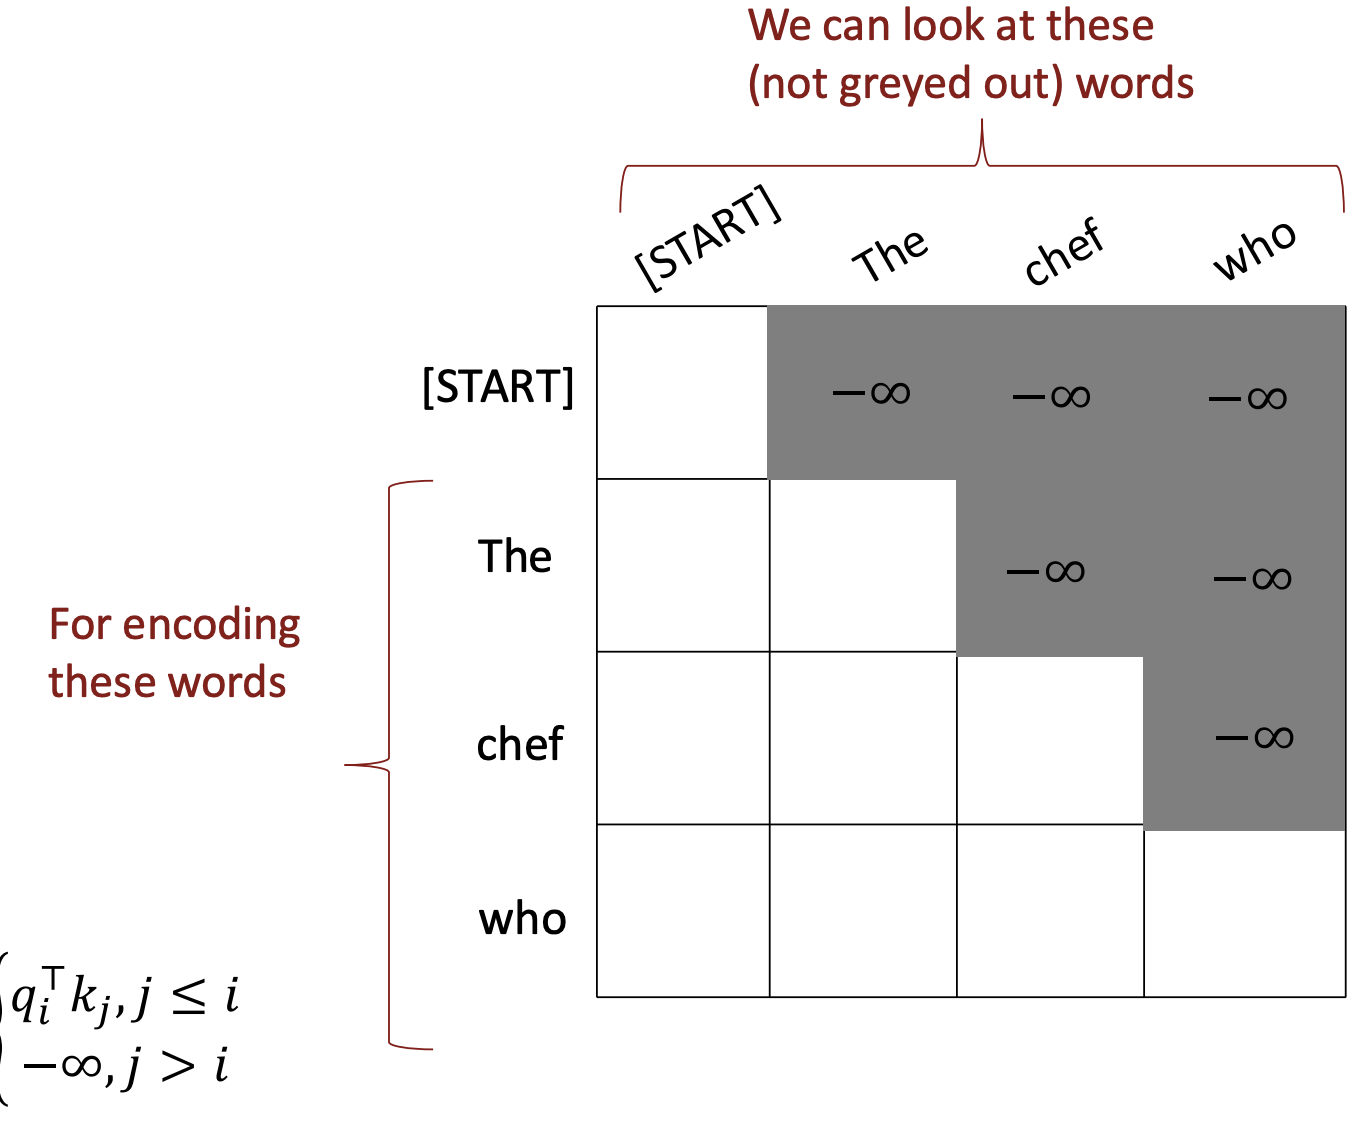
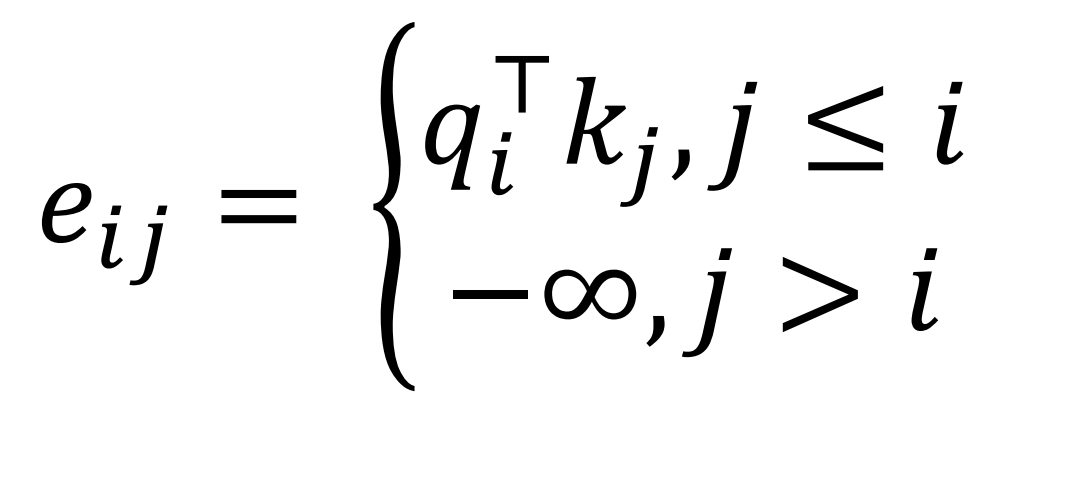
When applying self-attention in decoder, we must ensure we cannot depend on future.
2.2 Transformer 2.2.9 Training Stability
2.2 Transformer 2.2.9 Training Stability
Residual and Normalization
Residual and Normalization
https://jalammar.github.io/illustrated-transformer/
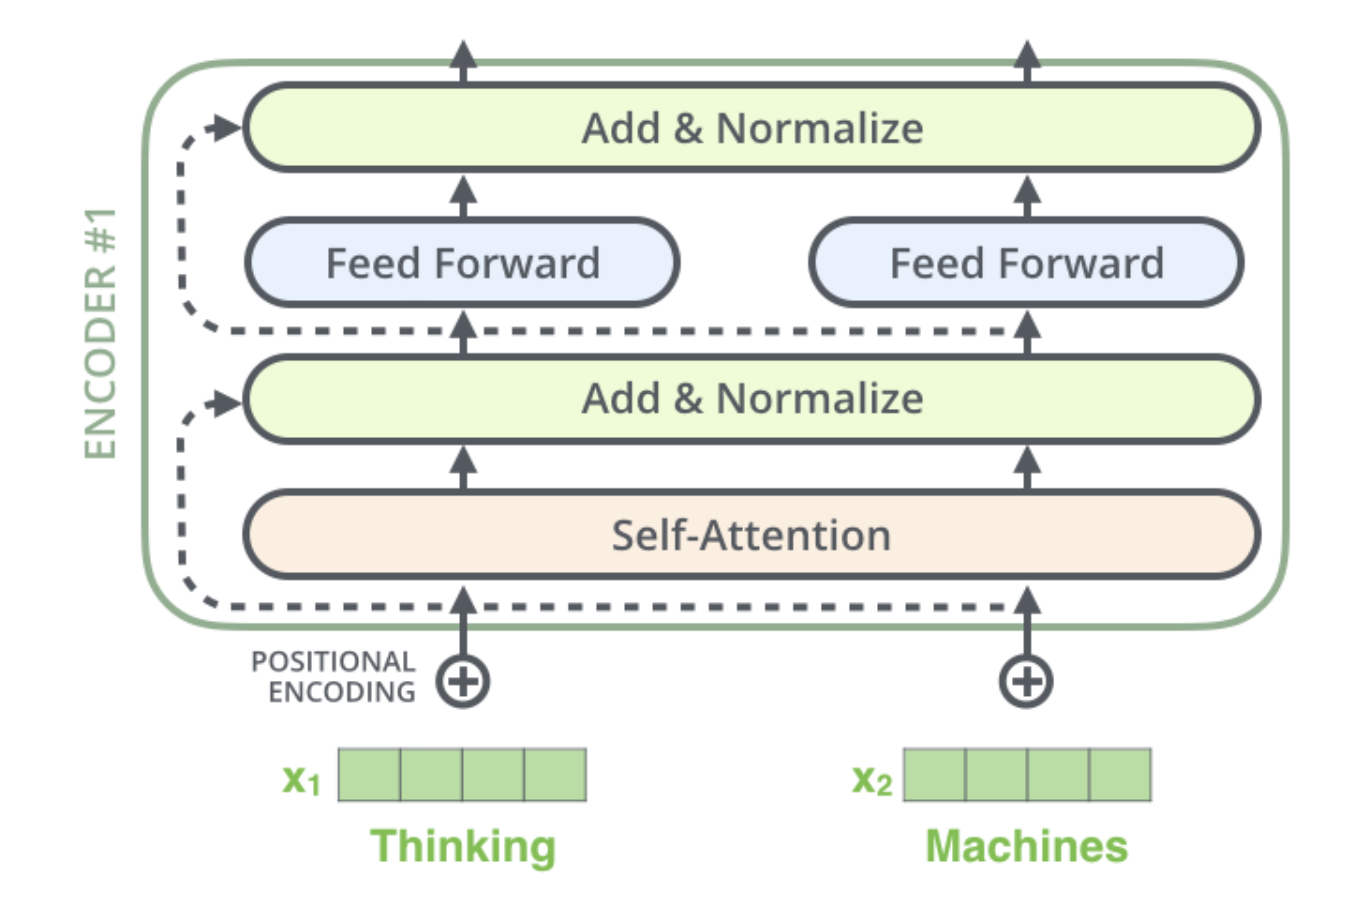
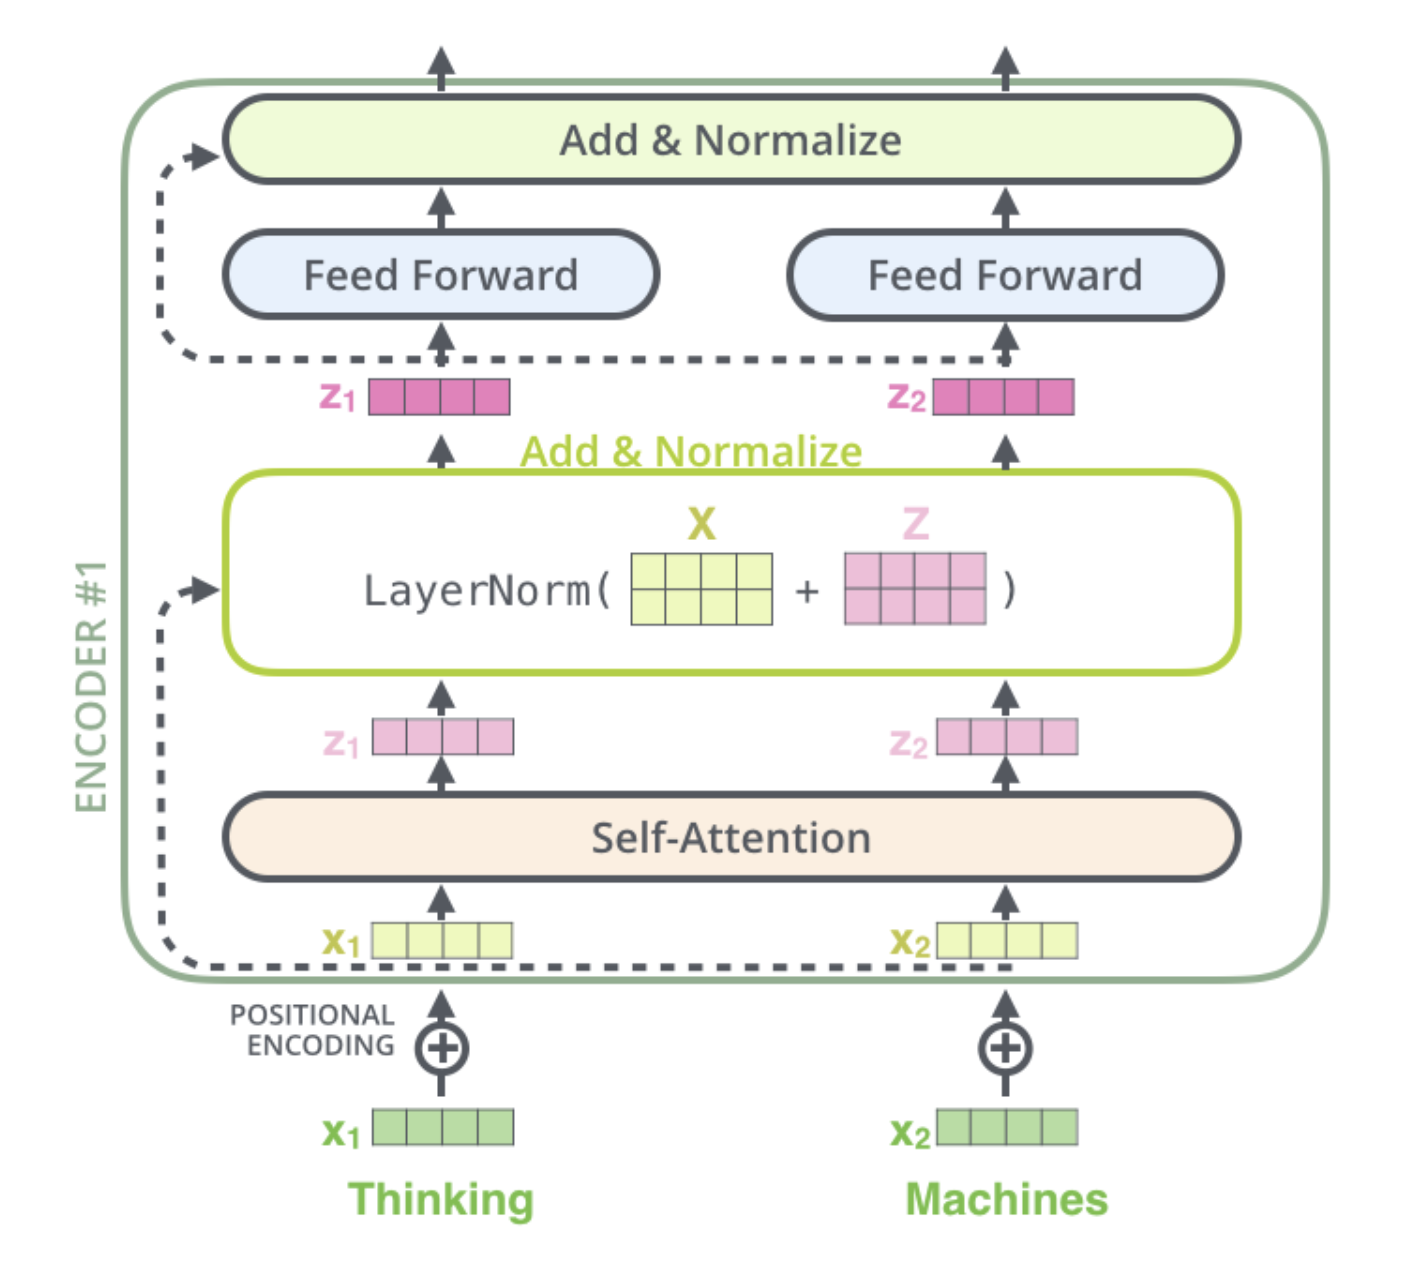
Residual and Normalization
Residual and Normalization
https://jalammar.github.io/illustrated-transformer/
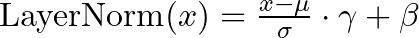
2.2 Transformer 2.2.10 Transformer Block Summary
2.2 Transformer 2.2.10 Transformer Block Summary
Building Blocks
Building Blocks
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture08-transformers.pdf
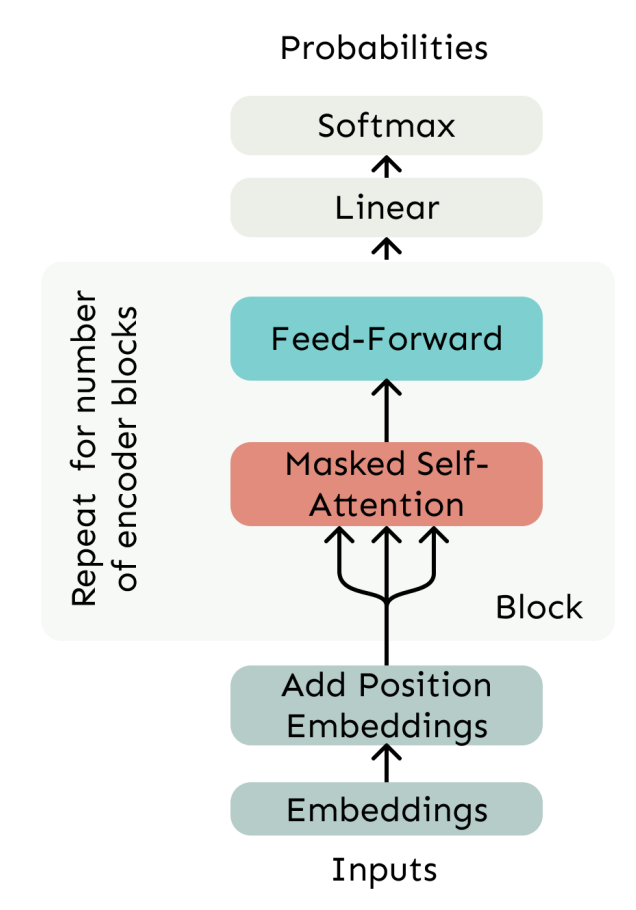
Self-attention:
the basis of the method.
Position representations:
Specify the sequence order, since self-attention is an unordered function of its inputs.
Nonlinearities:
At the output of the self-attention block
Frequently implemented as a simple feedforward network.
Masking:
Parallelize operations while not looking at the future.
Keeps information about the future from “leaking” to the past.
2.2 Transformer 2.2.11 Transformer Architecture
2.2 Transformer 2.2.11 Transformer Architecture
Encoder and Decoder
Encoder and Decoder
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture08-transformers.pdf
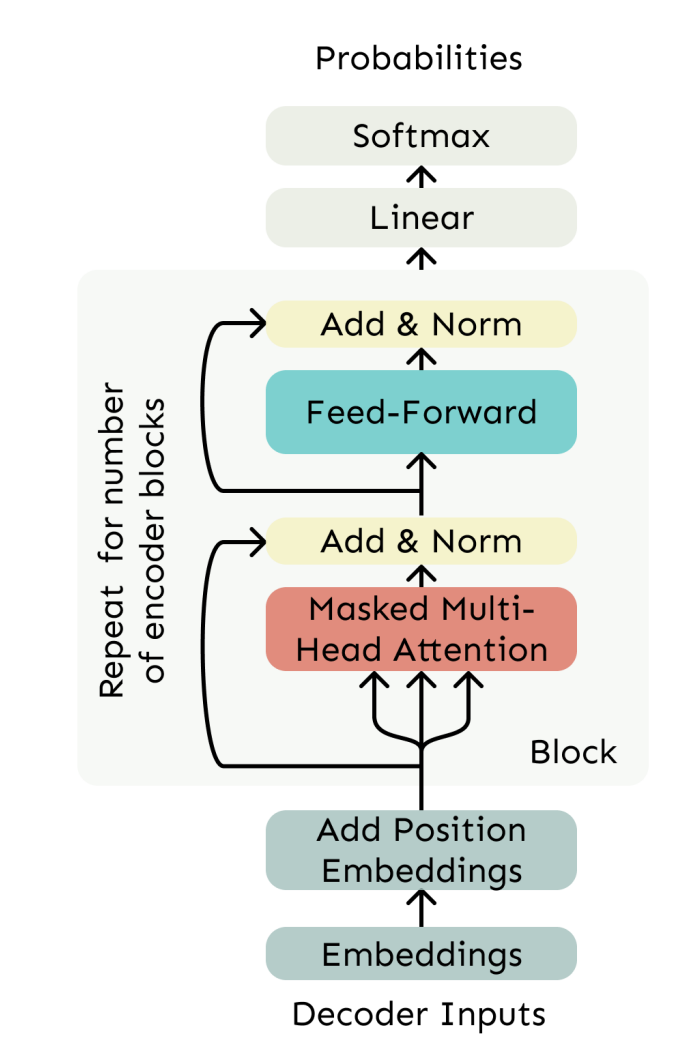
Encoder
Decoder
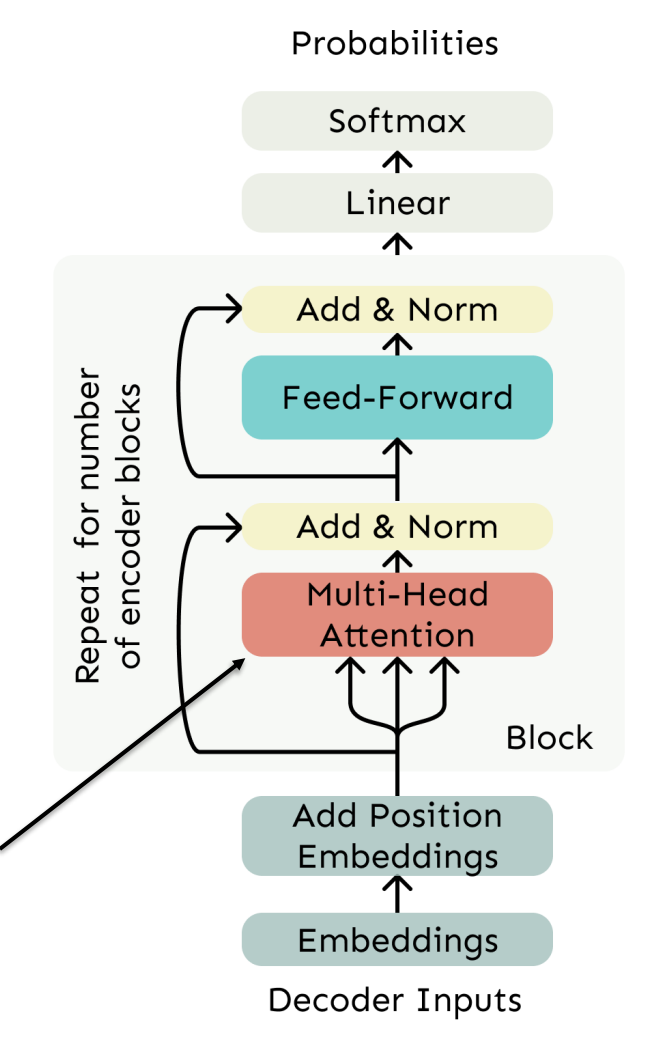
No Masking!
Encoder-Decoder
Encoder-Decoder
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture08-transformers.pdf
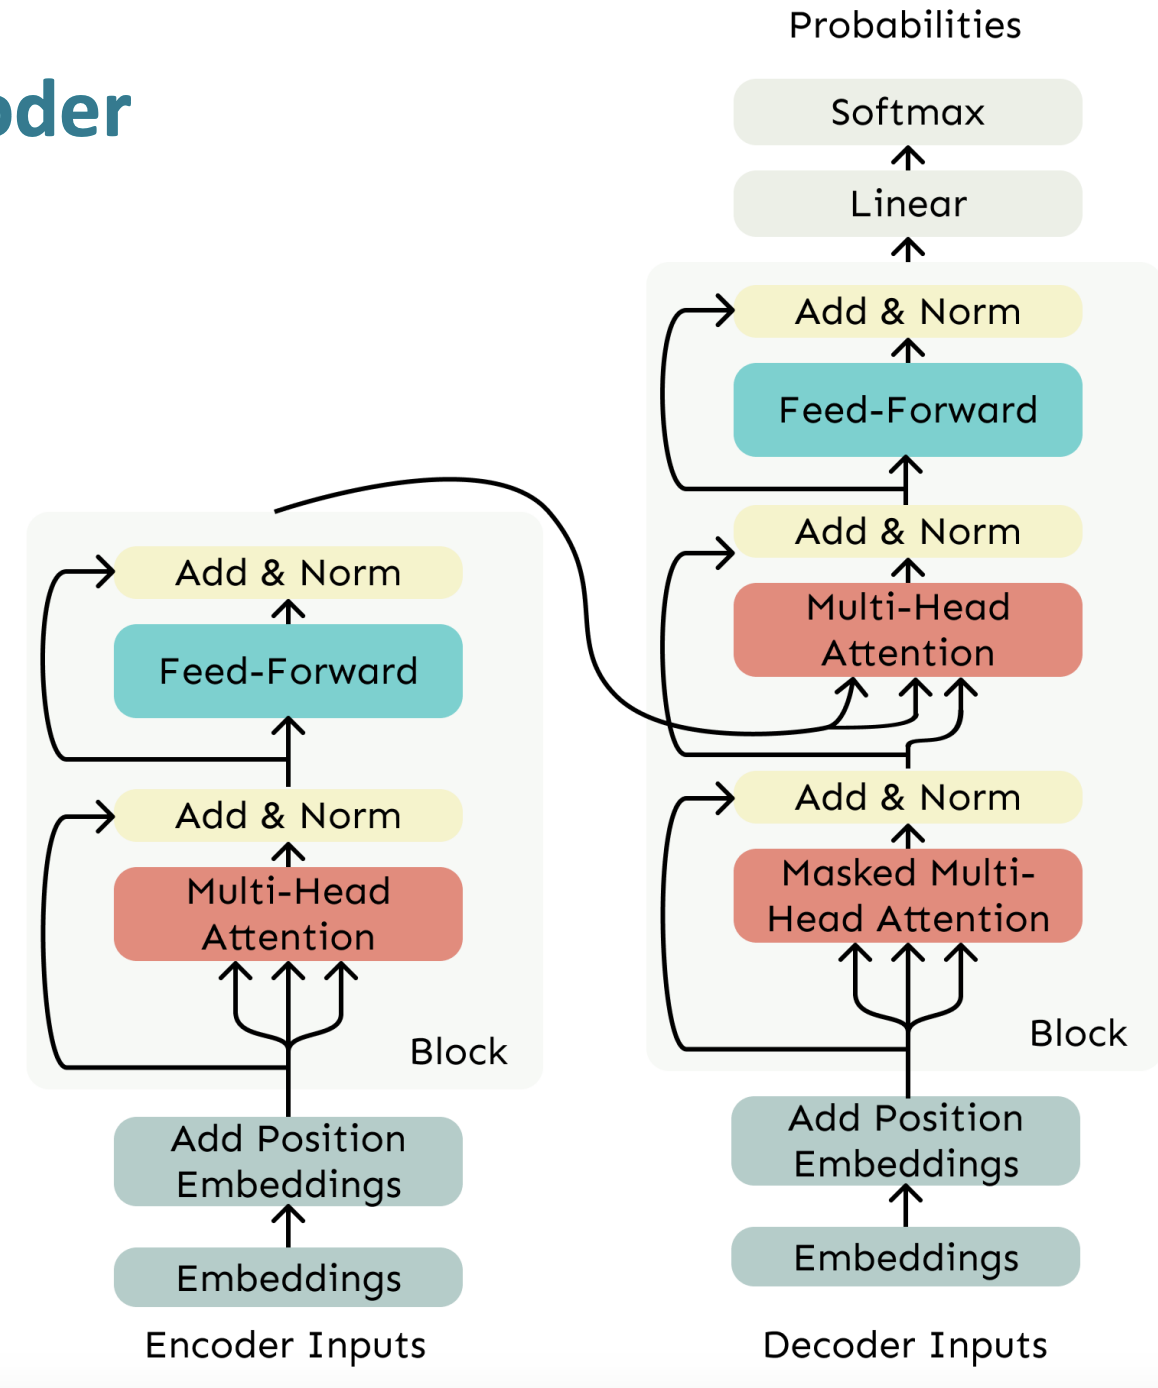
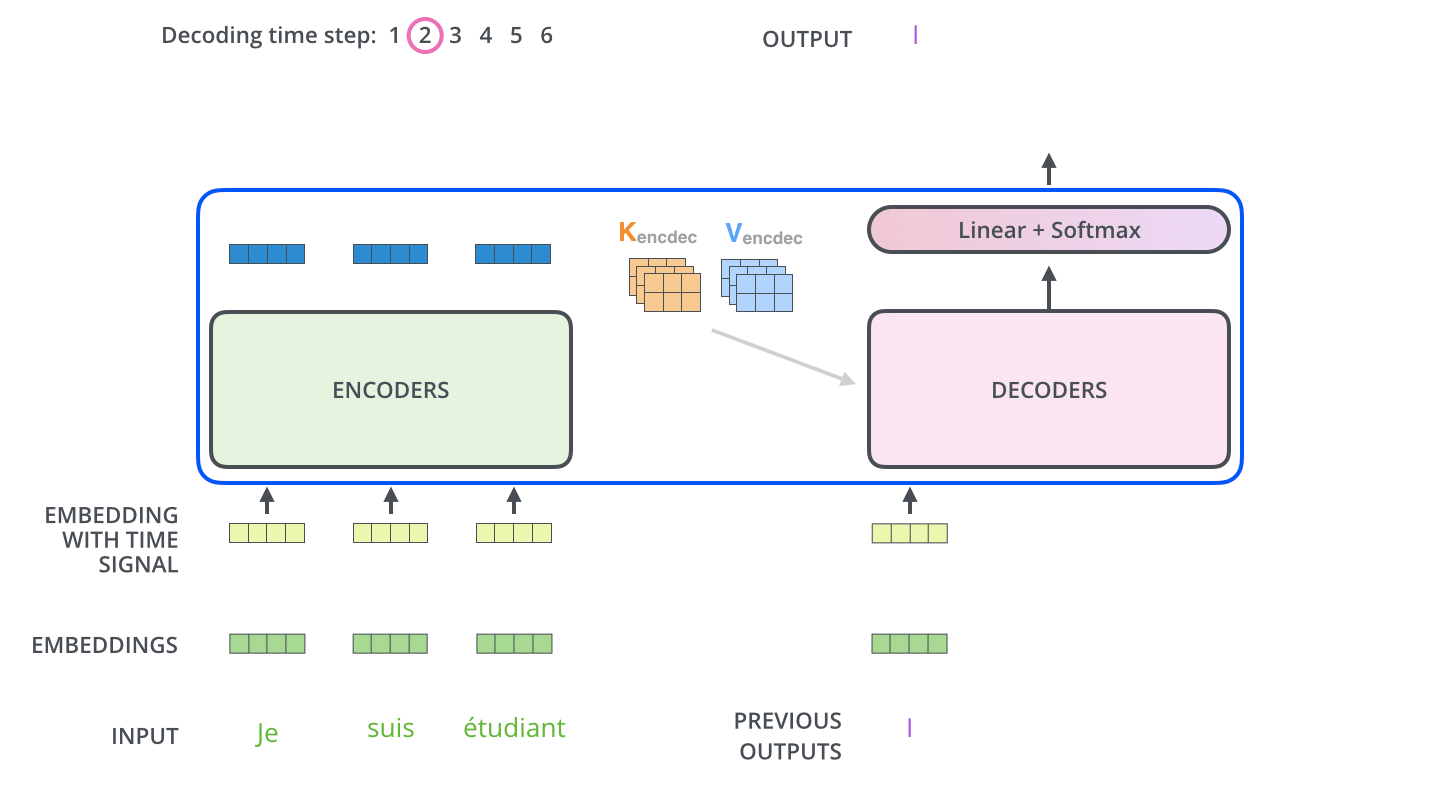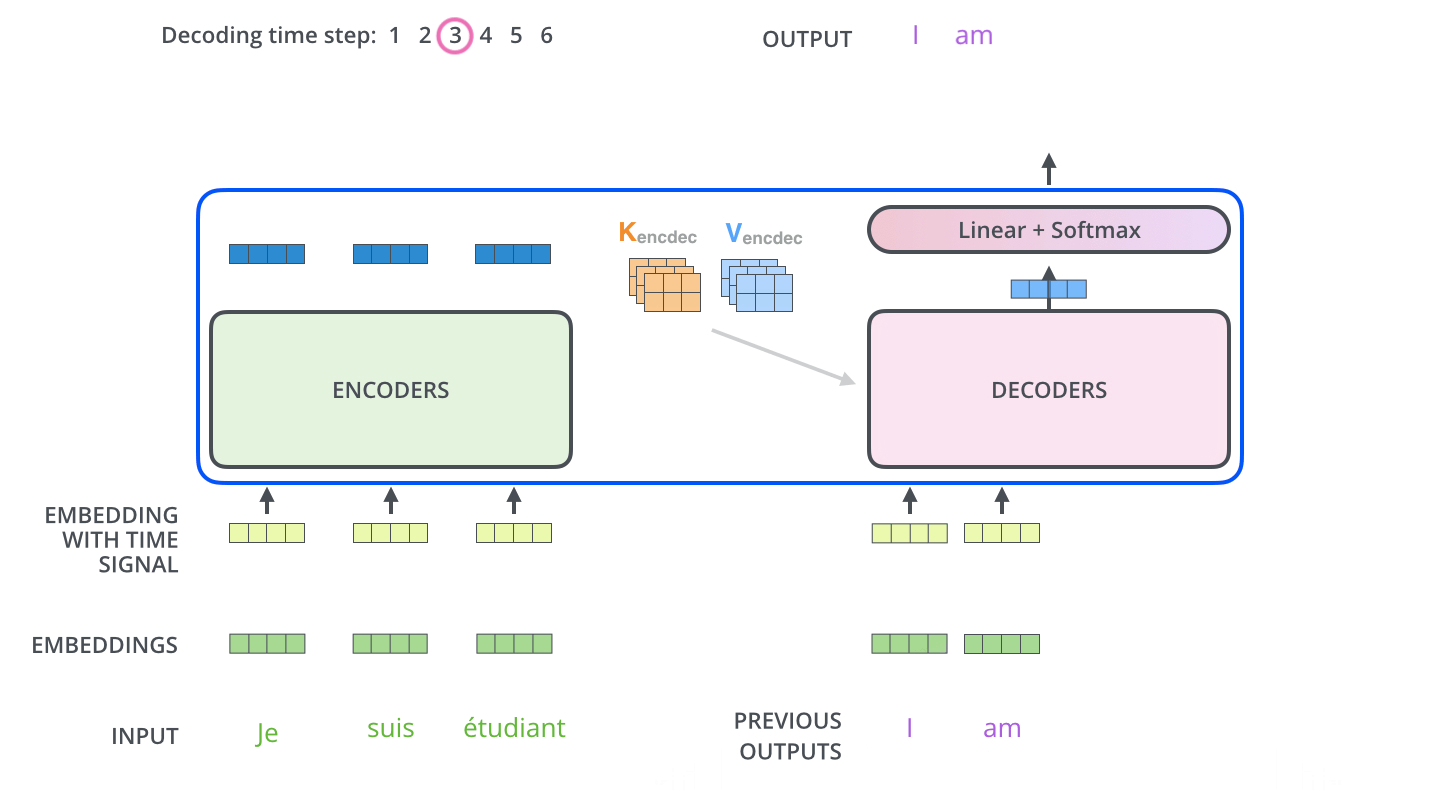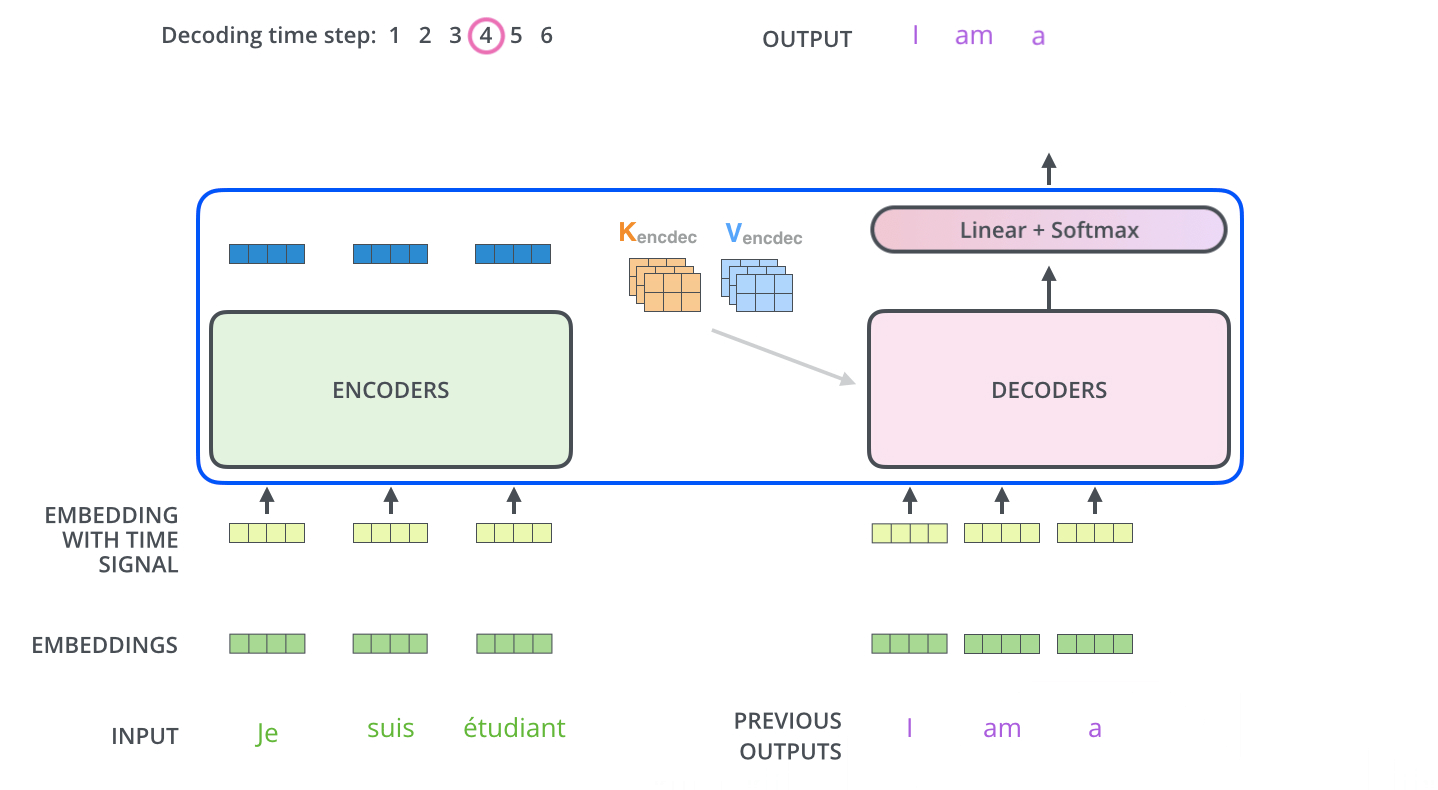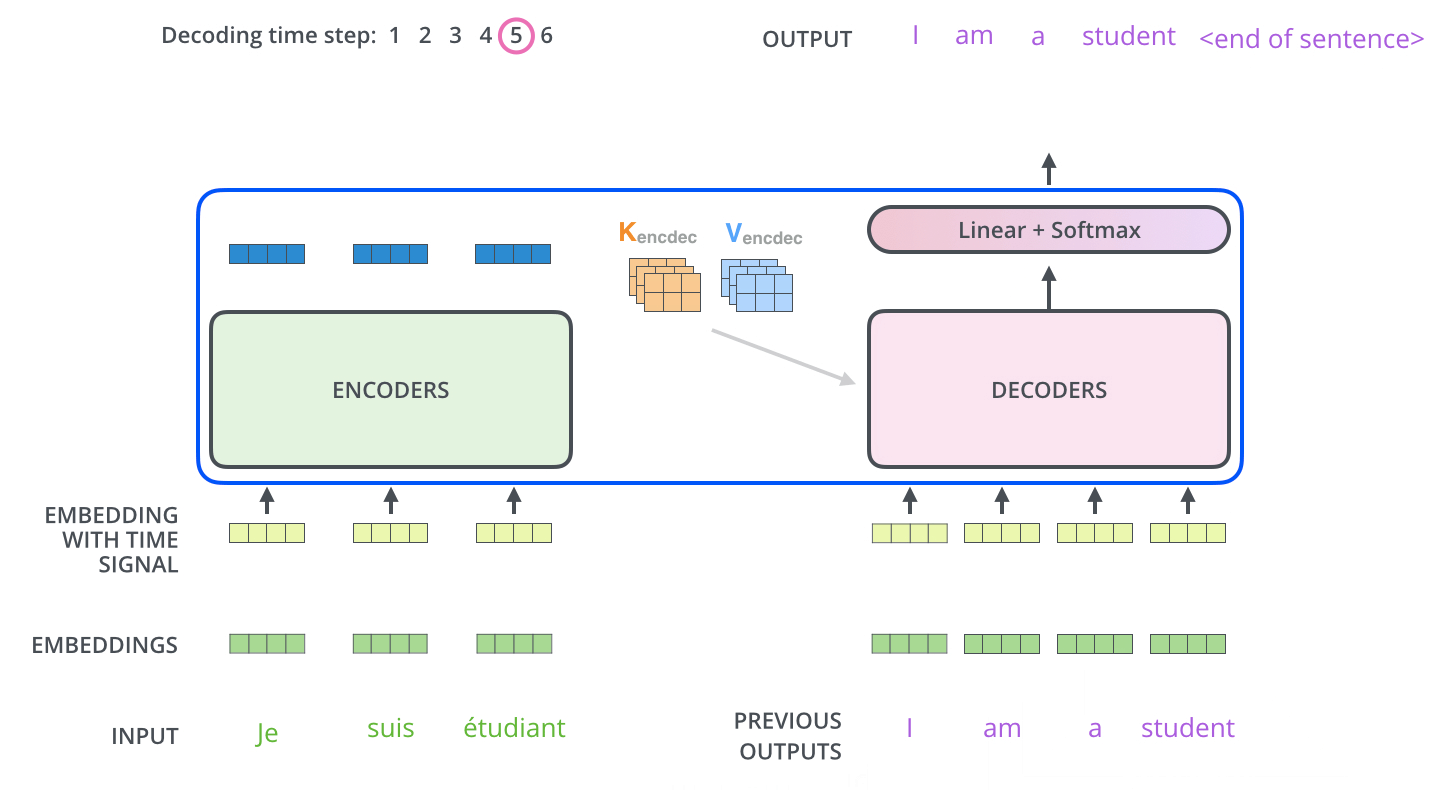
The embedding produced by Decoder should be conditional on the Encoder embedding
The Cross Attention:
Encoder Embedding K, V;
Decoder Embedding Q
Encoder-Decoder Illustration
Encoder-Decoder Illustration
https://jalammar.github.io/illustrated-transformer/
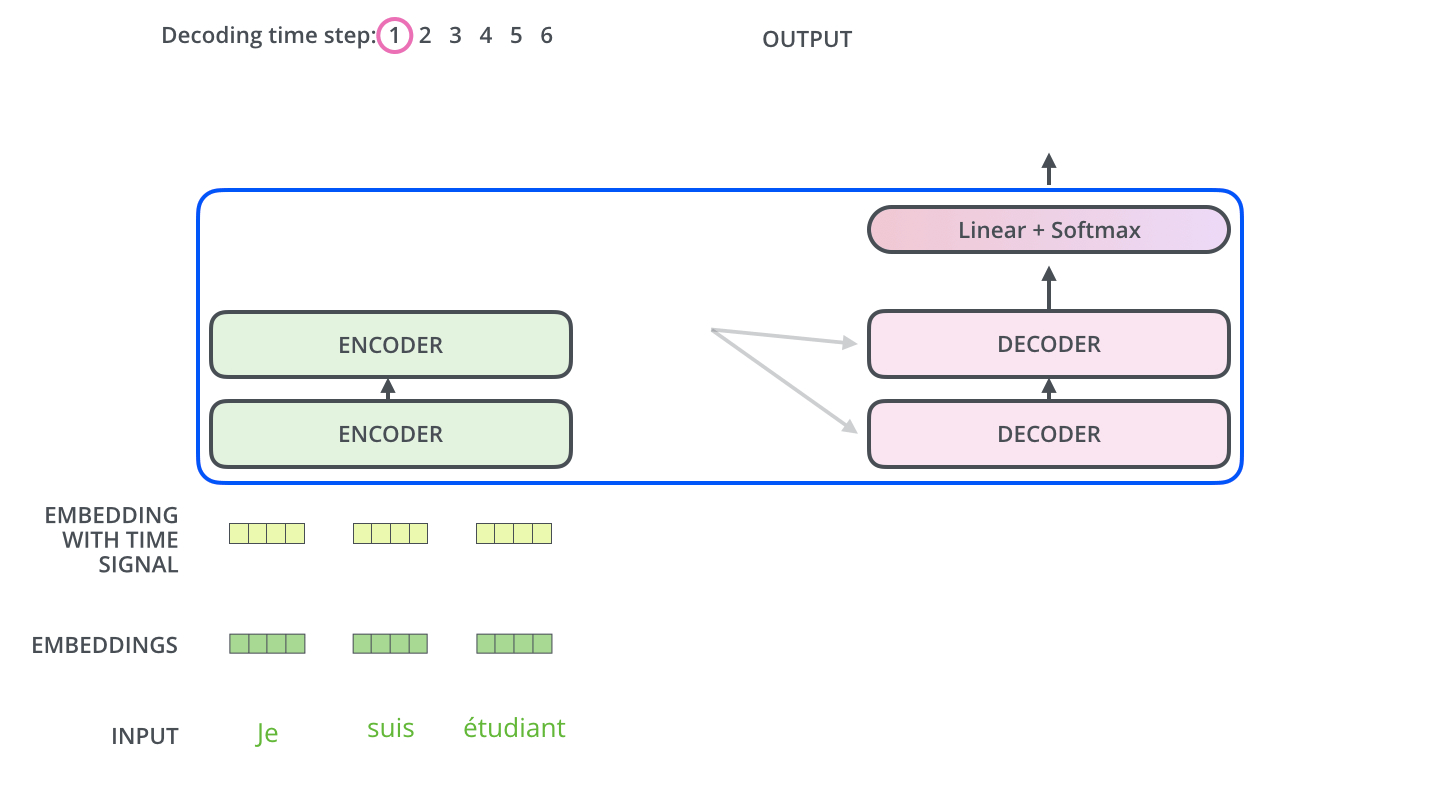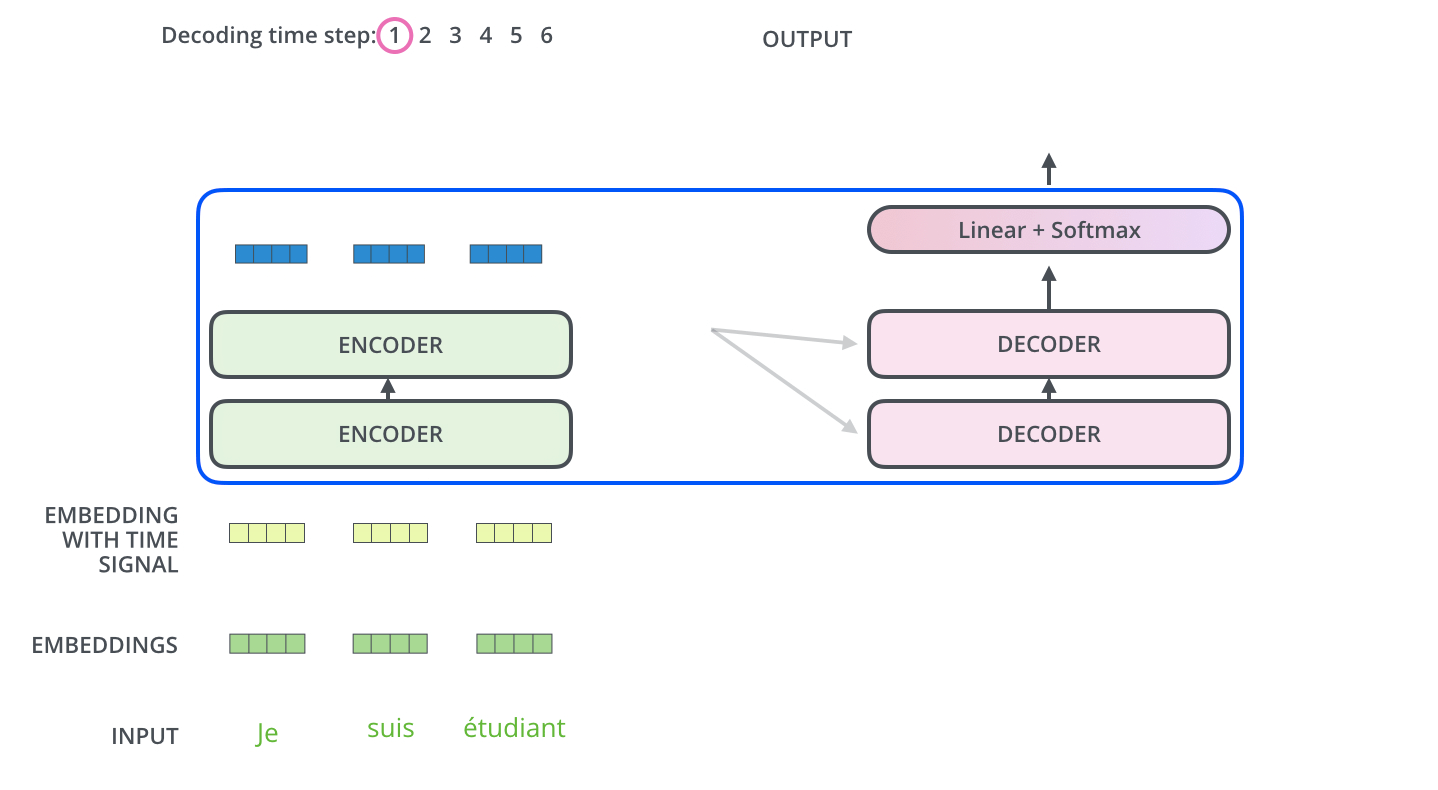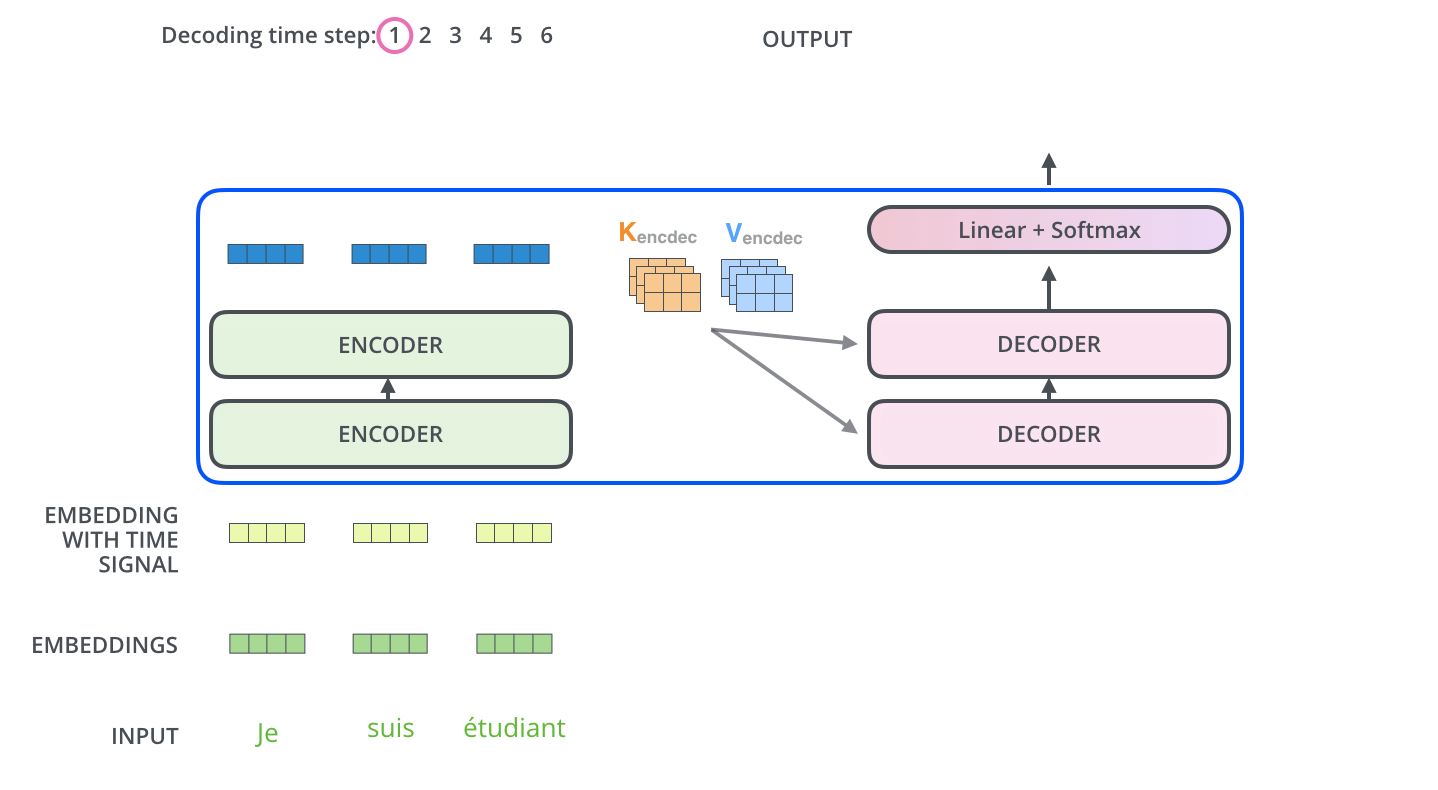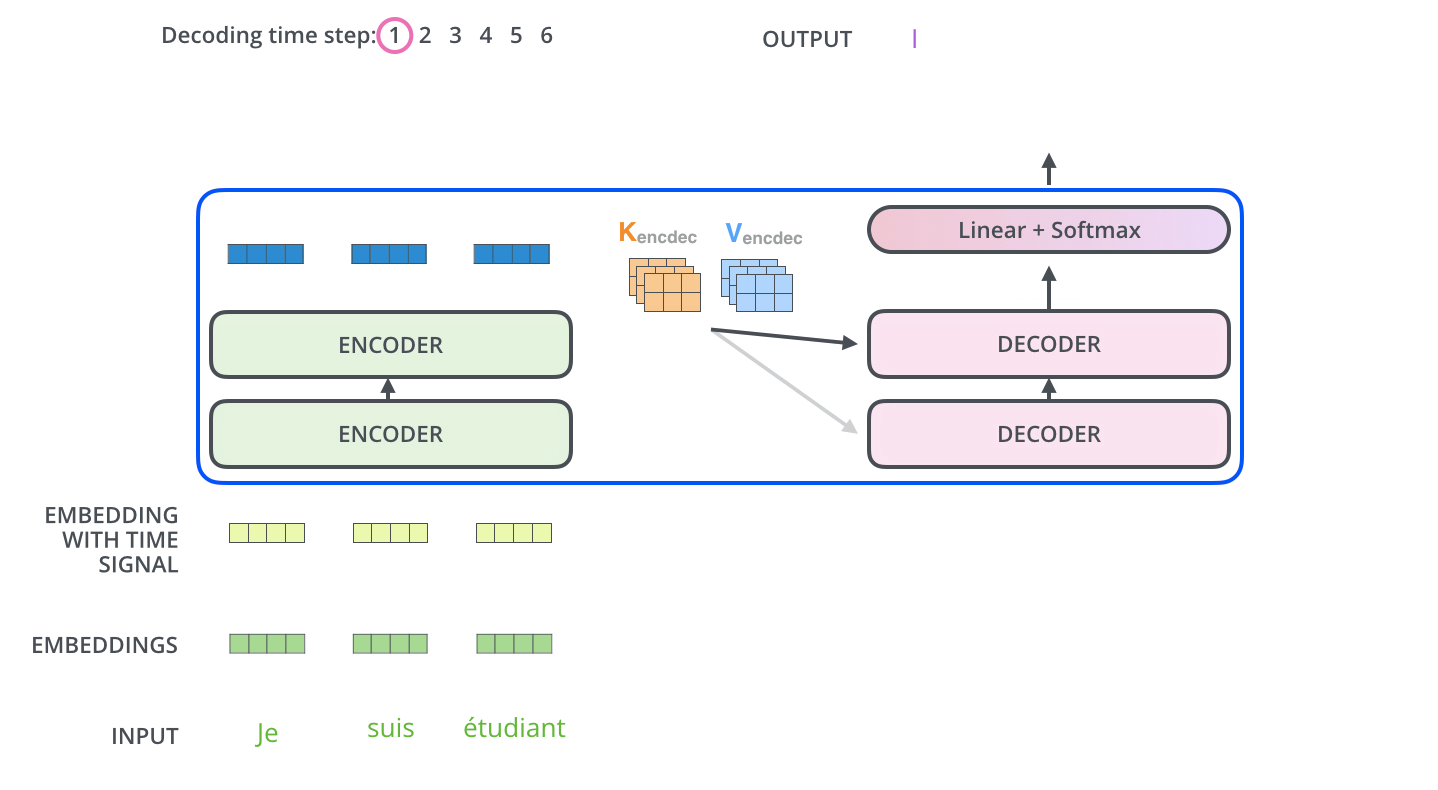
Encoder-Decoder Illustration
Encoder-Decoder Illustration
https://jalammar.github.io/illustrated-transformer/
2.2 Transformer 2.2.12 Position Representations
2.2 Transformer 2.2.12 Position Representations
Sinusoidal Position Representations
Sinusoidal Position Representations
Pros:
Periodicity indicates that maybe “absolute position” isn’t as important
Maybe can extrapolate to longer sequences as periods restart!
Cons:
Not learnable; also the extrapolation doesn’t really work!
Learnable Position Representations
Learnable Position Representations
Let all be learnable parameters! Learn a matrix , and let each be a column of that matrix!
Pros:
Flexibility: each position gets to be learned to fit the data
Cons:
Definitely can’t extrapolate to indices outside 1, … , 𝑛.
Widely used in many system;
From absolute position to relative position:
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture08-transformers.pdf
RoPE –Rotary Position Embedding
RoPE –Rotary Position Embedding
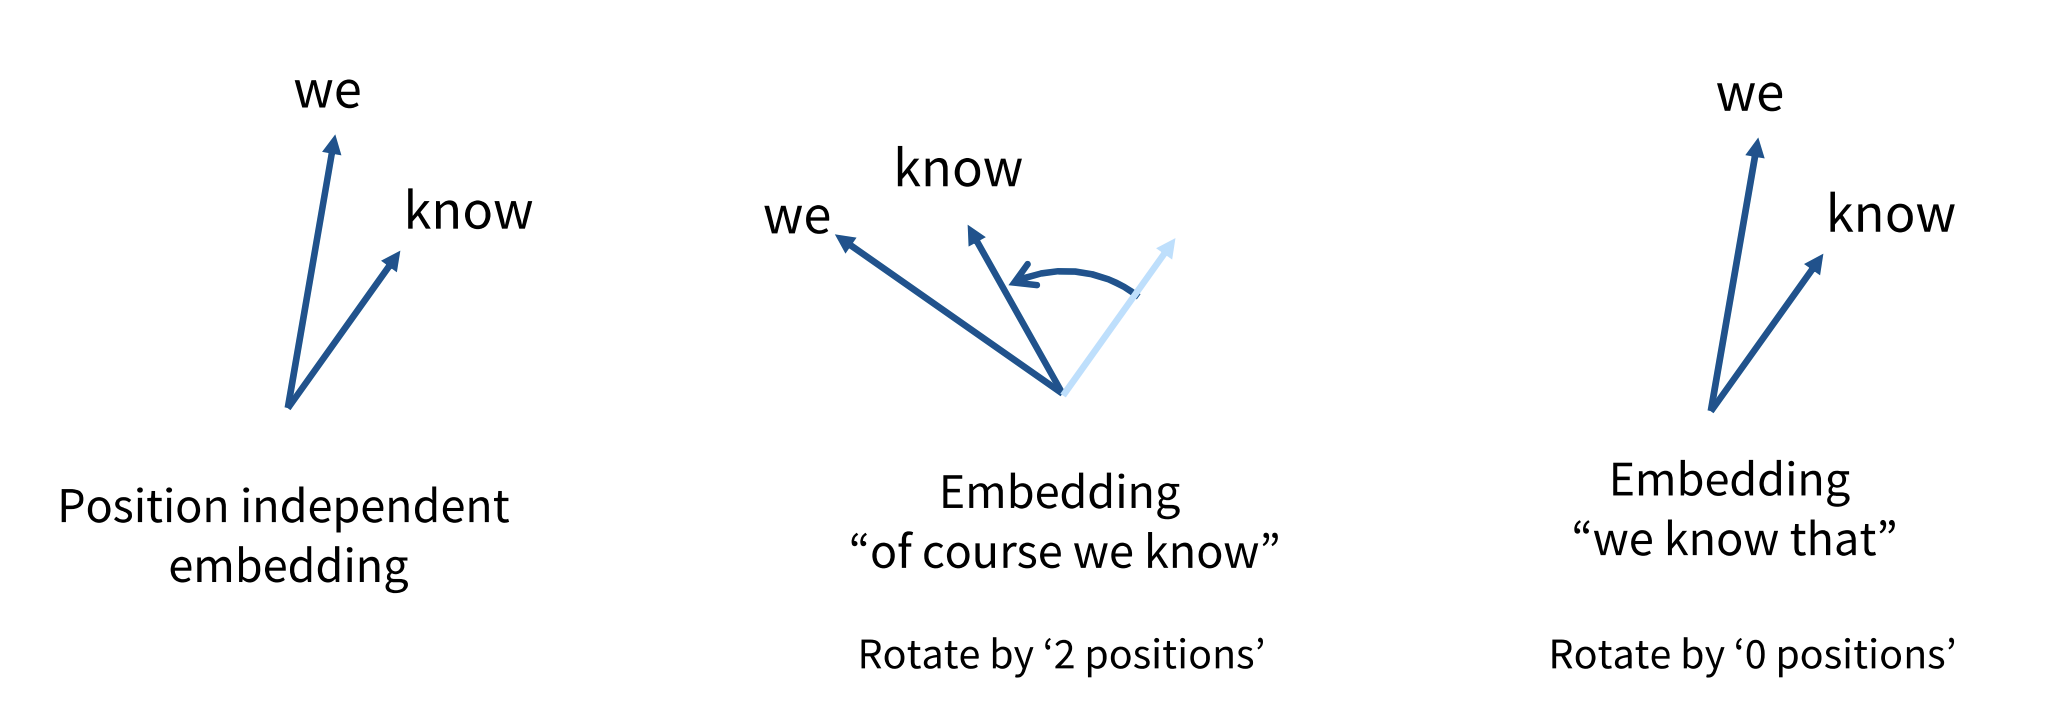
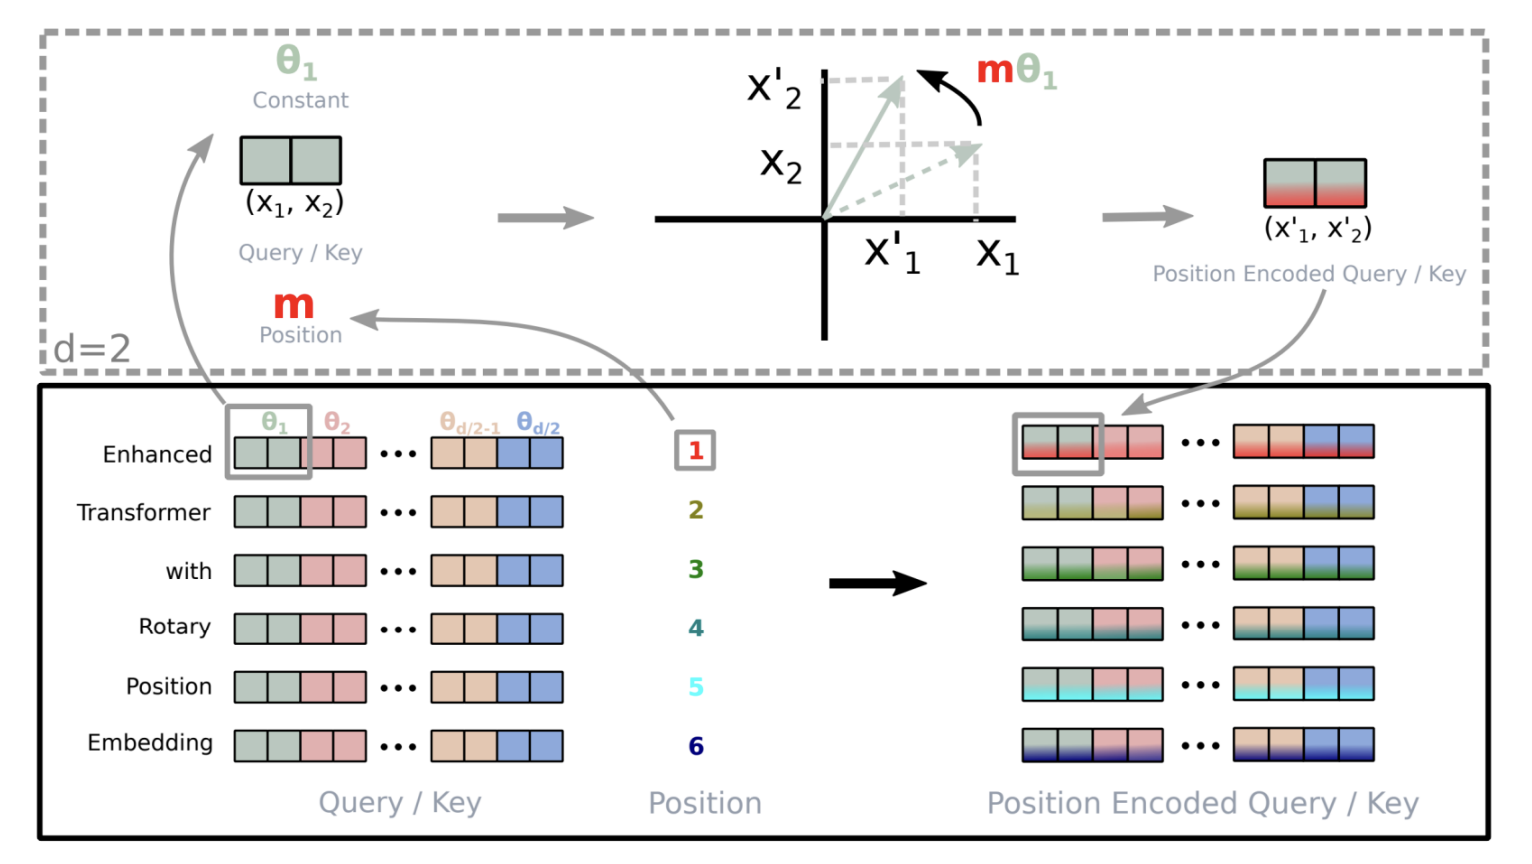
Relative position should be some s.t.
That is, the attention function only gets to depend on the relative position .
Relative position equivariance → Rotation
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture08-transformers.pdf
RoPE in High Dimension
RoPE in High Dimension
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture08-transformers.pdf
2.2 Transformer 2.2.13 Context Length
2.2 Transformer 2.2.13 Context Length
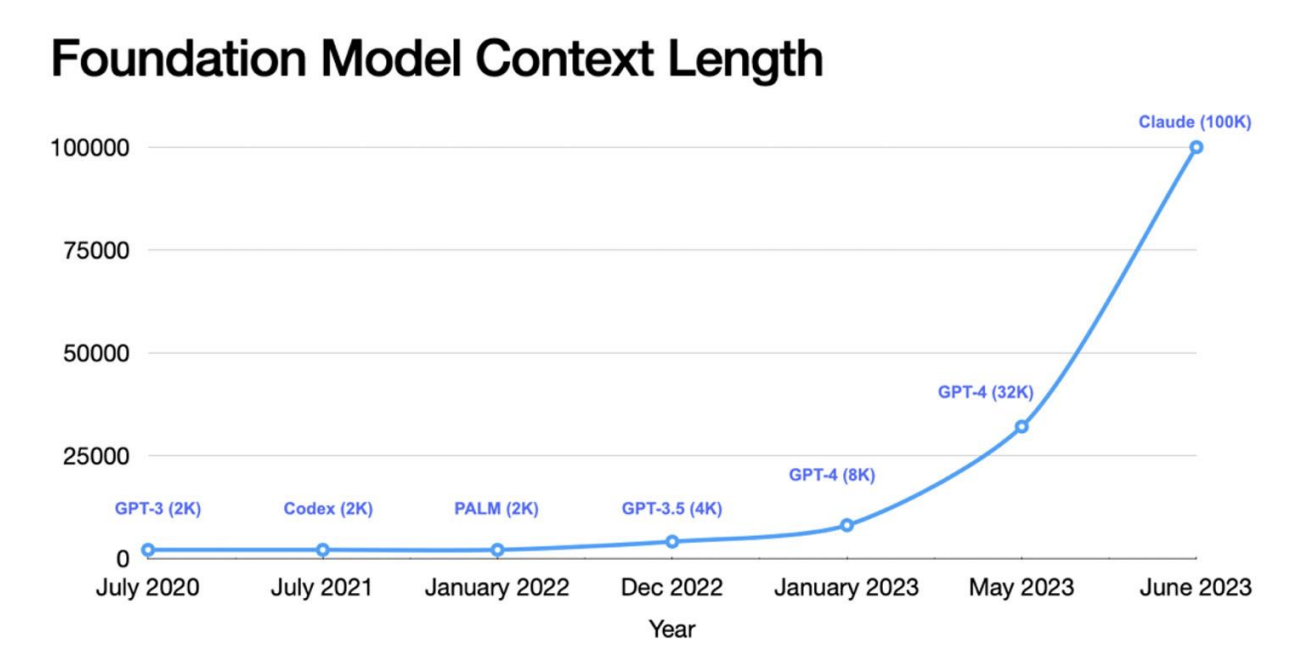
Beyond Fixed-Length Context
Beyond Fixed-Length Context
The matrix computations in Transformer need Fixed-Length Context
Limited context hampers performance on long texts
Key use cases:
Long documents
Conversations
Streaming text
Agents
…
https://web.stanford.edu/class/cs224n/slides_w25/cs224n-2025-lecture08-transformers.pdf
Approaches
Approaches
Why Transformer cannot cope with very long context?
The attention complexity is
Approaches:
Sparse Attention
Linear approximation of Attention: Back of RNN
Sparse Attention
Sparse Attention
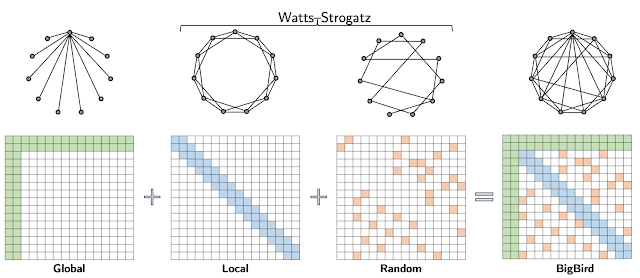
https://research.google/blog/constructing-transformers-for-longer-sequences-with-sparse-attention-methods/
Linear Approximation
Linear Approximation
https://newsletter.maartengrootendorst.com/p/a-visual-guide-to-mamba-and-state
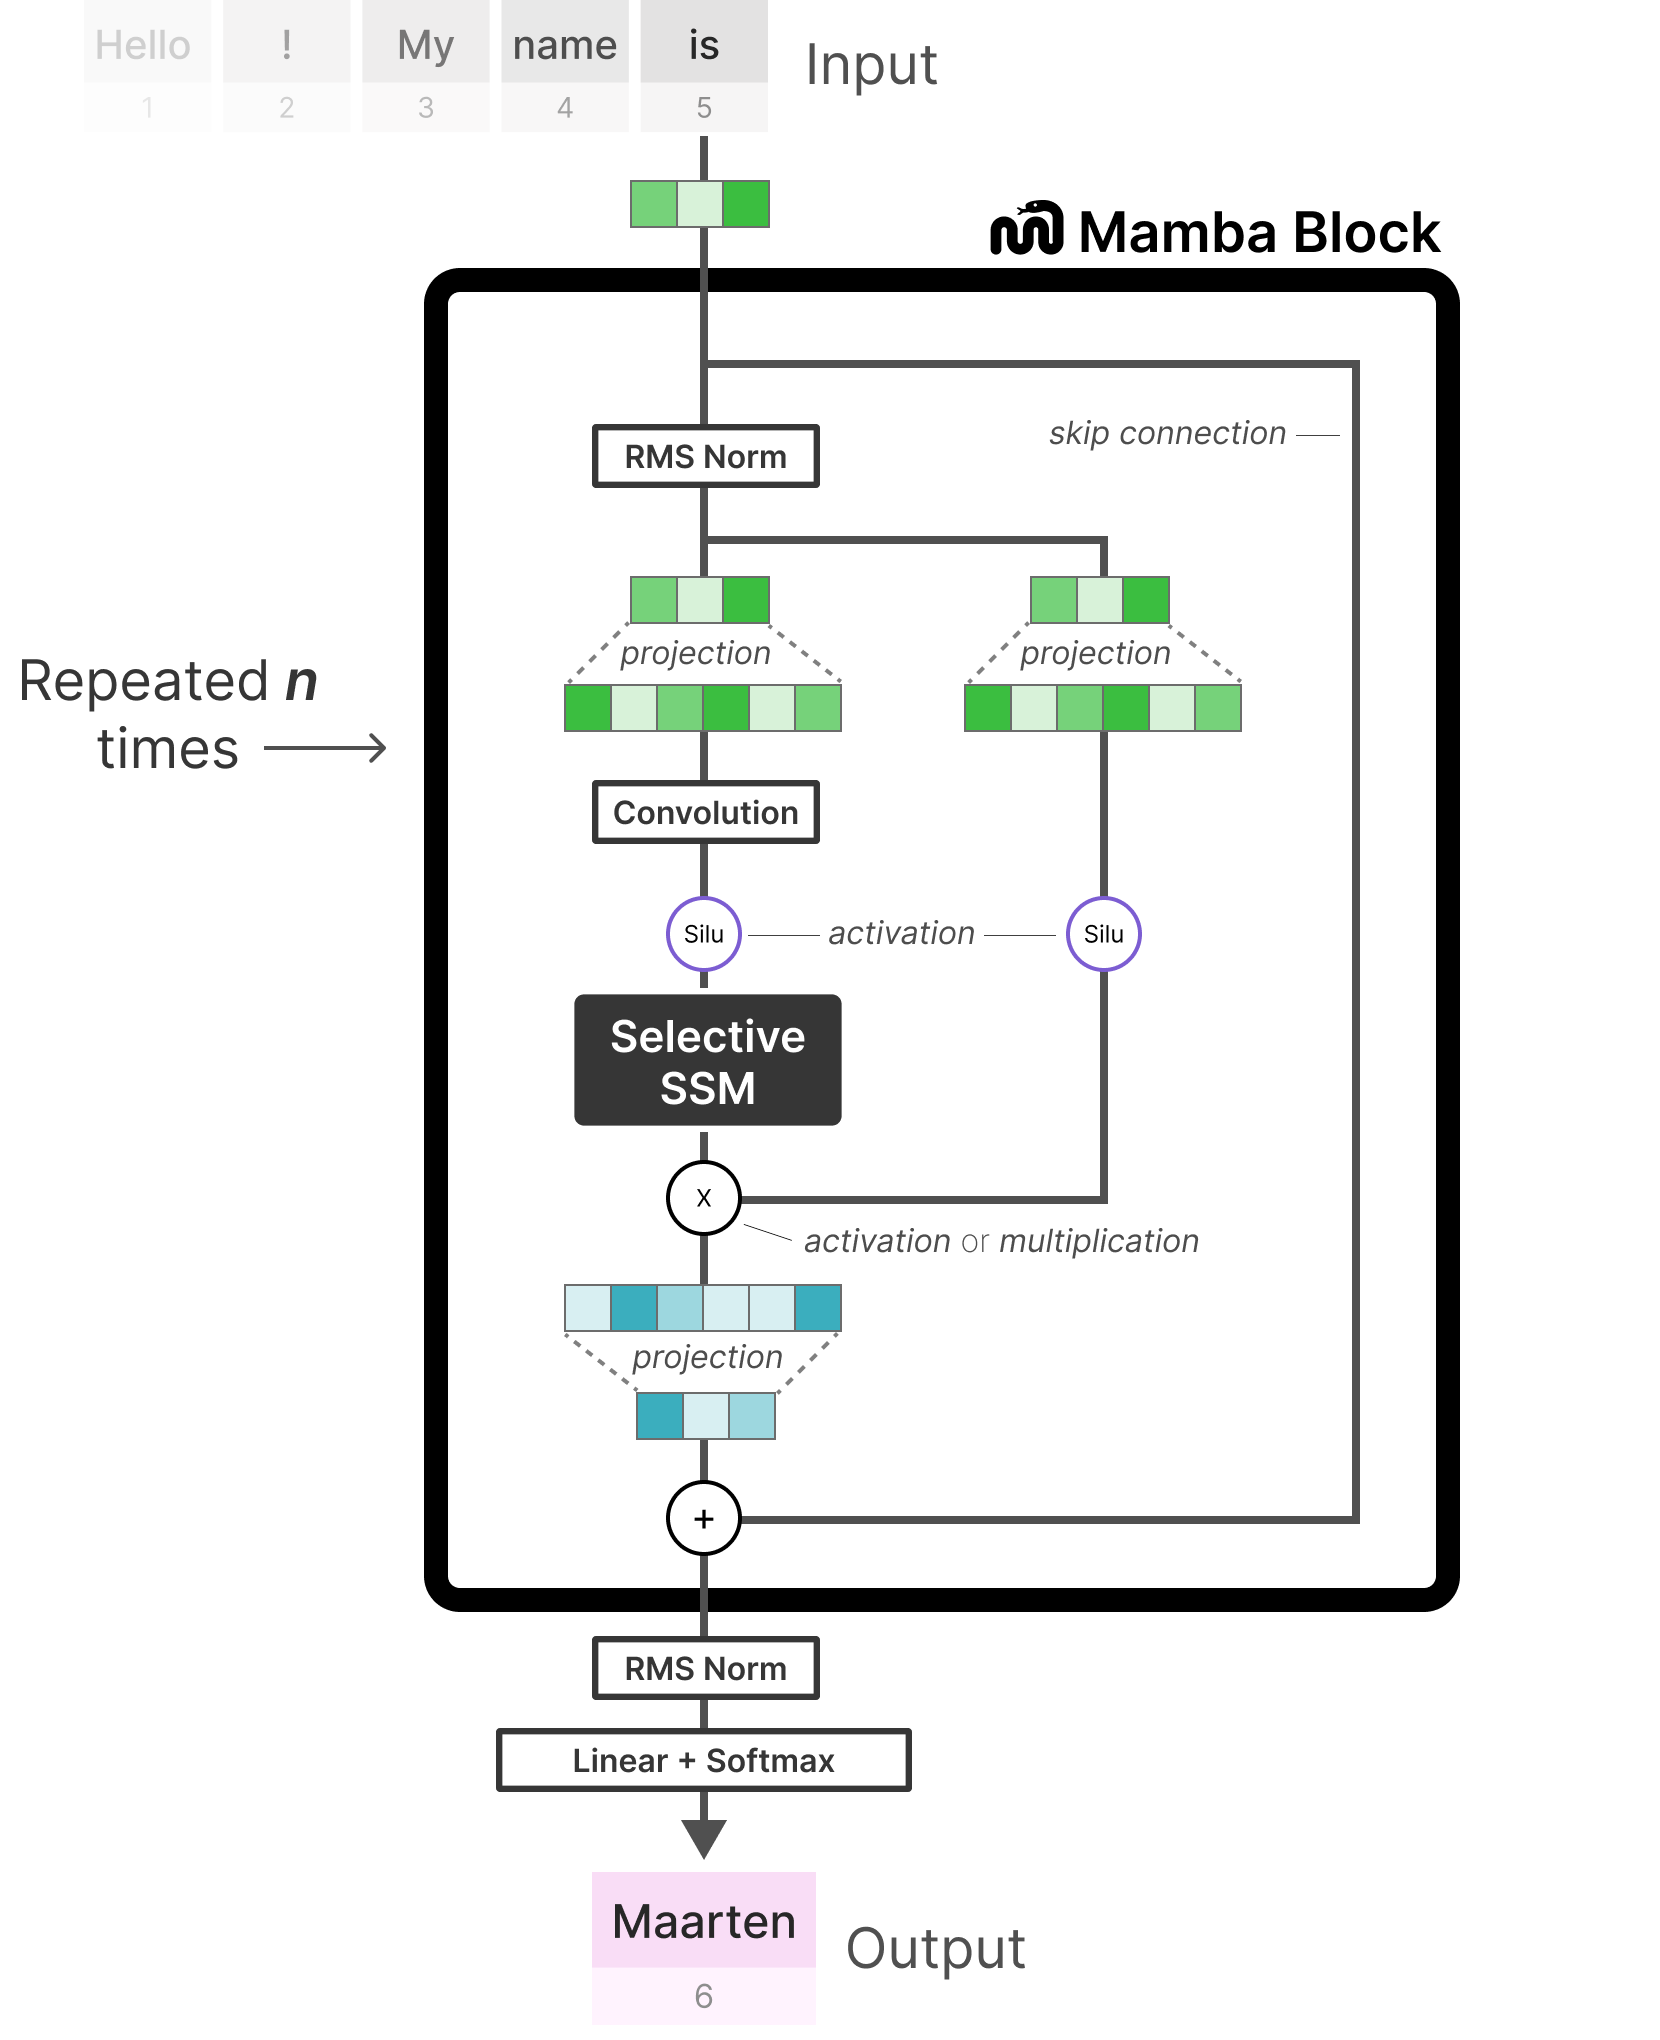
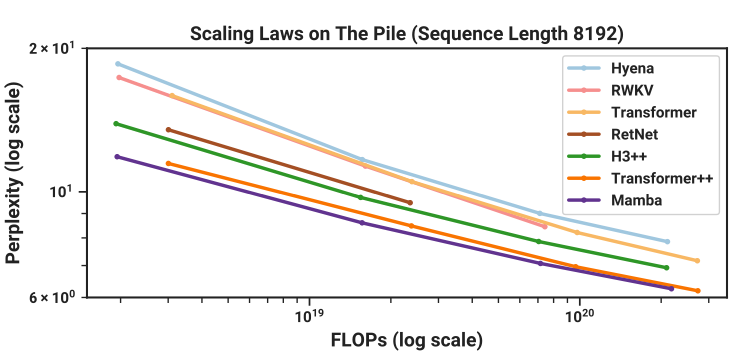
https://thegradient.pub/mamba-explained/
2.2 Transformer 2.2.14 Transferability of Modifications
2.2 Transformer 2.2.14 Transferability of Modifications
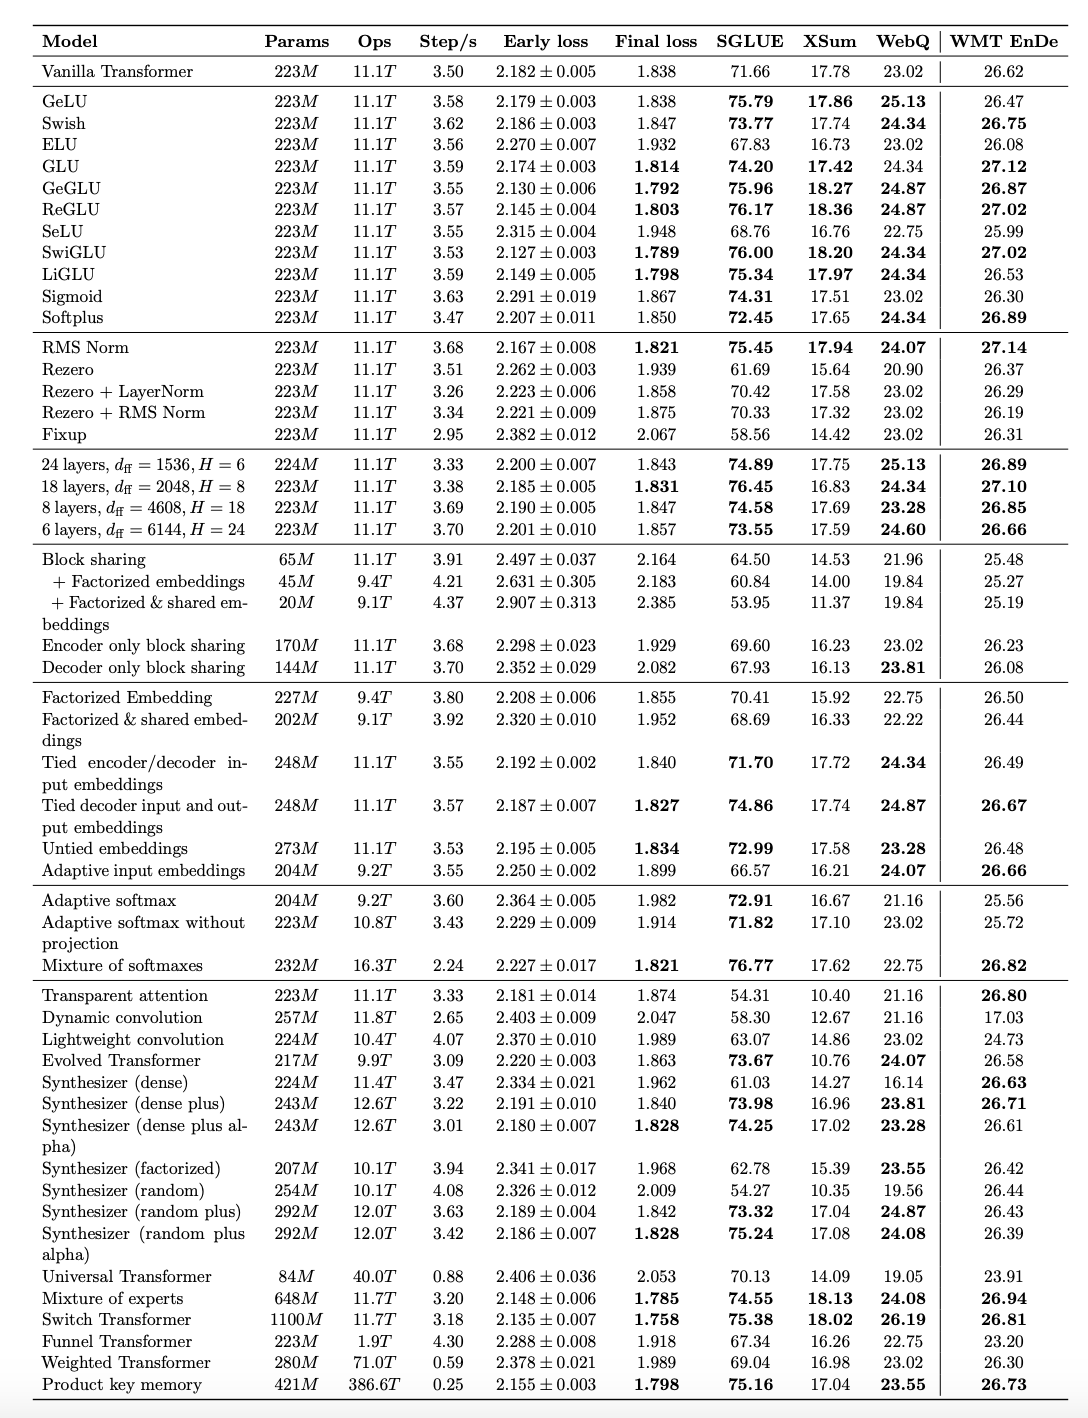
Do Transformer Modifications Transfer?
Do Transformer Modifications Transfer?
"Surprisingly, we find that most modifications do not meaningfully improve performance."
2.2 Transformer 2.2.15 Suggested Readings
2.2 Transformer 2.2.15 Suggested Readings
Papers and Articles
Papers and Articles
A Visual Guide to Mamba and State Space Models https://newsletter.maartengrootendorst.com/p/a-visual-guide-to-mamba-and-state
Any Questions?
Any Questions?